feat(research): OR1 — unify OUTWARD_DISCOVERY+OUTWARD_READING into OUTWARD
One coherent MiMo external-research pass. Discovery and reading remain
visible as subsections inside the artifact, not separate top-level stages.
Artifact has discovery and reading subsections. Event relay streams both.
This commit is contained in:
 Nick committed
1 parent
83ea89c1ba
commit
9d1e0da8e5
21 files changed
+2855
-30
No files matched your search
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://news.ycombinator.com/item?id=31473373","title":"I've yet to see how you can use SQLite for a multi-user multi-write app ...","description":"SQLite doesn't support concurrent writers. In WAL mode it can handle a single writer with concurrent readers. In \"vanilla\" mode, a writer requires exclusive ...","position":1},{"url":"https://sqlite.org/forum/info/b4e8b29ae409cd198652c6b7e70b53b702f269e67e1d2573d627feeba37bbf85","title":"Multiple Writers - SQLite User Forum","description":"# Multiple Writers\n### (1) By [pyarlath](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=pyarlath) on 2025-01-03 08:35:02 [[link]](https://sqlite.org/forum/forumpost/7fb8bf206005d943) [[source]](https://sqlite.org/forum/forumpost/7fb8bf206005d943?raw)\n```\nI am new to this forum, so please be adjusting of me if i ask some noob level questions.\n\nWhy cant sqlite have multiple writers?\n\nMy theoretical understanding is if you open a file in append only mode by 2 process, each process can append data without overwriting each other, now i further understand the support for append is weak in other systems apart from linux or may even differ, but then whats stopping to write a module with shared memory or file or something equivalent to maintain a counter and allocate exclusive space for different writers such that they dont overwrite each other in same file a little like MVCC but instead of version of same data its writing different data from different writers..\n\nI understand there will be more issues internal to sqlite to manage other ds but i feel they can managed with some clever solution, the real limitation should be file cannot accept multiple writer, but they do in an append only mode..\n\nDoes this click some thought?\n```\n\n### (4) By [pyarlath](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=pyarlath) on 2025-01-03 13:14:00 in reply to [2.1](https://sqlite.org/forum/forumpost/6fda11b073) [[link]](https://sqlite.org/forum/forumpost/dcdf209b088e7f93) [[source]](https://sqlite.org/forum/forumpost/dcdf209b088e7f93?raw)\n```\nI may be wrong but as a DB system it should be able to provide multiple writers to a same sqlite file is my recommendation here, if to writers wants to update same at same time fine we should be able to give them that provision with complete data integrity, what meaning that data makes to them is app driven logic..\n\nI am talking here about lockless system like MVCC where updates to same row can be made by just appending to the file at the same time without any locks. So i think there is no illusion here its a well known practice in DB world... i feel\n```\n\n### (5) By [pyarlath](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=pyarlath) on 2025-01-03 13:16:22 in reply to [3](https://sqlite.org/forum/forumpost/c36f1f8f03) [[link]](https://sqlite.org/forum/forumpost/b85a03da3c87e6ea) [[source]](https://sqlite.org/forum/forumpost/b85a03da3c87e6ea?raw)\n```\nNot sure why you thought of performance is what i am after, i am not my request was just like multiple process can read the same DB file, i wanted to understand what is the challenge to provide multiple writer? specially when systems like append-only data structures exists..\n```\n\n### (12) By [pyarlath](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=pyarlath) on 2025-01-03 19:07:57 in reply to [11](https://sqlite.org/forum/forumpost/b4e8b29ae4) [[link]](https://sqlite.org/forum/forumpost/85cde6083d4c6102) [[source]](https://sqlite.org/forum/forumpost/85cde6083d4c6102?raw)\n```\nI never said I understand sqlite, infact I am noob like i said in the original first post.. but am a big fan of the embedded database strategy..\n\nTransactions in append only file formats are durable and also have order the append order..\n\nI am not asking for a coordinator process but all we need is to do is coordinate of the underlying file size and keep appending ie adding to it as a shared counter..\n\nI completely understand file format compatibility is number 1 priority, but we can always achieve the said by having extra file just like Wal which will be home for multiple writers and possible move data to sqlite format on periodic time..\n\nAgain my interest is in suggesting this concept of achieving multiple writer but the community can tell me if this a feasible idea..\n```\n\n### (15) By [pyarlath](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=pyarlath) on 2025-01-04 11:24:41 in reply to [13](https://sqlite.org/forum/forumpost/388af122d9) [[link]](https://sqlite.org/forum/forumpost/f39edda8db7d11a5) [[source]](https://sqlite.org/forum/forumpost/f39edda8db7d11a5?raw)\n```\nThat's called snapshot, Each transaction starts with a snapshot[simply say file size here] so when final commit happens transaction just compares the snapshot[file size] if no data is mutated it remains same else it's changes and we can throw serialization error for the transaction..\n\nAgain all this is common practice in PG and other ACID comLine truncated
|
||||
@@ -0,0 +1,53 @@
|
||||
# Research Stage: OUTWARD
|
||||
|
||||
## Process capsule
|
||||
- Issue: {{ISSUE_NUMBER}}
|
||||
- Round: {{ROUND}}
|
||||
- Stage: OUTWARD (of 7)
|
||||
- Prior artifacts: {{PRIOR_ARTIFACTS}}
|
||||
- Blocking unknowns: {{BLOCKING_UNKNOWNS}}
|
||||
|
||||
## Your task
|
||||
Find and read enough reliable external evidence to answer the external research questions.
|
||||
|
||||
## You MUST
|
||||
|
||||
DISCOVERY:
|
||||
- Issue real searches (webfetch of search engines, documentation sites)
|
||||
- Preserve query/tool receipts
|
||||
- Identify candidate sources with stable IDs (O1, O2, ...)
|
||||
- Classify each source (official docs, GitHub, academic, blog)
|
||||
- Select a bounded relevant set for reading
|
||||
|
||||
READING:
|
||||
- Actually fetch/read the selected sources
|
||||
- Extract evidence claims relevant to the subquestions
|
||||
- Record limitations and contradictions
|
||||
- Preserve source IDs and fetch/read receipts
|
||||
|
||||
## You MUST NOT
|
||||
- Inspect unrelated Rune code
|
||||
- Design the Rune solution
|
||||
- Perform INNOVATION (that's the next stage)
|
||||
- Perform SYNTHESIS
|
||||
- Modify production code
|
||||
- Continue searching after the evidence requirement is satisfied
|
||||
- Treat search snippets as evidence (actually read the pages)
|
||||
|
||||
## STOP CONDITION
|
||||
Stop when each required external subquestion has:
|
||||
- Adequate evidence, OR
|
||||
- Explicit contradictory evidence, OR
|
||||
- A named unresolved gap
|
||||
|
||||
## Output
|
||||
Produce your stage artifact as structured text with:
|
||||
- DISCOVERY: queries issued, sources discovered with URLs
|
||||
- READING: sources actually read, evidence extracted
|
||||
- LIMITATIONS: what the sources don't cover
|
||||
- CONTRADICTIONS: where sources disagree
|
||||
|
||||
End with:
|
||||
```
|
||||
StageCompleted: OUTWARD
|
||||
```
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://sqlite.org/forum/info/6ed6824176b9c773","title":"What does, if many threads and/or processes need to write ... - SQLite","description":"# What does, if many threads and/or processes need to write the database at the same instant, mean?\n### (2) By [ThanksRyan](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=ThanksRyan) on 2021-04-10 23:13:09 in reply to [1](https://sqlite.org/forum/forumpost/7b7ea1373c) [[source]](https://sqlite.org/forum/forumpost/6ed6824176b9c773?raw)\nSQLite only supports one writer at a time per database file.\n\n### (4) By iio7 ( [iio7iio7](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=iio7iio7)) on 2021-04-11 11:50:53 in reply to [1](https://sqlite.org/forum/forumpost/7b7ea1373c) [[link]](https://sqlite.org/forum/forumpost/e1903d54f15133ac) [[source]](https://sqlite.org/forum/forumpost/e1903d54f15133ac?raw)\n```\nPRAGMA journal_mode = WAL;\nPRAGMA temp_store = MEMORY;\nPRAGMA synchronous = NORMAL;\nPRAGMA cache_size = -64000;\n```","position":1},{"url":"https://news.ycombinator.com/item?id=31473373","title":"I've yet to see how you can use SQLite for a multi-user multi-write app ...","description":"SQLite uses a queue (in WAL mode) in order to handle concurrent writes. In WAL mode it can handle a single writer with concurrent readers. A single thread; no ...","position":2},{"url":"https://www.reddit.com/r/learnprogramming/comments/1l82ohn/confused_about_sqlite_and_concurrency/","title":"Confused about SQLite and concurrency : r/learnprogramming","description":"So sqlite, with WAL enabled, supports multiple readers at the same time, and supports reading and writing at the same time. The only thing it ...Question regarding multiple readers and writers : r/sqlite - RedditConcurrency when writing data into SQLite? : r/golang - RedditMore results from www.reddit.com","position":3},{"url":"https://www.bugsink.com/blog/database-transactions/","title":"Single-writer Database Architecture with SQLite - Bugsink","description":"SQLite allows only one writer at a time. Even in WAL mode, concurrent write transactions are not possible – any attempt to write while another ...","position":4},{"url":"https://stackoverflow.com/questions/9264772/sqlite-alternative-with-concurrent-writing-delphi","title":"SQLite alternative with concurrent writing (Delphi) - Stack Overflow","description":"You may consider using FireBird which has a more complex (and tuned) architecture for client-server. SQLite3 default writing method is expected ...SQLite Concurrent AccessSqlite WAL blocks despite doc sais it doesn'tMore results from stackoverflow.com","position":5},{"url":"https://oldmoe.blog/2024/07/08/the-write-stuff-concurrent-write-transactions-in-sqlite/","title":"The Write Stuff: Concurrent Write Transactions in SQLite","description":"SQLite, using the Write-Ahead-Log (WAL) journaling mode, supports an unlimited number of readers and a single writer any given moment.","position":6}]},"id":"01a08314-06fc-706f-becc-a9e4f0c2b9f2","creditsUsed":2}
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://berthub.eu/articles/posts/a-brief-post-on-sqlite3-database-locked-despite-timeout/","title":"What to do about SQLITE_BUSY errors despite setting a timeout","description":"# SQLite transactions\nYou can also force this decision with BEGIN IMMEDIATE, which always starts a write transaction.\n\n```sql\npragma journal_mode=\"wal\"; -- only have to do this once\ncreate table t (v INT) strict;\n.timeout 10000 -- 10 seconds\n```\n\nIf we leave the transaction on the left open for too long, the right side will get a SQLITE_BUSY error:\n\n# Getting into trouble\nAs noted, if you BEGIN a transaction in SQLite without specifying ‘immediate’, SQLite actually only begins a transaction after you submit the first statement, and it will pick the _kind_ of transaction based on that first statement (read-only or read-write).\n\nNo matter how high you set your .timeout, this scenario always delivers an instant SQLITE_BUSY error.","position":1},{"url":"https://lobste.rs/s/yapvon/what_do_about_sqlite_busy_errors_despite","title":"What to do about SQLITE_BUSY errors despite setting a timeout","description":"TLDR: if you're seeing SQLITE_BUSY errors, try using BEGIN IMMEDIATE for transactions that you know are going to be a write. It turns out I've ...","position":2},{"url":"https://news.ycombinator.com/item?id=45781519","title":"In SQLite, transactions by default start in “deferred” mode. This means ...","description":"The fix is to set a busy_timeout and to begin any transaction ... Note that busy_timeout is not applicable to SQLite in this case (the SQLITE_BUSY issued ...","position":3},{"url":"https://sqlite.org/forum/forumpost/04ed1d235b","title":"Help understanding the effect of BEGIN IMMEDIATE - SQLite","description":"# Help understanding the effect of BEGIN IMMEDIATE\n### (1) By Simon Willison ( [simonw](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=simonw)) on 2024-06-21 22:17:11 [[link]](https://sqlite.org/forum/forumpost/119e937367a6a50c) [[source]](https://sqlite.org/forum/forumpost/119e937367a6a50c?raw)\nThe problem is that by upgrading a transaction after it has started, SQLite will immediately return a SQLITE_BUSY error without respecting the busy_timeout previously mentioned, if the database is already locked by another connection.\n\n### (2) By Nuno Cruces ( [ncruces](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=ncruces)) on 2024-06-21 22:55:18 in reply to [1](https://sqlite.org/forum/forumpost/119e937367) [[link]](https://sqlite.org/forum/forumpost/650a97c05c9caacd) [[source]](https://sqlite.org/forum/forumpost/650a97c05c9caacd?raw)\nIt immediately gets a `SQLITE_BUSY` error and the connection B succeeds.\n\n### (7) By Ziad ( [ziadkh0](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=ziadkh0)) on 2025-09-10 16:05:00 in reply to [1](https://sqlite.org/forum/forumpost/119e937367) [[link]](https://sqlite.org/forum/forumpost/10686f6a4024e2f2) [[source]](https://sqlite.org/forum/forumpost/10686f6a4024e2f2?raw)\n```\nStep | Terminal A: | Terminal B:\n-----|--------------------------------------|--------------------------\n 1 | $ sqlite3 immediate.db |\n 2 | sqlite> PRAGMA busy_timeout=5000; |\n 3 | sqlite> BEGIN; |\n 4 | sqlite> SELECT * FROM sqlite_master; |\n 5 | | $ sqlite3 immediate.db\n 6 | | sqlite> BEGIN IMMEDIATE;\n 7 | sqlite> CREATE TABLE test(id int); |\n```\n\nIn terminal A you will get `Runtime error: database is locked (5)` error immediately (not respecting the `busy_timeout` of 5 seconds).","position":4},{"url":"https://sqlite-users.sqlite.narkive.com/66NfRrlL/implementing-busy-waiting-on-sqlite","title":"Implementing busy-waiting on SQLite","description":"If the transaction contains a command that will change the database (eg delete, update or insert), then use \"begin immediate\" to start the transaction, so that ...[sqlite] sqlite3_busy_timeout not avoiding \"database is locked\" errors ...[sqlite] busy_timeout() not working always?More results from sqlite-users.sqlite.narkive.com","position":5},{"url":"https://simonwillison.net/tags/sqlite-busy/","title":"Simon Willison on sqlite-busy","description":"The fix is to use BEGIN IMMEDIATE if you know your transaction is going to make a write. Bert provides the clearest explanation I've seen yet of ...","position":6}]},"id":"01a08313-b087-709b-9197-052863218223","creditsUsed":2}
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://stackoverflow.com/questions/3747232/how-expensive-sqlite3-connect-and-close-in-sqlite","title":"How expensive sqlite3.connect and close in SQLite? - Stack Overflow","description":"Connections are fairly expensive – they correspond to opening the file – but cursors aren't very so use as many as you need.python - Efficiency of reopening sqlite database after each queryCan I improve Sqlite Connection.Open time?More results from stackoverflow.com","position":1},{"url":"https://news.ycombinator.com/item?id=44530518","title":"SQLite async connection pool for high-performance - Hacker News","description":"Opening and closing SQLite connections is expensive. If we can re-use the same instance things go a lot faster. anacrolix on July 15, 2025 ...","position":2},{"url":"https://sqlite.org/forum/info/4393a42b3b5e2382","title":"Tips for getting SQLite under Python to perform better with more RAM?","description":"I'm interested in getting better performance out of SQLite on machines with more RAM, using the Python sqlite3 module from the standard ...Questions about running SQL queries in parallel for performance - SQLitesqlite write performance is slower than the filesystemMore results from sqlite.org","position":3},{"url":"https://remusao.github.io/posts/few-tips-sqlite-perf.html","title":"Getting the most out of SQLite3 with Python","description":"# Getting the most out of SQLite3 with Python\n## Use Bulk Operations\n```\nconnection.executemany(\n 'INSERT INTO my_table VALUE (?)',\n iter_data()\n)\n```\n\n- `executemany`: **1.6** seconds\n\n## Use Pragmas\n```\nconnection.execute('PRAGMA synchronous = OFF')\n```\n\n```\nconnection.execute('PRAGMA journal_mode = WAL')\n```","position":4},{"url":"https://docs.python.org/3/library/sqlite3.html","title":"sqlite3 — DB-API 2.0 interface for SQLite databases — Python 3.14.7 ...","description":"# `sqlite3` — DB-API 2.0 interface for SQLite databases [¶](https://docs.python.org/3/library/sqlite3.html#module-sqlite3)\n## Reference [¶](https://docs.python.org/3/library/sqlite3.html#reference)\n### Connection objects [¶](https://docs.python.org/3/library/sqlite3.html#connection-objects)\n```\n>>> con.getlimit(sqlite3.SQLITE_LIMIT_SQL_LENGTH)\n1000000000\n```","position":5},{"url":"https://powersync.com/blog/sqlite-optimizations-for-ultra-high-performance","title":"SQLite Optimizations For Ultra High-Performance - PowerSync","description":"# SQLite Optimizations For Ultra High-Performance\n## Key SQLite Performance Optimizations To Consider\n### **#** 1: Enable Write-Ahead Logging (WAL) And Disable Synchronous Mode\n```\npragma journal_mode = WAL;\npragma synchronous = normal;\npragma journal_size_limit = 6144000;\n```\n\n### **#** 5: Optimize Concurrency\nHowever, each separate \"connection\" is effectively single-threaded.","position":6}]},"id":"01a08314-01b2-762f-a3be-ec169e73f991","creditsUsed":2}
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://pytest-xdist.readthedocs.io/en/stable/distribution.html","title":"Running tests across multiple CPUs — pytest-xdist documentation","description":"- Running tests across multiple CPUs\n\n# Running tests across multiple CPUs [](https://pytest-xdist.readthedocs.io/en/stable/distribution.html#running-tests-across-multiple-cpus)\n```\npytest -n auto\n```\n\nThis can lead to considerable speed ups, especially if your test suite takes a noticeable amount of time.\n\nWith `-n auto`, pytest-xdist will use as many processes as your computer\n\nif it is not or if it fails to determine the number of logical CPUs, fall back to `-n auto` behavior.\n\nUse `-n 0` to disable xdist and run all tests in the main process.\n\nTo specify a different meaning for `-n auto` and `-n logical` for your tests, you can:\n\n- `--maxprocesses=maxprocesses`: limit the maximum number of workers to\nprocess the tests.\n- `--max-worker-restart`: maximum number of workers that can be restarted\nwhen crashed (set to zero to disable this feature).\n\n```\n@pytest.mark.xdist_group(name=\"group1\")\ndef test1():\n pass\n\n\nclass TestA:\n @pytest.mark.xdist_group(\"group1\")\n def test2():\n pass\n```\n\n- `--dist no`: The normal pytest execution mode, runs one test at a time (no distribution at all).","position":1},{"url":"https://stackoverflow.com/questions/45733763/how-to-run-pytest-tests-in-parallel","title":"How to run pytest tests in parallel? - python - Stack Overflow","description":"UPDATE: The solution below is to demonstrate concurrent pytests are possible, but pytest-parallel is currently unmaintained. pytest-xdist is a ...pytest fixtures and threads synchronizations - Stack OverflowPytest with multiprocessing lock not working as expected when running ...More results from stackoverflow.com","position":2},{"url":"https://github.com/pytest-dev/pytest/discussions/12188","title":"Is there an easy way to disable thread parallelism for tests in one file?","description":"If you're using the pytest-xdist plugin … you can disable parallelism by specifying -n 0 when you run pytest.Is it possible to run in parallel only some of the tests ? #325 - GitHubEnforce serial execution of related tests · Issue #84 · pytest ... - GitHubMore results from github.com","position":3,"category":"github"},{"url":"https://qaskills.sh/blog/pytest-benchmark-performance-testing-guide","title":"pytest-benchmark: The Complete Performance Testing Guide (2026)","description":"# pytest-benchmark: The Complete Performance Testing Guide\n## Installing pytest-benchmark\n```bash\n# requirements-dev.txt\npytest>=8.0\npytest-benchmark>=4.0\n```\n\n```bash\npytest --version -V\n# Look for \"benchmark-x.y.z\" in the registered plugins list\n```\n\n## Saving benchmark results\n```bash\npytest --benchmark-save=baseline\n```\n\n## Grouping benchmarks for analysis\n```bash\npytest --benchmark-group-by=group\n```\n\n## Disabling garbage collection and calibration\n```bash\npytest --benchmark-disable-gc\n```\n\n## A complete CLI flag reference\n```ini\n[pytest]\naddopts = --benchmark-disable-gc --benchmark-sort=min\n```\n\n## Pitfalls and the noise problem\nThe result is that the same code can benchmark 30% faster or slower between two runs with no code change at all.\n\nFirst, do not run benchmarks under pytest-xdist; parallel workers contend for the same cores and destroy the measurement, so always run the benchmark suite single-process. Third, beware dead-code elimination at the Python level is not really a thing, but a benchmark whose result is never used can still mislead you if the function lazily defers work, so always consume the return value.\n\n## Frequently Asked Questions\n### Why are my benchmark results so noisy on CI?\nShared CI runners are multi-tenant, so your job competes for CPU, cache, and memory bandwidth with other tenants, producing swings of 30% or more with no code change. Always compare relative deltas against a baseline measured on the same runner type, set a generous fail threshold like `min:15%`, disable GC during timing, and never run benchmarks under pytest-xdist parallel workers.","position":4},{"url":"https://www.youtube.com/watch?v=tBnfDaPAH44","title":"Test Parallelization with pytest-xdist - YouTube","description":"In this video we look at how to parallelize tests with the plugin pytest-xdist! pytest-xdist Docs: https://pypi.org/project/pytest-xdist/ ...","position":5}]},"id":"01a08314-01f6-76e0-a85b-8892a8a01515","creditsUsed":2}
|
||||
@@ -0,0 +1,85 @@
|
||||
[Index](https://avi.im/blag/)
|
||||
|
||||
[About](https://avi.im/blag/about)[Now](https://avi.im/blag/now)
|
||||
|
||||
# PSA: SQLite WAL checksums fail silently and may lose data
|
||||
|
||||
22 Jul 2025
|
||||
|
||||
This is a follow-up post to my [PSA: SQLite does not do checksums](https://avi.im/blag/2024/sqlite-bit-flip) and [PSA: Most databases do not do checksums by default](https://avi.im/blag/2024/databases-checksum). In the previous posts I mentioned that SQLite does not do checksums by default, but it has checksums in WAL mode. However, on checksum errors, instead of raising error, it drops all the subsequent frames. Even if they are not corrupt. This is not a bug; it’s intentional.
|
||||
|
||||
Disclosure: I work at Turso, which maintains a SQLite fork, libSQL. Since libSQL is a fork, it also has the same issue.
|
||||
|
||||
## SQLite WAL
|
||||
|
||||
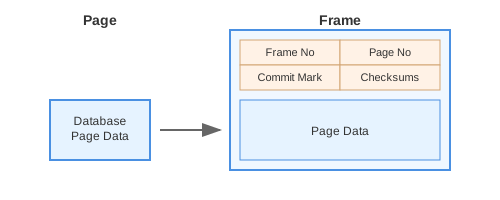
SQLite introduced WAL in 2010. It’s not the default mode, but you’re likely using it if you want higher write throughput. Whenever you make writes, they are first written to the WAL file. Then, during checkpoint operations, the database pages are written from the WAL to the main DB file. Each page in the WAL is called a frame. Each frame has a header, which comprises the frame number, page number, commit marker, and checksums.
|
||||
|
||||
|
||||
|
||||
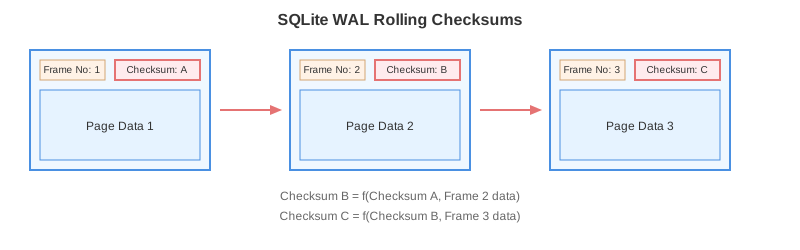
The way checksums work in WAL is interesting. They use rolling checksums, meaning the checksum of the n+1 frame is computed with the checksum of the nth frame. In other words, a frame’s checksum depends on the previous frame.
|
||||
|
||||
|
||||
|
||||
## Recovery
|
||||
|
||||
If one frame is found to have a checksum mismatch, you can’t be sure that the next frame isn’t corrupted either. What’s interesting is that when a frame is found to have a missing or invalid checksum, SQLite drops that frame and all the subsequent frames. This is [documented](https://www.sqlite.org/walformat.html#recovery):
|
||||
|
||||
> Recovery works by doing a single pass over the WAL, from beginning to end. The checksums are verified on each frame of the WAL as it is read. The scan stops at the end of the file or at the first invalid checksum. The mxFrame field is set to the index of the last valid commit frame in WAL.
|
||||
|
||||
Earlier I mentioned SQLite does not do checksums by default, so it won’t ever notice if a page is corrupt. So when is WAL checksum verification triggered? A WAL may contain multiple frames for the same page number. To make lookups faster, SQLite maintains an index called the WAL Index. This is the `.db-shm` file you often see. During the building of this index, SQLite checks the checksums.
|
||||
|
||||
You can verify this in the code as well. The recovery process happens in [`walIndexRecover`](https://github.com/sqlite/sqlite/blob/version-3.50.3/src/wal.c#L1384), this calls [`walDecodeFrame`](https://github.com/sqlite/sqlite/blob/version-3.50.3/src/wal.c#L1000) which has this:
|
||||
|
||||
```c
|
||||
/* A frame is only valid if a checksum of the WAL header,
|
||||
** all prior frames, the first 16 bytes of this frame-header,
|
||||
** and the frame-data matches the checksum in the last 8
|
||||
** bytes of this frame-header.
|
||||
*/
|
||||
nativeCksum = (pWal->hdr.bigEndCksum==SQLITE_BIGENDIAN);
|
||||
walChecksumBytes(nativeCksum, aFrame, 8, aCksum, aCksum);
|
||||
walChecksumBytes(nativeCksum, aData, pWal->szPage, aCksum, aCksum);
|
||||
if( aCksum[0]!=sqlite3Get4byte(&aFrame[16])
|
||||
|| aCksum[1]!=sqlite3Get4byte(&aFrame[20])
|
||||
){
|
||||
/* Checksum failed. */
|
||||
return 0;
|
||||
}
|
||||
```
|
||||
|
||||
To trigger this issue, the following needs to happen:
|
||||
|
||||
1. You have SQLite `.db` and `.db-wal` files, but no accompanying `.db-shm` file. Maybe your friend shared it with you, or you downloaded some data off the internet.
|
||||
2. Unclean shutdown during WAL write. The WAL index is updated after a successful write. Maybe after the WAL write, the process crashed, and the index wasn’t updated. On the next start, SQLite rebuilds the index.
|
||||
|
||||
During this process, if there’s a checksum mismatch on a frame, that frame and the rest of the WAL frames are dropped. Even if they are not corrupt (technically)! Note that SQLite always checkpoints and truncates the WAL file on the last connection close.
|
||||
|
||||
## Demo
|
||||
|
||||
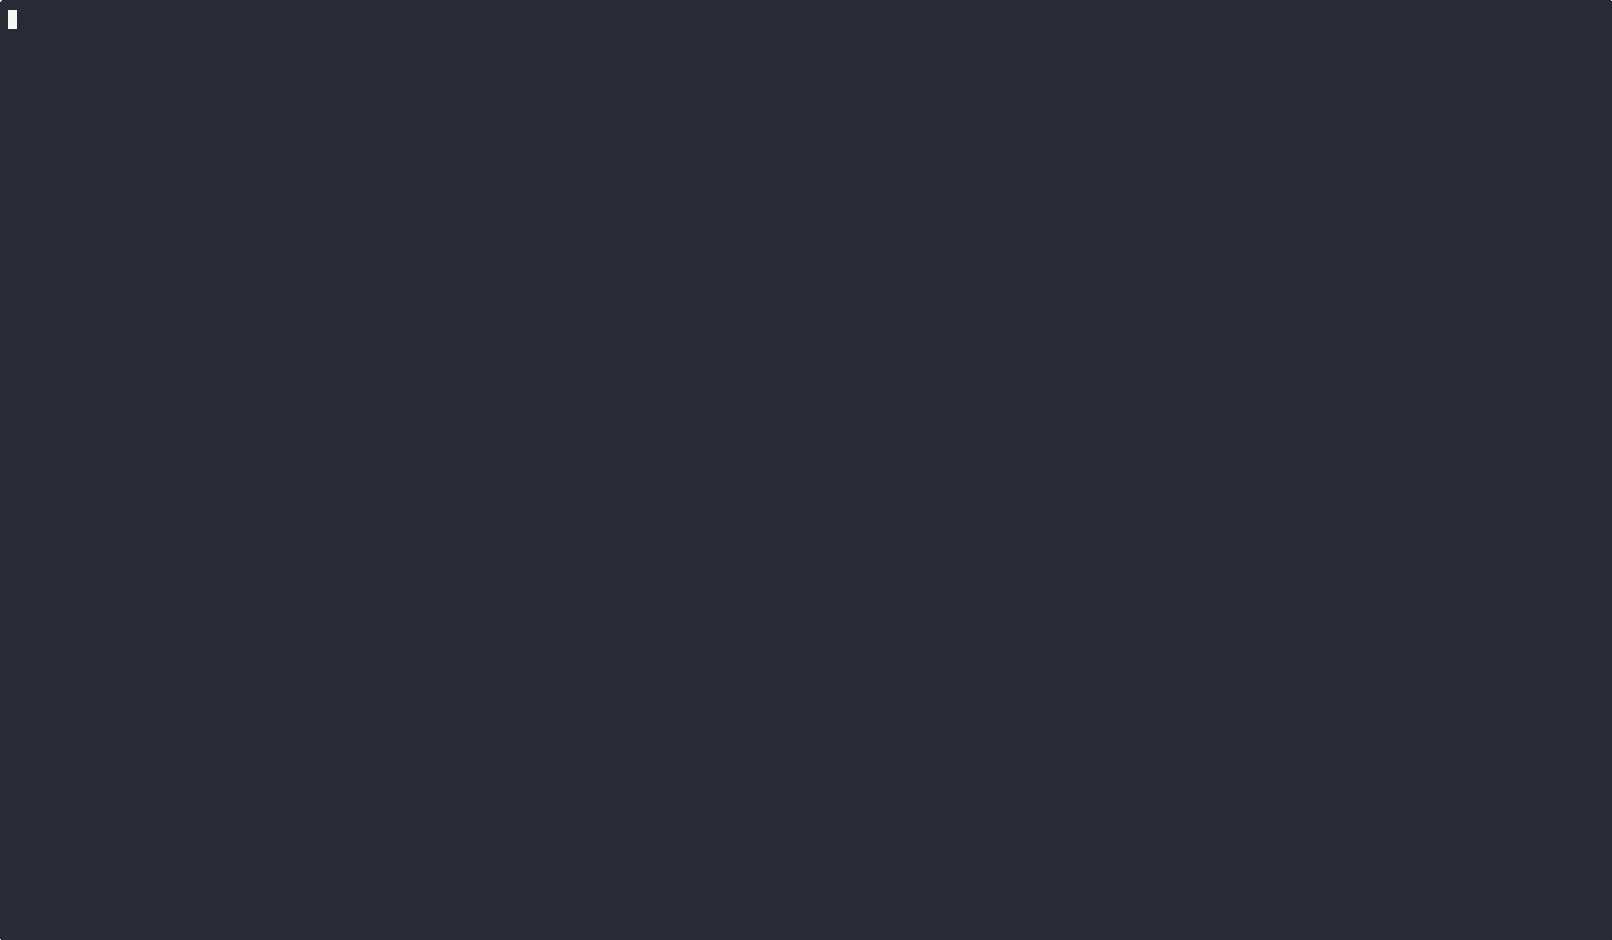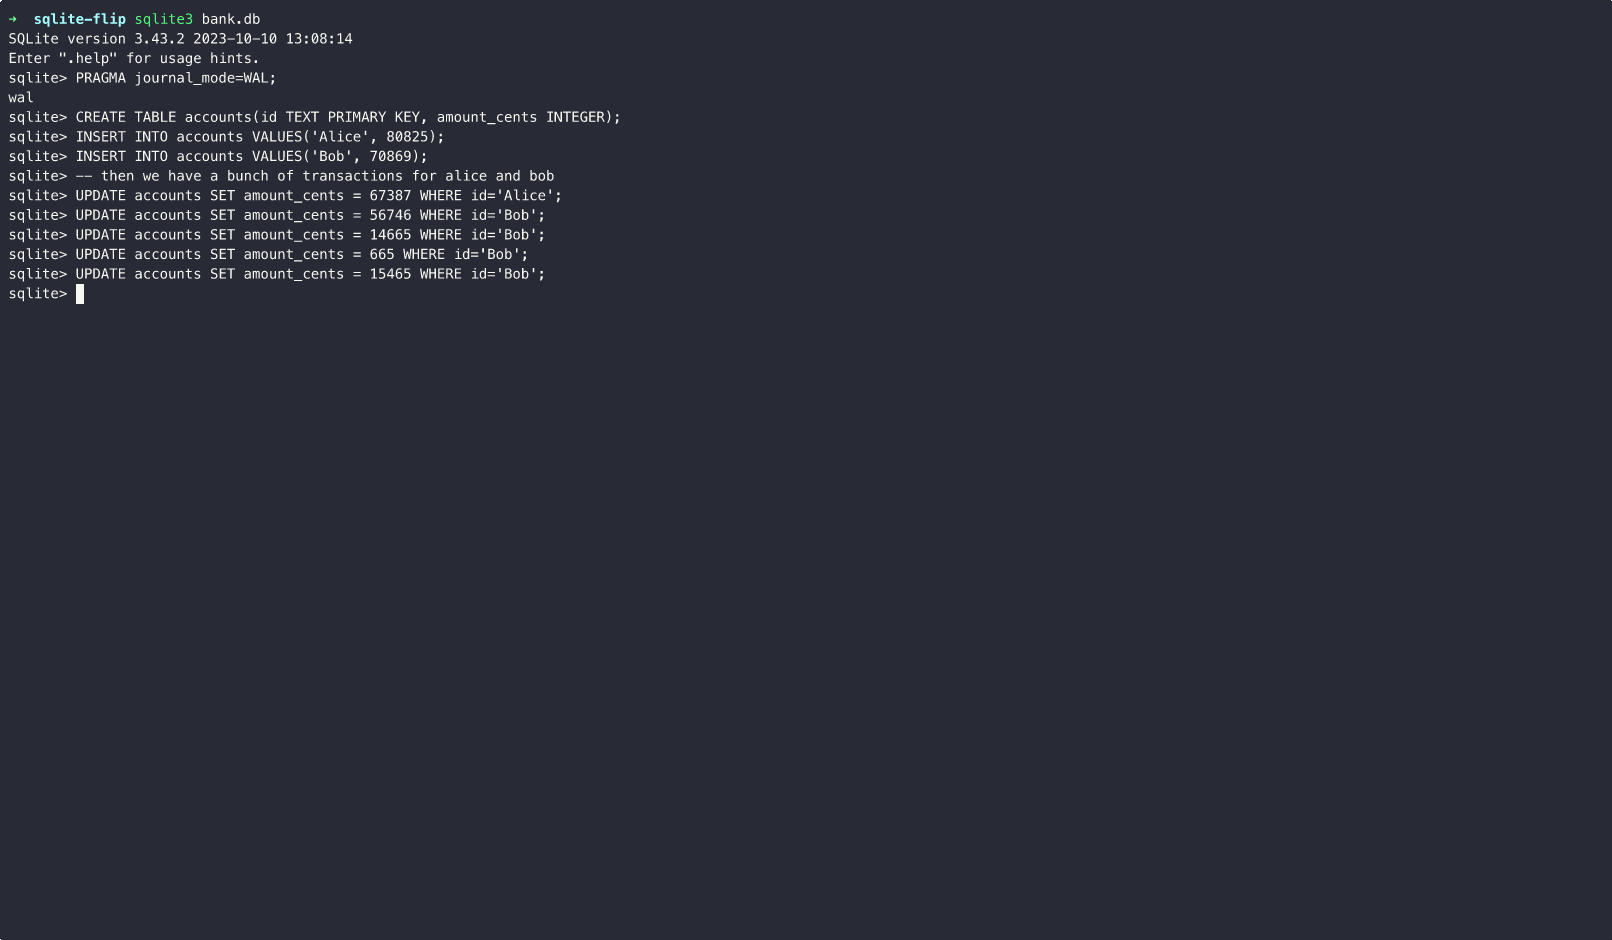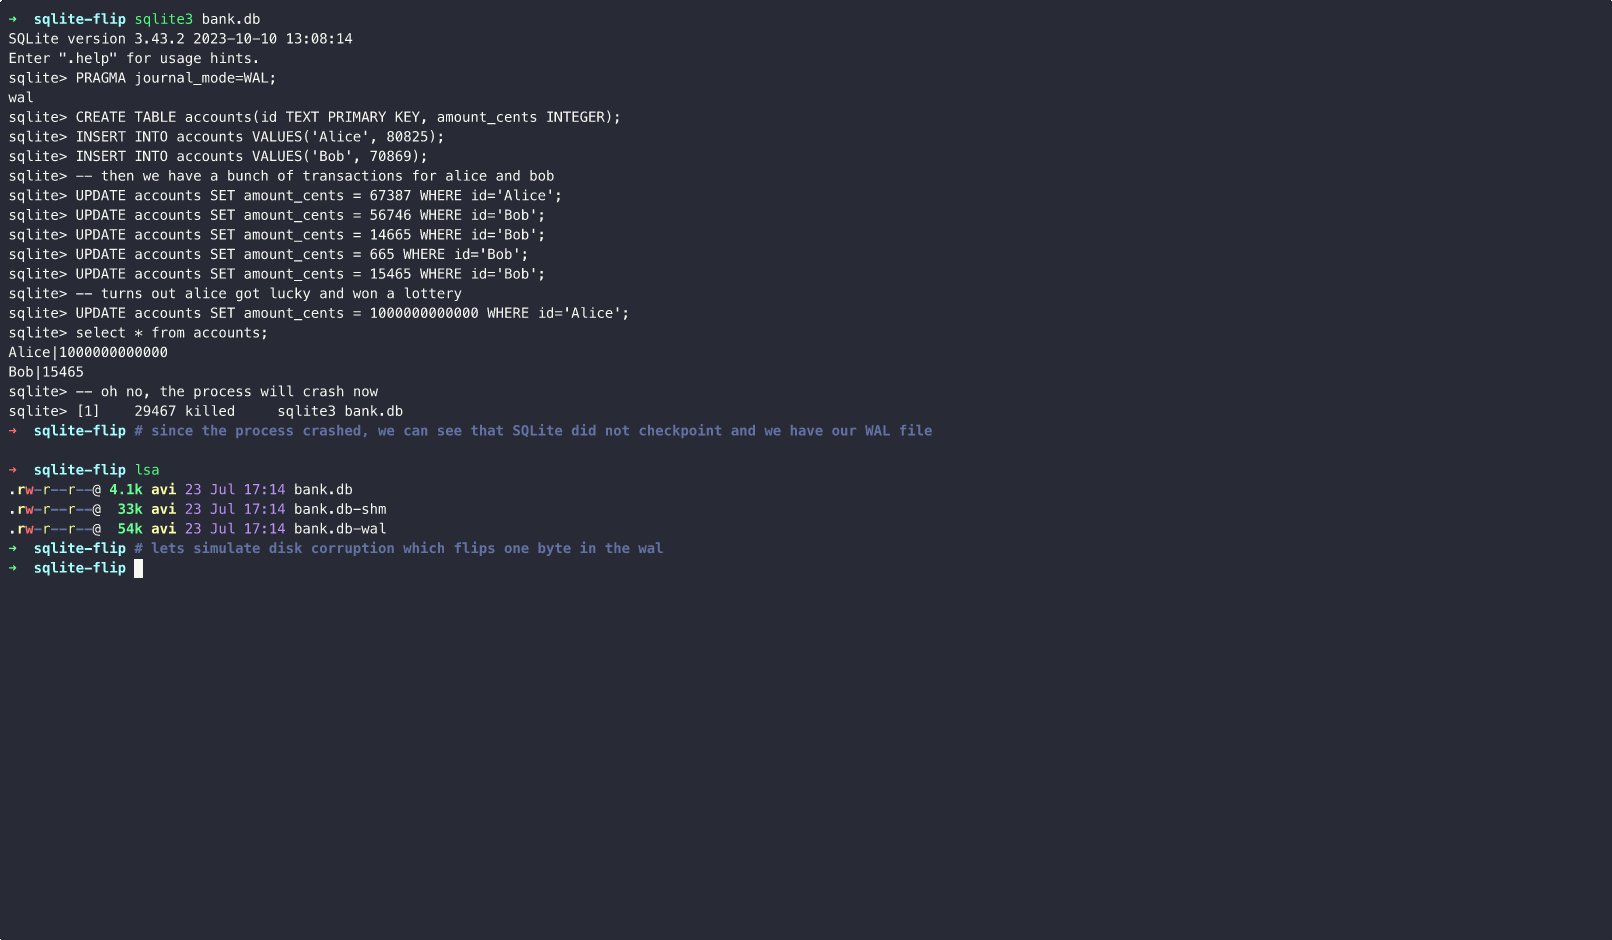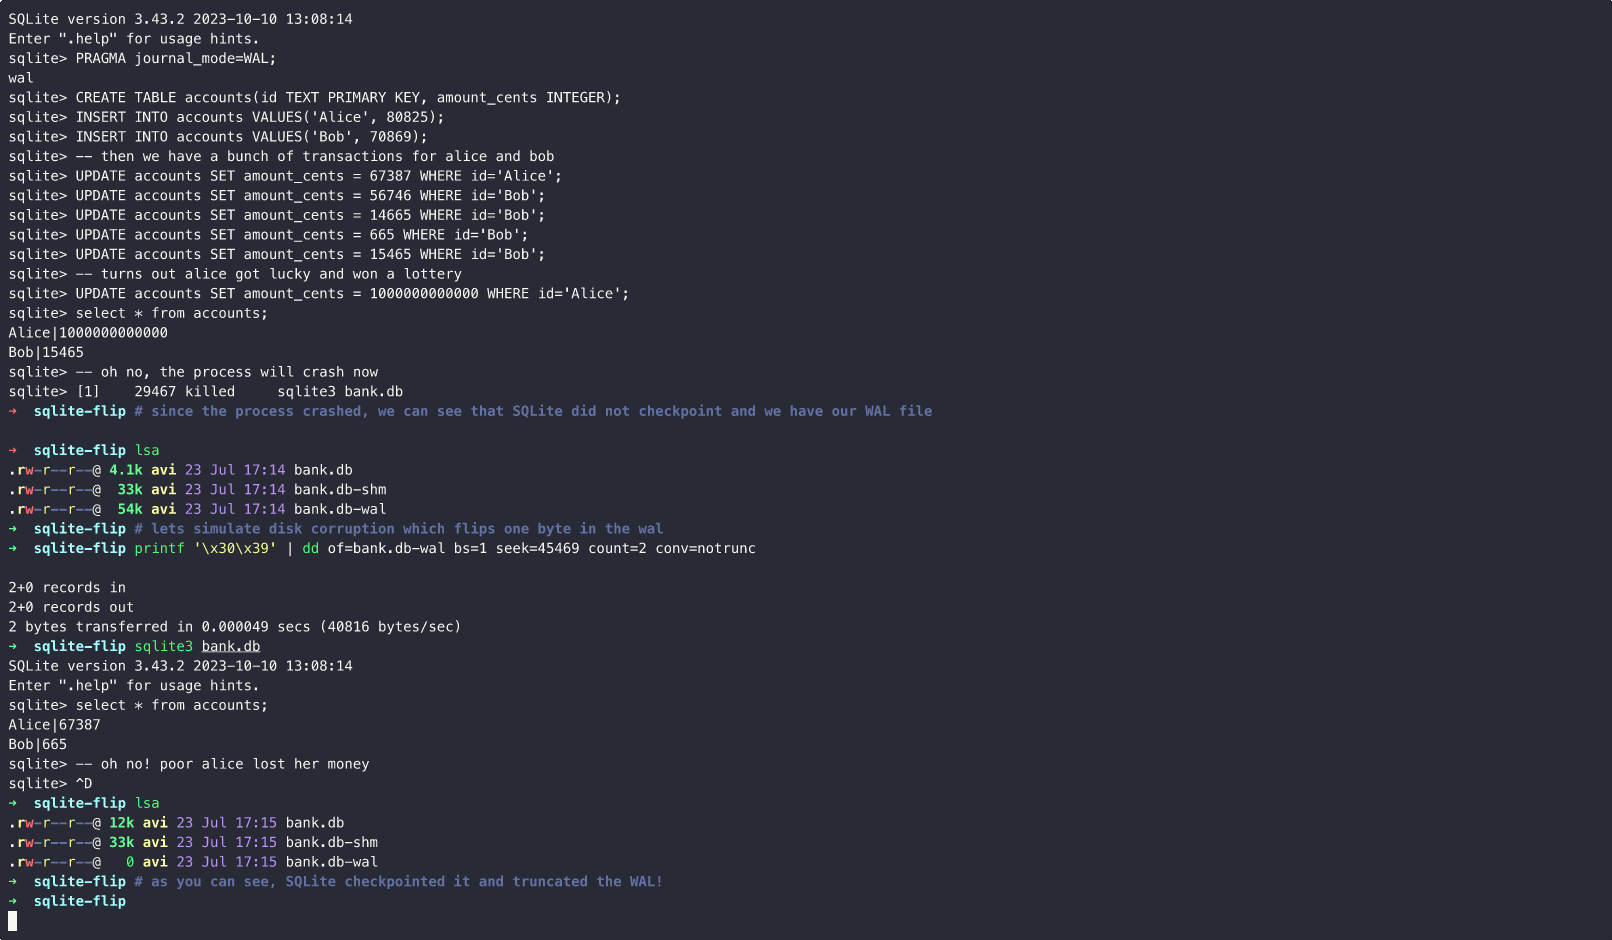
|
||||
|
||||
Alice would have lost money, [again](https://avi.im/blag/2024/sqlite-bit-flip). Poor Alice.
|
||||
|
||||
## Thoughts
|
||||
|
||||
1. I really don’t like that SQLite doesn’t throw any error on detection of corruption
|
||||
2. Since it automatically checkpoints every time, the data is lost too
|
||||
|
||||
I’m not sure why this is the default behavior. Backward compatibility reasons? The checksums in WAL are likely not meant to check for random page corruption in the middle; maybe they’re just to check if the last write of a frame was fsynced properly or not?
|
||||
|
||||
What I want: throw an error when corruption is detected and let the code handle it. Don’t checkpoint and truncate the WAL! Maybe provide an option for users to opt in to ignore the corruption and work with the existing behavior.
|
||||
|
||||
In the demo, I corrupted a frame that belonged to an older version of a page. Meaning no new transactions can ever read that data. That frame is practically useless, yet it caused data loss. There are pages like belonging to an index or maybe some table that we don’t care about at all. With sophisticated recovery mechanisms, we could sometimes able to recover all the data.
|
||||
|
||||
Overall, I don’t like the default that it does not raise an error. However, [Pekka Enberg](https://x.com/penberg) offered a different perspective that SQLite runs in embedded environments where there’s no server, and maybe core developers decided it may be better to limp along than crash.
|
||||
|
||||
I would guess that other databases behave the same way, but I haven’t verified it myself. I was discussing this with [Alex Miller](https://transactional.blog/), and he raised an interesting point: SQLite mostly runs on mobile devices with cheap SD cards (as opposed to running on enterprise-grade SSDs), and corruptions are more common. So, it’s more important for SQLite to have corruption detection than other databases.
|
||||
|
||||
Update:
|
||||
The paper [Redundancy Does Not Imply Fault Tolerance: Analysis of Distributed Storage Reactions to Single Errors and Corruptions](https://www.usenix.org/conference/fast17/technical-sessions/presentation/ganesan) is worth a read. Here is a [tweet from one of the authors](https://x.com/AishwaryaGanlat/status/1948473336717345115) in response to this article.
|
||||
|
||||
Subscribe
|
||||
|
||||
Want to become a better programmer? [Join the Recurse Center!](https://www.recurse.com/scout/click?t=a4aabd5087bb19daf083302de1b46650)
|
||||
|
||||
[](https://github.com/avinassh "GitHub")[](https://avi.im/blag/index.xml "GitHub")
|
||||
@@ -0,0 +1,185 @@
|
||||
[Skip to Main Menu](https://berthub.eu/articles/posts/a-brief-post-on-sqlite3-database-locked-despite-timeout/#main-menu)Toggle Sidebar
|
||||
|
||||
[](https://berthub.eu/articles/)
|
||||
|
||||
Also see: [berthub.eu](https://berthub.eu/).
|
||||
|
||||
[Subscribe to mailing list](https://berthub.eu/ckmailer/start.html?hl=c5)
|
||||
|
||||
[Schrijf in voor nieuwsbrief](https://berthub.eu/ckmailer/start.html?hl=c3)
|
||||
|
||||
[Skip to Content](https://berthub.eu/articles/posts/a-brief-post-on-sqlite3-database-locked-despite-timeout/#content)Toggle Sidebar
|
||||
|
||||
Bert Hubert's writings
|
||||
|
||||
bert@hubertnet.nl
|
||||
|
||||
# What to do about SQLITE\_BUSY errors despite setting a timeout
|
||||
|
||||
Posted on Feb 16 2025
|
||||
|
||||
So I’m a huge SQLite fanboy and I use it for almost everything these days. Recently, the project added [sqlite3\_rsync](https://www.sqlite.org/rsync.html) which allows you to swiftly replicate your database to other servers (or to the same server if you want), and this really was the cherry on top for me.
|
||||
|
||||
Last week however, I ran into one of my projects unexpectedly getting [SQLITE\_BUSY](https://www.sqlite.org/rescode.html#busy) errors. And then someone urged me to run ‘a real database’ (PostgreSQL), and that hurt.
|
||||
|
||||
> The tl;dr on this, to prevent SQLITE\_BUSY errors even when setting a timeout, don’t ever upgrade transactions to read-write. If you know you are going to write in a transaction, use ‘BEGIN IMMEDIATE’, or start off with the write. But do read on for why this is so, and how other databases struggle with this problem as well.
|
||||
>
|
||||
> Thanks are due to PostgreSQL developer & backdoor-slayer [Andres Freund for sharing his wisdom on Mastodon](https://mastodon.social/@AndresFreundTec/114009633982257113), which found its way into this post. Mistakes remain mine though!
|
||||
|
||||
Before we start, do know I love both PostgreSQL and SQLite, these are two very impressive projects, and we are extremely lucky that we get to benefit from all this excellence.
|
||||
|
||||
# The problem
|
||||
|
||||
When running in [WAL mode](https://www.sqlite.org/wal.html) (which you should), SQLite makes some explicit and detailed concurrency promises: “Readers do not block writers and a writer does not block readers. Reading and writing can proceed concurrently”. The devil is in those details however.
|
||||
|
||||
Now, we can easily deal with _waiting_ for the database to do something. Often there aren’t that many writes, and if occasionally two writes have to wait for each other, this is not a problem, especially since SQLite is extremely fast anyhow. SQLite’s single writer mode will often in practice be faster than other server’s multiple writer models, if only because it has no interprocess/network latency penalty. Meanwhile, SQLite offers various timeout settings and functions to deal with waiting for write access.
|
||||
|
||||
What is harder to deal with however is when queries or inserts don’t wait but immediately dump a SQLITE\_BUSY error on you, despite setting a timeout. It can be hard to recover from that.
|
||||
|
||||
So why does this happen?
|
||||
|
||||
# SQLite transactions
|
||||
|
||||
SQLite allows you to [BEGIN a transaction](https://www.sqlite.org/lang_transaction.html) without telling it what kind of transaction this will be: read-only or a read-write transaction. SQLite actually determines this based on the first statement you execute within the transaction. If that is an UPDATE or a DELETE or anything else that changes things, you get a write capable transaction. Otherwise you get a read-only transaction. You can also force this decision with BEGIN IMMEDIATE, which always starts a write transaction.
|
||||
|
||||
To demonstrate this, we’ll first setup a database:
|
||||
|
||||
```sql
|
||||
pragma journal_mode="wal"; -- only have to do this once
|
||||
create table t (v INT) strict;
|
||||
.timeout 10000 -- 10 seconds
|
||||
```
|
||||
|
||||
Next up, let’s open two parallel connections:
|
||||
|
||||
```
|
||||
begin immediate; |
|
||||
insert into t values (1); | begin immediate; -- blocks
|
||||
commit; | -- we are unblocked
|
||||
| insert into t values(2);
|
||||
| commit;
|
||||
```
|
||||
|
||||
This is all good. It may be disappointing that SQLite only allows one simultaneous writer, but at least this is clear, and by waiting for a bit, our writes do happen (sequentially). If we leave the transaction on the left open for too long, the right side will get a SQLITE\_BUSY error:
|
||||
|
||||
```
|
||||
Runtime error: database is locked (5)
|
||||
```
|
||||
|
||||
Figuring out the right timeout is not easy. But, if you get a timeout, you can reconsider, and perhaps decide to wait even longer.
|
||||
|
||||
# Getting into trouble
|
||||
|
||||
As noted, if you BEGIN a transaction in SQLite without specifying ‘immediate’, SQLite actually only begins a transaction after you submit the first statement, and it will pick the _kind_ of transaction based on that first statement (read-only or read-write).
|
||||
|
||||
If you later in a read-only transaction try to write to the database somehow, SQLite will attempt to _upgrade_ your transaction to a write transaction. And this is where we can run into problems:
|
||||
|
||||
```
|
||||
| begin;
|
||||
begin; | insert into t values(2);
|
||||
select count(1) from t; | -- we are in a WRITE transaction
|
||||
insert into t values(3); |
|
||||
Runtime error: database is locked (5) -- immediately
|
||||
```
|
||||
|
||||
The right side opens a write transaction based on the initial ‘insert’ statement.
|
||||
The left side opens a read-only transaction, while the right side has a write transaction open. SQLite supports this just fine.
|
||||
|
||||
Then however the left site tries to do an insert, which leads to an attempt to upgrade the transaction to read-write. And this fails immediately. No matter how high you set your .timeout, this scenario always delivers an instant SQLITE\_BUSY error. And this is frustrating.
|
||||
|
||||
# Why does this have to happen?
|
||||
|
||||
At this point, you might have preferred to have the insert on the left just wait it out until the transaction on the right is done. But no can do.
|
||||
|
||||
SQLite implements a [transaction isolation mode called “serializable”](https://www.sqlite.org/isolation.html). The technical definition from [some kind of SQL standard informal draft review](https://en.wikipedia.org/wiki/Isolation_(database_systems)#Serializable) (?): “A serializable execution is defined to be an execution of the operations of concurrently executing SQL-transactions that produces the same effect as _some_ serial execution of those same SQL-transactions”.
|
||||
|
||||
When the transaction on the left wanted to upgrade itself to a read-write transaction, SQLite could not allow this since the transaction on the right might already have made changes that the transaction on the left had not yet seen.
|
||||
|
||||
This in turn means that if left and right transactions would commit sequentially, the result would not necessarily be what would have happened if all statements had been executed sequentially within the same transaction. So no go.
|
||||
|
||||
Now, this is not a SQLite problem, all quality databases mostly do the same thing when in SERIALIZABLE mode.
|
||||
|
||||
Let’s try it in PostgreSQL:
|
||||
|
||||
```
|
||||
SET SESSION CHARACTERISTICS AS TRANSACTION ISOLATION LEVEL serializable;
|
||||
```
|
||||
|
||||
Then we run two transactions:
|
||||
|
||||
```
|
||||
| begin;
|
||||
begin; | select count(1) from t;
|
||||
select count(1) from t; | insert into t values (2);
|
||||
insert into t values (1); | commit;
|
||||
commit; |
|
||||
ERROR: could not serialize access due to read/write dependencies among transactions
|
||||
DETAIL: Reason code: Canceled on identification as a pivot, during commit attempt.
|
||||
HINT: The transaction might succeed if retried.
|
||||
```
|
||||
|
||||
It may be good to know that in many common cases, PostgreSQL can prove there are no serialization issues, and will in fact be able to commit both transactions without issue. But not always.
|
||||
|
||||
Another key difference is that PostgreSQL, being an extremely impressive project, allows for multiple transaction isolation levels, some of which do not get you these errors (but also not this consistency). SQLite just has one mode (also due to its straightforward design which lacks row-level locks).
|
||||
|
||||
It turns out that there is a fundamental issue with concurrent read-write access to all databases - you can have slow operations that never fail nor get errors, or you can run in faster modes where you could get inconsistent results, or you can pick a mode where you will have to learn how to recover from writes that failed and need to be reissued somehow. If someone smugly tells you their “real database” supports multiple writers, know that they probably aren’t aware of [these trade-offs](https://www.postgresql.org/docs/current/transaction-iso.html).
|
||||
|
||||
By default, PostgreSQL runs in Read Committed isolation mode, which leads to the following behaviour that may be surprising for people coming from SQLite or MySQL:
|
||||
|
||||
```
|
||||
BEGIN; | BEGIN;
|
||||
select count(1) from t; | insert into t values (3);
|
||||
4 | COMMIT;
|
||||
select count(1) from t; |
|
||||
5 |
|
||||
COMMIT; |
|
||||
```
|
||||
|
||||
In SQLite and [MySQL](https://dev.mysql.com/doc/refman/8.4/en/innodb-transaction-isolation-levels.html), the left transaction would not have seen the insert that happened on the right. As long as the left transaction is open, no changes are observed. But in PostgreSQL’s default mode, you do see them. Note that MySQL defaults not to serializable but to ‘ [repeatable read](https://en.wikipedia.org/wiki/Isolation_(database_systems)#Repeatable_reads)’.
|
||||
|
||||
Again, [this is all a matter of choice](https://mastodon.social/@AndresFreundTec/114009633982257113), and there are [lots of reasons to prefer one transaction isolation mode over another](https://www.postgresql.org/docs/current/transaction-iso.html). Just know and understand which one you are using!
|
||||
|
||||
# Ok, but now what
|
||||
|
||||
The excellent [PostgreSQL documentation notes that serializable mode can lead to failing transactions that need to be repeated](https://www.postgresql.org/docs/current/transaction-iso.html#XACT-SERIALIZABLE). And they also offer us advice for how to ameliorate that, and this advice is very useful for SQLite as well:
|
||||
|
||||
- Declare transactions (or connections in SQLite) as READ ONLY when possible.
|
||||
- Control the number of active connections, using a connection pool if needed. This is always an important performance consideration, but it can be particularly important in a busy system using Serializable transactions.
|
||||
- Don’t put more into a single transaction than needed for integrity purposes.
|
||||
- Don’t leave connections dangling “idle in transaction” longer than necessary
|
||||
|
||||
This is all mitigation. To absolutely prevent SQLITE\_BUSY errors, you have a few options (when running in WAL mode):
|
||||
|
||||
- If you know you are going to write in a transaction, start it with a write, or use BEGIN IMMEDIATE
|
||||
- Just don’t use transactions, or effectively, use single-statement transactions
|
||||
|
||||
You might read here and there to just always use BEGIN IMMEDIATE but that will easily cause timeouts, since you can only have a single write transaction open at a time.
|
||||
|
||||
It is better to have a good think on how you do writes, and completely avoid transactions that have to be upgraded. Because that is where the immediate SQLITE\_BUSY errors come from once you’ve made a database connection.
|
||||
|
||||
# SQLITE\_BUSY\_RECOVERY
|
||||
|
||||
If your program starts by opening multiple SQLite connections at the same time, you might get a SQLITE\_BUSY error at that stage. This has to do with [the rolling the WAL journal when recovering from an unclean shutdown](https://www.sqlite.org/rescode.html#busy_recovery). If you open multiple SQLite connections at the beginning of your program, I recommend doing so sequentially. This admittedly is somewhat of a wart.
|
||||
|
||||
# Some further reading
|
||||
|
||||
- [Wikipedia page Isolation (database systems)](https://en.wikipedia.org/wiki/Isolation_(database_systems))
|
||||
- [SQLite Transactions page](https://www.sqlite.org/lang_transaction.html)
|
||||
- [SQLITE\_BUSY](https://www.sqlite.org/rescode.html#busy)
|
||||
- [How SELECT FOR UPDATE Works (in PostgreSQL)](https://haril.dev/en/blog/2024/04/20/select-for-update-in-PostgreSQL)
|
||||
|
||||
Tags: [programming](https://berthub.eu/articles/tags/programming/)
|
||||
|
||||
[PreviousPrevious post: Rondetafelgesprek Tweede Kamer Digitale Soevereiniteit Rijksoverheid 13 Februari 2025](https://berthub.eu/articles/posts/digitale-soevereiniteit-rijksoverheid-13-februari-2025/)
|
||||
|
||||
[Next post: Voor de duidelijkheid: Open-XchangeNext](https://berthub.eu/articles/posts/voor-de-duidelijkheid-open-xchange/)
|
||||
|
||||
- [Open Github account in new tab](https://github.com/berthubert)
|
||||
- [Contact via Email](mailto:bert@hubertnet.nl)
|
||||
- [Open Linkedin account in new tab](https://linkedin.com/in/bert-hubert-b05452)
|
||||
- [Open Mastodon account in new tab](https://eupolicy.social/@bert_hubert)
|
||||
- [Open Google\_scholar account in new tab](https://scholar.google.com/citations?user=cc3n86AAAAAJ)
|
||||
|
||||
© 2014-2026 bert hubert
|
||||
|
||||
[Support Ukraine](https://u24.gov.ua/)
|
||||
@@ -0,0 +1,270 @@
|
||||
[Bugsink](https://www.bugsink.com/)
|
||||
|
||||
- [Docs](https://www.bugsink.com/docs/)
|
||||
- [Blog](https://www.bugsink.com/blog/)
|
||||
- [Code](https://github.com/bugsink/bugsink/)
|
||||
- [Community](https://www.bugsink.com/community/)
|
||||
- [Pricing](https://www.bugsink.com/#pricing)
|
||||
- [Sign Up](https://www.bugsink.com/register/15K/)
|
||||
|
||||
[](https://www.bugsink.com/)[Bugsink](https://www.bugsink.com/)
|
||||
|
||||
[Docs](https://www.bugsink.com/docs/) [Blog](https://www.bugsink.com/blog/) [Code](https://github.com/bugsink/bugsink/) [Community](https://www.bugsink.com/community/) [Pricing](https://www.bugsink.com/#pricing) [Sign Up](https://www.bugsink.com/register/15K/)
|
||||
|
||||
# The single-writer Database Architecture
|
||||
|
||||
|
||||
|
||||
Klaas van Schelven;
|
||||
|
||||
March 24, 2025 - 9 min read
|
||||
|
||||
\| tags: [architecture](https://www.bugsink.com/blog/tags/architecture/)
|
||||
|
||||
|
||||
|
||||
Conveyor belt with lady-bugs. Representing the idea of processing events in a predictable, sequential manner.
|
||||
|
||||
|
||||
**TL;DR**: Bugsink uses a **single-writer architecture** to keep database state consistent and predictable.
|
||||
This model is **built around SQLite’s concurrency model**: for writes, a global lock; for reads, snapshot isolation.
|
||||
Bugsink’s specific use case ( **event processing**) makes this model a perfect fit.
|
||||
|
||||
### Introduction & Design Goals
|
||||
|
||||
In this article, we’ll take a look at Bugsink’s transaction model, and how it uses SQLite’s unique properties to
|
||||
create a simple, stable, and efficient system.
|
||||
|
||||
Bugsink is a self-hosted error tracker. This means that it’s built to be **simple to operate and safe to run**: everybody
|
||||
should be able to set it up and keep it running without too much hassle.
|
||||
|
||||
It’s also designed to be **simple to maintain**: I’m a single developer taking on a market in which VC-backed _unicorns_ operate. This
|
||||
means that I need to be able to reason about the system’s behavior quickly and confidently, even if I haven’t touched
|
||||
that particular part of the code in months.
|
||||
|
||||
Here’s how the broader design goals translate into the transaction model:
|
||||
|
||||
- **Stability**: No weird edge cases, no locking errors, no surprises under load.
|
||||
|
||||
- **Data Integrity**: The transaction model should ensure that data is never left in an inconsistent state, even if something goes wrong.
|
||||
(this is a bit of an open door, but it’s worth stating explicitly).
|
||||
|
||||
- **Simplicity**: The transaction model should be simple to understand and implement. There’s one way to do it, it’s used
|
||||
everywhere, and it’s easy to reason about later. Think once, apply everywhere.
|
||||
|
||||
- **Alignment with SQLite**: Lean into what SQLite is good at. Treat its limits as “features in disguise”, shaping
|
||||
forces that guide the design. Don’t fight the datbase.
|
||||
|
||||
- **Fit with Bugsink’s Architecture**:
|
||||
Bugsink makes strong, opinionated choices, and the transaction model leans into them. Also: the way we interact with
|
||||
the database might just influence the way we structure the application.
|
||||
|
||||
|
||||
All of these goals point in the same direction: I want a system that works correctly, but without adding extra overhead
|
||||
to my development process.
|
||||
|
||||
Contrast this with the typical “just don’t want to think about transactions at all” approach, where you just do CRUD
|
||||
operations throughout the code. That may just work, until it doesn’t. And that’s not acceptible to me.
|
||||
|
||||
Still, the underlying objective of not having to think about transactions all the time _is_ very valuable. The
|
||||
transaction model should be a given, not something that needs to be rethought for every new feature.
|
||||
|
||||
### SQLite in Production: the Basics
|
||||
|
||||
When Bugsink was first developed (i.e. when this architecture materialized), we supported only a single database: SQLite.
|
||||
This means this story starts with a production-ready configuration of SQLite.
|
||||
|
||||
By the way, that somewhat unusual choice was itself made to fit with the design goals of being easy to install and operate.
|
||||
|
||||
As recommended by basically everyone, the first step is to enable [WAL mode](https://www.sqlite.org/wal.html). Without
|
||||
it, any write blocks all readers until it completes. That’s fine for scripts or low-traffic apps, but not acceptable for
|
||||
a production system. WAL mode avoids this by allowing readers and writers to operate concurrently. It’s
|
||||
the default in Bugsink, and the foundation for everything that follows.
|
||||
|
||||
The second key concept to understand is how reads behave under WAL. SQLite provides [snapshot\\
|
||||
isolation](https://www.sqlite.org/isolation.html): a read transaction sees the database exactly as it was when the read
|
||||
began, even if concurrent writes are happening. Readers never see any writes that started after their transaction began.
|
||||
It also ensures the UI and API reflect a consistent view of the world, and it matches how most developers (humans, even)
|
||||
intuitively expect things to work.
|
||||
|
||||
### Global write lock
|
||||
|
||||
In the above, I mentioned that WAL mode allows readers and writers to operate concurrently. That’s true, in the sense
|
||||
that readers don’t block writers and vice versa.
|
||||
|
||||
Regarding multiple writers operating at the same time, however, the story is different.
|
||||
**SQLite allows only one writer at a time**. Even in WAL mode, concurrent write transactions are not possible – any attempt
|
||||
to write while another write is in progress will block or fail with a `SQLITE_BUSY` error. This limitation applies
|
||||
across all tables and connections to the database: the write lock is effectively global.
|
||||
|
||||
For many applications, that’s a dealbreaker. But it’s also one of the clearest boundaries SQLite enforces, and it gives
|
||||
you a strong guarantee: if a write is in progress, nothing else is modifying the database.
|
||||
|
||||
### Turning a Weakness into Strength
|
||||
|
||||
The global write lock might look like a limitation — but in Bugsink, it became part of the architecture.
|
||||
To turn this limitation into a strength, we embraced it fully.
|
||||
|
||||
The key insight was this: Bugsink is, at its core, **an error-event processing machine**, and it’s this event processing
|
||||
that puts the overwhelming majority of writes into the database. The other 1% or so of writes, in systems under load, are
|
||||
user-triggered actions like marking an issue as resolved or changing settings.
|
||||
|
||||
That makes it natural to **split the event-processing into ingestion and digestion phases**: receive events, queue them, and
|
||||
process them in some separate pipeline.
|
||||
|
||||
This is exactly how Bugsink works in practice. Incoming events are accepted by a lightweight ingestion process, which
|
||||
does not write to the database, but instead enqueues a digestion task to be picked up “later”.
|
||||
|
||||
A separate process reads from this queue and does the actual work of processing the event and writing it to the datbase,
|
||||
the “digestion”. For the purposes of this article, feel free to think of this **digestion process as a single-threaded,**
|
||||
**fully serialized process**. (In actuality, the process is multi-threaded and we just rely on SQLite to serialize writes,
|
||||
but that’s an implementation detail).
|
||||
|
||||
By leaning into SQLite’s locking behavior rather than fighting it, the architecture avoids contention and becomes
|
||||
simpler overall.
|
||||
|
||||
One major advantage of a single write architecture is that it removes the mental overhead of coordinating concurrent
|
||||
modifications. **With only one writer at a time, there’s no need to think about what might be changing in parallel**.
|
||||
|
||||
For example, consider what happens when a new event comes in: the event itself needs to be stored, the corresponding
|
||||
issue’s event count must be incremented, and the project-wide counters need to be updated as well. In a concurrent
|
||||
system, each of these updates might require separate locks, retries, or careful coordination to avoid subtle bugs. But
|
||||
in Bugsink’s model, all of this happens in one transaction, with no other writes taking place at the same time.
|
||||
|
||||
Of course, this does put the burden on the digestion process to be very fast: **since each digest operation is serialized,**
|
||||
**it must be able to keep up with the incoming event rate**. You can’t just “add more workers” to speed things up.
|
||||
But that’s a focused problem: one place to optimize, one code path to understand. Also: the fact that SQLite is so fast
|
||||
at writes (it’s a local database) helps a lot.
|
||||
|
||||
Some of the associated optimazations are in fact made possible by the simple model itself: various denormalizations and
|
||||
caches are trivial to compute if you know you’re alone in the database. Consider counting things: when digesting, this
|
||||
becomes a simple plus-1 operation, and those counts themselves being available in the database means they can be read
|
||||
without doing a full table scan.
|
||||
|
||||
### Technical Details
|
||||
|
||||
Let’s see how the above principles are implemented in practice.
|
||||
|
||||
#### Enabling WAL Mode
|
||||
|
||||
Bugsink ensures that the database operates in Write-Ahead Logging (WAL) mode by executing:
|
||||
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Copy
|
||||
PRAGMA journal_mode=WAL;
|
||||
PRAGMA journal_mode=WAL;
|
||||
```
|
||||
|
||||
This configuration is applied during the initial setup of the database schema: a mechanism called _migrations_ is
|
||||
already in place to ensure that the database schema matches Bugsink’s requirements, and the WAL mode simply ties into
|
||||
that by being the first migration.
|
||||
|
||||
This approach simplifies the setup process for users, as the system is ready for optimal performance out of the box.
|
||||
|
||||
#### All writes use `BEGIN IMMEDIATE`
|
||||
|
||||
To ensure that write operations never needlessly fail, Bugsink uses `BEGIN IMMEDIATE` for all write transactions. To
|
||||
understand why, let’s take a step back and look at how SQLite handles transactions.
|
||||
|
||||
In SQLite, the default transaction mode (called “deferred”) doesn’t begin a write transaction until the first write
|
||||
operation is executed. If a transaction begins with a read, it starts as a read transaction; if a write is attempted
|
||||
later, SQLite tries to upgrade it to a write transaction. But if another connection is already in the middle of a write,
|
||||
that upgrade fails, and the operation returns `SQLITE_BUSY`.
|
||||
|
||||
The reason is simple: read transactions operate on a stable snapshot of the database – as it existed when the
|
||||
read began. If a deferred transaction starts as a read and later attempts to write, SQLite faces a problem: the database
|
||||
may have changed in the meantime. SQLite would either have to break the promise of snapshot isolation to continue, or
|
||||
have the upgraded write overwrite the changes made by the concurrent write. Neither of those options are acceptible,
|
||||
so SQLite just says “no” – it errors out instead.
|
||||
|
||||
There is a way to prevent this: by starting a transaction with `BEGIN IMMEDIATE`, it becomes a write transaction right
|
||||
away. That way, if the transaction starts at all, it’s guaranteed to be able to write later. There’s no mid-flight change
|
||||
of state, and the system stays predictable. The trade-off is that the transaction is now a write transaction from the
|
||||
start, and will thus have to wait for concurrent write transactions to finish before it can begin: it will have to wait
|
||||
for the global write lock, even for the operations in the transactions that are reads.
|
||||
|
||||
That “trade-off” is a perfect match for the kind of writes Bugsink does: in the event digestion process the writes are
|
||||
sequential (one event is written after the other), and in the UI/API layer, writes are infrequent and can afford to wait
|
||||
a bit (under heavy load this might increase to half a second or so, but that’s still acceptable).
|
||||
|
||||
#### Read or Write: The Handler Decides
|
||||
|
||||
As per the above we take some care to tell SQLite about the kind of transaction we need: for operations that will
|
||||
(ultimately) involve writes, we start with `BEGIN IMMEDIATE`. For read-only operations, we start with `BEGIN`.
|
||||
|
||||
To tie this back to Python code in the HTTP request/response cycle, each view in Bugsink is wrapped in a transaction
|
||||
of the correct type. For most views, we determine which type of transaction to use based on the HTTP method: `GET`
|
||||
requests are treated as reads, and get a standard read transaction (`BEGIN`). Anything else—`POST`, `PUT`, `PATCH`,
|
||||
`DELETE`—is treated as a write, and gets a `BEGIN IMMEDIATE` transaction.
|
||||
|
||||
This is handled by a decorator called `@atomic_for_request_method`, which wraps the whole request. The main reason for
|
||||
doing this at the outermost level is that important reads (like checking project membership) often happen before the
|
||||
actual view function is called. Wrapping early ensures those reads are also included in the same transaction – and
|
||||
therefore later writes don’t error out.
|
||||
|
||||
The case of inspecting the request method is just the default.
|
||||
In some places, we take a slightly more custom approach. The most common example of doing that is when expensive read
|
||||
operations are followed by write operations: in that case a read transaction is started for the expensive reads first.
|
||||
Then a separate write transaction is started (no upgrading). This ensures that the time spent by the expensive read
|
||||
operations does contribute to the time the write transaction is open, and hence to the time the global write lock is held.
|
||||
|
||||
Of course, doing a single logical operation in multiple database transactions does require extra work, because the
|
||||
results of the read transaction need to be somehow passed to the write transaction, but without assuming that the data
|
||||
corresponds to a single point in time. In other words: this is the kind of optimization where the design goal of simplicity
|
||||
is at odds with the design goal of performance.
|
||||
|
||||
### MySQL and Postgres
|
||||
|
||||
As mentioned earlier, Bugsink started with SQLite as the only supported database. This is the database the transaction
|
||||
model was designed around. However, the system has since expanded to support other databases as well.
|
||||
|
||||
In addition to SQLite, Bugsink currently **supports MySQL and has experimental support for Postgres**. Despite differences
|
||||
between these systems and SQLite, the core transactional model has been preserved. Thanks to the use of an ORM, most of
|
||||
the database logic remains portable, with only minimal backend-specific handling.
|
||||
|
||||
Unlike SQLite, neither MySQL nor Postgres offer an exact equivalent of `BEGIN IMMEDIATE`. However, similar behavior can
|
||||
be achieved by acquiring an explicit lock at the start of the transaction. We simply issue a `SELECT ... FOR UPDATE`
|
||||
on a known, singleton, row. This ensures that only one transaction proceeds at a time, effectively emulating SQLite’s
|
||||
“one writer at a time” behavior.
|
||||
|
||||
The other property that we rely on, namely “snapshot isolation”, is also present (and is the default) in MySQL and
|
||||
Postgres.
|
||||
|
||||
The fact that these databases are in the client/server model may also mean that they’re more slow to write to than
|
||||
SQLite, which could make the global write lock more of a bottleneck. This is something that will need to be monitored
|
||||
as the system grows.
|
||||
|
||||
That said, full global locking is likely unnecessary for most real-world workloads. The database tables in Bugsink that
|
||||
are involved in the event ingestion process are already partitioned by project, and most other tables are as well. This
|
||||
allows for a project-level global write-lock strategy for these databases, which would allow for more parallelism than
|
||||
SQLite’s global write lock.
|
||||
|
||||
### Conclusion
|
||||
|
||||
Bugsink’s transaction model is designed to be simple, stable, and efficient. By embracing SQLite’s limitations and
|
||||
building around them, the system avoids many of the pitfalls that can come with more complex transaction models.
|
||||
|
||||
The model is built around the idea of a single writer at a time, which simplifies the system and ensures that writes
|
||||
are always consistent. This approach is particularly well-suited to the event-processing nature of Bugsink, where most
|
||||
writes are sequential and can be handled in a single transaction.
|
||||
|
||||
The model has been successfully extended to support MySQL and Postgres, with only minimal changes required. The core
|
||||
principles of the model remain the same, and the system continues to operate efficiently and predictably.
|
||||
|
||||
If you’re considering using SQLite in a production system, or if you’re looking for a simple, reliable transaction model
|
||||
for your application, Bugsink’s approach is a good place to start.
|
||||
|
||||
[About](https://www.bugsink.com/about/)
|
||||
|
||||
[Terms](https://www.bugsink.com/terms-and-conditions/) [Privacy](https://www.bugsink.com/privacy-policy/) [Cookies](https://www.bugsink.com/privacy-policy/#cookies) [LinkedIn](https://www.linkedin.com/company/bugsink)
|
||||
|
||||
[Discord](https://discord.gg/6Af6Yzz77C) [🇪🇺 Made & Hosted in the EU](https://www.bugsink.com/about/)
|
||||
File diff suppressed because it is too large.
Load diff
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://sqlite.org/forum/info/117c91891cf7ac15","title":"WAL mode speed vs normal comparison - SQLite User Forum","description":"WAL is about concurrency, not speed. How could it be faster, for a single connection? Has to potentially re-assemble a table (or index) pages ...WAL journal and threading modewal checkpointing very slowMore results from sqlite.org","position":1},{"url":"https://javascript.plainenglish.io/stop-the-sqlite-performance-wars-your-database-can-be-10x-faster-and-its-not-magic-156022addc75","title":"Stop the SQLite Performance Wars: Your Database Can Be 10x Faster ...","description":"# Stop the SQLite Performance Wars: Your Database Can Be 10x Faster (and it’s not magic!) ✨🚀\n## The Great Showdown: Rollback vs. The WAL Wizardry\n- **With WAL:** The exact same test was completed in a blistering **568 milliseconds**! 💥\n\n## Get Rogerio Amorim’s stories in your inbox\n```\nPRAGMA journal_mode = WAL;\nPRAGMA synchronous = NORMAL;\n.timer on\nBEGIN TRANSACTION;\n-- Run the exact same batch of INSERTs or UPDATEs from the previous test.\nEND TRANSACTION;\n.timer off\n```","position":2},{"url":"https://www.reddit.com/r/sqlite/comments/1ecjvst/wal_mode_sqlite3_bulk_updatesinserts/","title":"WAL Mode, SQLite3 Bulk updates/inserts : r/sqlite - Reddit","description":"WAL mode is slower than JOURNAL_MODE=DELETE for inserts. WAL stands for Write Ahead Log. not perform the same thing because another process ...Sqlite wal mode reliable for multiple writers without readers?Concurrency when writing data into SQLite? : r/golangMore results from www.reddit.com","position":3},{"url":"https://www.youtube.com/watch?v=qf0GqRz-c74","title":"SQLite's WAL mode is fast fast - YouTube","description":"Want to learn more SQLite? Check out the full course: https://highperformancesqlite.com. Get your free SQLite reference guide: ...","position":4},{"url":"https://superuser.com/questions/1938008/why-is-sqlite-wal-mode-so-much-faster-than-default-delete-mode-for-concurrent-wr","title":"mysql - Why is SQLite WAL mode so much faster than default DELETE ...","description":"The write performance improved drastically, almost by a factor of 4 or 5, and the disk activity dropped significantly. I understand that WAL ...","position":5},{"url":"https://github.com/cashubtc/nutshell/issues/907","title":"SQLite: enable WAL mode and busy_timeout for concurrent write ...","description":"# SQLite: enable WAL mode and busy_timeout for concurrent write performance#907\n## Problem\n```\n2026-02-25 19:27:31 | ERROR | cashu.mint.app:catch_exceptions:107 | Exception: failed to acquire database lock on None after 5s and 1 trials (1772047603357)\n2026-02-25 19:27:32 | ERROR | cashu.core.db:connect:243 | Error in session trial: 1 (1772047652030): proofs already spent\n2026-02-25 19:27:32 | ERROR | cashu.mint.db.write:_verify_spent_proofs_and_set_pending:84 | Failed to set proofs pending: proofs already spent\n```","position":6,"category":"github"}]},"id":"01a08313-ab43-724e-82f5-1e62c6d634f6","creditsUsed":2}
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://www.sqlite.org/wal.html","title":"Write-Ahead Logging - SQLite","description":"# 1. Overview\n4. ~~It is not possible to open [read-only WAL databases](https://sqlite.org/wal.html#readonly).\nThe opening process must have write privileges for \" `-shm`\"\n[wal-index](https://sqlite.org/walformat.html#shm) shared memory file associated with the database, if that\nfile exists, or else write access on the directory containing\nthe database file if the \" `-shm`\" file does not exist.~~\nBeginning with [version 3.22.0](https://sqlite.org/releaselog/3_22_0.html) (2018-01-22), a read-only\nWAL-mode database file can be opened if\nthe `-shm` and `-wal` files\nalready exist or those files can be created or the\n[database is immutable](https://sqlite.org/uri.html#uriimmutable).\n\n# 7. Implementation Of Shared-Memory For The WAL-Index\nleading to database corruption.\n\nthink this is a major concern since the wal-index rarely exceeds\n\n# 11. The WAL-Reset Bug\n## 11.1. Bug Details\n6. Later when a third checkpoint occurs, the third checkpoint skips all\nor part of the transaction that was written in step 3. Thus parts of\nthe transaction from step 3 never reach the database file, and the\ndatabase file goes corrupt.\n\n## 11.2. Low Probability Of Occurrence\nSo much so that the SQLite developers were unable","position":1},{"url":"https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database","title":"SQLite 3 WAL mode multiple processes frequently corrupting ...","description":"This seems to mostly occur if a process crashed after having opened a connection (doesn't matter if it's opened with a SQLITE_OPEN_READONLY flag ...Is it safe to delete sqlite's WAL file? - Stack OverflowHow safe is SQLite WAL on power failures? - Stack OverflowMore results from stackoverflow.com","position":2},{"url":"https://www.sqlite.org/walformat.html","title":"WAL-mode File Format - SQLite","description":"of the WAL-index are deliberately omitted since those details\n\nwhen it pertains to WAL mode processing.\n\n# 1. Files On Disk\n## 1.3. The Wal-Index or \"-shm\" file\nclient to connect to a quiescent database will normally truncate the In fact, if there were a mechanism by which SQLite could tell the it in cache memory, SQLite would use that mechanism to avoid any","position":3},{"url":"https://avi.im/blag/2025/sqlite-wal-checksum/","title":"PSA: SQLite WAL checksums fail silently and may lose data - blag","description":"SQLite WAL has checksums, but on corruption it drops all the data and does not raise error.","position":4},{"url":"https://sqlite.org/forum/info/47107ab818977549?t=h","title":"How exactly does corruption happen during WAL checkpoint? - SQLite","description":"# How exactly does corruption happen during WAL checkpoint?\n### (1) By esiy ( [tempacc423513](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=tempacc423513)) on 2024-02-02 08:57:47 [[source]](https://sqlite.org/forum/forumpost/47107ab818977549?raw)\n```\nOne of the instances mentioned in the docs [1] when it comes to WAL and DB corruption is (section 3.1):\n\nSTATEMENT A:\n\n\"In WAL mode, the only time that a failed sync operation can cause database corruption is during a checkpoint operation.\"\n\nThe checkpointing itself is described in the docs [2] as a couple of syncs (section 4.3):\n- first of WAL itself; prior to the merging the WAL records with the DB; and\n- then of the DB; prior to resetting the WAL.\n\nHowever, also in the docs [3] regarding performance considerations (section 2.3), it is pointed out that despite the checkpointer attempting \"as many sequential page writes\" that are interspersed by \"many seek operations\", even when \"a separate thread\" is used for checkpointing (so it does not happen with the commit that got it past WAL limit), then the thread \"that is doing database queries and updates will never block on a sync operation.\" Concluding that:\n\nSTATEMENT B:\n\n\"The downside to this configuration is that transactions are no longer durable and might rollback following a power failure or hard reset.\"\n\nSo, *other than* the loss of durability, what is meant by the \"corruption\" in STATEMENT A above and how exactly does it occur?\n\nThanks anyone who helps me not to go read through the code to figure this out.\n\n[1] https://www.sqlite.org/howtocorrupt.html\n[2] http://www.sqlite.org/draft/fileformat2.html#walformat\n[3] https://www.sqlite.org/wal.html\n```\n\n### (2) By Dan Kennedy ( [dan](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=dan)) on 2024-02-02 10:54:42 in reply to [1](https://sqlite.org/forum/forumpost/47107ab818?t=h) [[link]](https://sqlite.org/forum/forumpost/39139916c802d571?t=h) [[source]](https://sqlite.org/forum/forumpost/39139916c802d571?raw)\nAnd then may overwrite, truncate or delete the wal file. If at that point the OS crashes, or the power fails, and the sync operation was not implemented correctly, someLine truncated
|
||||
@@ -0,0 +1,108 @@
|
||||
{
|
||||
"process_id": "research-262-r1",
|
||||
"issue": 262,
|
||||
"round": 1,
|
||||
"stage": "ADVERSARIAL",
|
||||
"title": "sqlite WAL performance in concurrent Python applications (acceptance-test question, repo-specific)",
|
||||
"method_note": "New searches this stage (6 firecrawl queries, 4 full-page scrapes) targeted EXCLUSIVELY at counter-evidence to the emerging preferred approach inferred from DEFINE + INWARD + OUTWARD_READING: 'WAL mode + per-connection PRAGMA stack (busy_timeout, synchronous=NORMAL) + BEGIN IMMEDIATE + retry, validated by a pytest(-benchmark) acceptance test over Rune's multi-process topology.' Sources S1-S11 from OUTWARD_READING are referenced by ID; new adversarial sources are A1-A7. No advocacy for the preferred approach is included, per stage contract.",
|
||||
"preferred_approach_under_attack": "Enable WAL on Rune's SQLite databases; apply a hardened PRAGMA stack (busy_timeout, synchronous=NORMAL, wal_autocheckpoint) on every fresh per-call connection; use BEGIN IMMEDIATE for known-write transactions; retry on SQLITE_BUSY; validate with a pytest-based multi-process acceptance test (pytest-benchmark for perf assertions) asserting checkpoint progress after stale-reader release.",
|
||||
"attacks": [
|
||||
{
|
||||
"id": "X1",
|
||||
"target": "Core premise: WAL improves Rune's concurrency/performance",
|
||||
"attack": "WAL does not help Rune's actual bottleneck and may regress writes. (a) WAL adds an extra copy of every committed page (write amplification): commits go to the WAL AND must later be copied back to the main DB by checkpoints, so write throughput can be LOWER than journal_mode=DELETE for insert-heavy workloads (A2 reddit r/sqlite; A3 sqlite.org/forum 117c91891cf7ac15 'WAL is about concurrency, not speed'). (b) OUTWARD_READING's own S3 found WAL did NOT raise the concurrent-write ceiling (~500 simultaneous inserts failed identically with and without WAL, O8) — the repo's own workload (per-call fresh connections writing, I2/I4) is exactly the write-heavy multi-writer case WAL cannot scale: exactly one writer at a time (S1/O1). (c) S4's production incident (O9) shows multi-process writers on shared storage losing committed orders even in WAL. If Rune's pain is writer/writer contention, WAL is not the treatment and the acceptance test built around WAL success criteria measures the wrong thing.",
|
||||
"severity": "HIGH",
|
||||
"sources": ["A2", "A3", "S3/O8", "S1/O1", "S4/O9"]
|
||||
},
|
||||
{
|
||||
"id": "X2",
|
||||
"target": "busy_timeout as the primary SQLITE_BUSY mitigation",
|
||||
"attack": "busy_timeout has documented holes that retry logic alone does not patch. (a) In deferred transactions, a read that upgrades to write later gets SQLITE_BUSY IMMEDIATELY, ignoring busy_timeout entirely — the classic fix is BEGIN IMMEDIATE for known-write transactions (A4 berthub.eu, confirmed by sqlite.org forum + Simon Willison notes; also HN 45781519). This contradicts any design that applies busy_timeout and expects writers to queue: only BEGIN IMMEDIATE transactions actually wait. (b) S6's diagnostic runbook: PASSIVE checkpoints ALWAYS return busy=0 — a monitoring/assertion scheme reading the busy column will systematically report 'no contention' during starvation. (c) WAL checkpoints bypass the busy handler in some paths: concurrent checkpoint attempts return SQLITE_BUSY without invoking the busy handler at all (S2/O6), so connection-level busy_timeout does not help checkpoint coordination; explicit retry-at-app-level is mandatory, not optional. The preferred approach as stated ('set busy_timeout, retry') is insufficient; the test must distinguish deferred-upgrade BUSY (immediate, un-timed) from writer-queue BUSY (timed).",
|
||||
"severity": "HIGH",
|
||||
"sources": ["A4", "S2/O6", "S6/O11"]
|
||||
},
|
||||
{
|
||||
"id": "X3",
|
||||
"target": "Per-connection PRAGMA stack + fresh connections per call (Rune's topology, reinforced by S8/O14)",
|
||||
"attack": "The fresh-connection-per-call pattern is itself the cost center, and the preferred approach bakes it in rather than questioning it. Connections are expensive (they correspond to opening the file); reopening per call has measurable overhead (A5 SO 3747232; HN 44530518 'opening and closing SQLite connections is expensive... reuse is much faster'). A simpler alternative that the preferred approach does not consider: a single dedicated DB-writer thread fed by a queue (community-standard answer, S11/O18) or a persistent connection/pool per process eliminates BOTH the per-connect PRAGMA stack cost AND the sqlite-vec per-connection extension-load cost (curator.py:695, I3/I5 mapping) that the acceptance test would otherwise just accept as fixed overhead. The test design risk: benchmarking the fresh-connection pattern against itself proves nothing; the baseline must include the single-writer-queue alternative or the acceptance test endorses the incumbent by construction.",
|
||||
"severity": "MEDIUM-HIGH",
|
||||
"sources": ["A5", "S11/O18", "I3 curator.py:695"]
|
||||
},
|
||||
{
|
||||
"id": "X4",
|
||||
"target": "pytest-benchmark as the performance-assertion harness (O17)",
|
||||
"attack": "pytest-benchmark is a poor fit for the acceptance test the pipeline is converging on. (a) It benchmarks single functions with per-call calibration — a multi-process concurrency scenario (N writer processes + stale reader + checkpoint observation) is not a callable you can benchmark; it would need artificial wrapper functions that distort the measurement. (b) It AUTO-DISABLES under pytest-xdist (confirmed in S10 docs, O17) — i.e., the canonical pytest parallelization layer silently disables the benchmarking layer, so any attempt to parallelize the concurrency test kills the perf assertions. (c) Timing assertions for checkpoint-progress-after-release are deadline/liveness properties, not throughput medians; a plain wall-clock deadline assertion in a normal test is more honest and simpler. The simpler alternative: no pytest-benchmark at all; assert deadlines and WAL-size bounds with time.monotonic() + PRAGMA wal_checkpoint(PASSIVE) counters.",
|
||||
"severity": "MEDIUM-HIGH",
|
||||
"sources": ["S10/O17"]
|
||||
},
|
||||
{
|
||||
"id": "X5",
|
||||
"target": "Silent data-loss failure mode the preferred approach does not address",
|
||||
"attack": "WAL's rolling-checksum recovery silently DROPS committed frames on any checksum mismatch and never raises an error: the scan stops at the first invalid checksum, mxFrame is set to the last valid commit frame, and the data after it is discarded at the next checkpoint+truncate (A1 avi.im, quoting sqlite.org/walformat.html#recovery and wal.c/walDecodeFrame; corroborated by Lobsters discussion). Preconditions match Rune: unclean shutdown mid-WAL-write (crashed background task, I4 auto_tasks.py) + wal-index rebuild on next open. Separately, S4/O9 documents real order loss in production with multi-process writers in WAL. An acceptance test that only asserts throughput and checkpoint progress would PASS while this failure mode exists. Any test claiming 'WAL acceptance' must include a crash/kill-during-write scenario (SIGKILL a writer mid-transaction, reopen, verify committed data present or cleanly absent — no silent truncation of acknowledged commits).",
|
||||
"severity": "HIGH",
|
||||
"sources": ["A1", "S4/O9", "S6"]
|
||||
},
|
||||
{
|
||||
"id": "X6",
|
||||
"target": "Multi-process same-host WAL stability claims (O4 'validates repo topology')",
|
||||
"attack": "Field reports contradict the safe-multi-process narrative. SO 46023203 (A6): recurring 'malformed database' reports after adopting WAL with multiple processes including read-only openers, suspected -shm/-wal state mismatch after a process crash; accepted answer links it to a Python client crashing inside an open transaction while a concurrent process queries, resolved only by guaranteeing transaction close on crash. Rune's auto_tasks.py background jobs (I4) are exactly the crash-prone multi-process population. sqlite.org/wal.html itself (S1) lists residual BUSY/corruption surfaces (recovery after crashed connection, exclusive locking modes) that the preferred approach's PRAGMA stack does not touch. If Rune's processes can die mid-transaction (they can — background jobs), the acceptance test needs process-kill coverage, and the 'WAL is safe for multi-process same-host' premise is contingent, not guaranteed.",
|
||||
"severity": "MEDIUM",
|
||||
"sources": ["A6", "S1/O4", "I4"]
|
||||
},
|
||||
{
|
||||
"id": "X7",
|
||||
"target": "BEGIN IMMEDIATE + retry as complete write-contention strategy",
|
||||
"attack": "BEGIN IMMEDIATE shifts the failure from 'immediate BUSY on upgrade' to 'unbounded wait under the write lock' — with long write transactions, every other writer blocks up to busy_timeout and then fails anyway; retry-with-backoff under sustained multi-writer load produces livelock-ish behavior (repeated timeout + retry storms) that no source in the pipeline has bounded. A6's asker explicitly could not coordinate two writer processes without IPC-level coordination and considered falling back to journal_mode=DELETE. The simpler alternative (single serialized writer, X3) eliminates the entire BEGIN IMMEDIATE/retry/timeout tuning problem. The acceptance test as sketched (O13 Given/When/Then) contains no sustained-contention scenario that would surface retry-storm behavior.",
|
||||
"severity": "MEDIUM",
|
||||
"sources": ["A4", "A6", "X3"]
|
||||
},
|
||||
{
|
||||
"id": "X8",
|
||||
"target": "S8 (productionhardening.org) quantitative claims — quarantine confirmed",
|
||||
"attack": "OUTWARD_READING flagged S8's numbers (40-60% faster writes with synchronous=NORMAL, 15-30% FULL penalty, 256MB mmap) as unverified; this stage's searches surfaced ZERO corroboration (no independent source repeats these figures), and the site remains anonymous. Adversarial recommendation: strike S8's numbers from any synthesis; keep only its mechanism-level advice that is independently confirmed (per-connection PRAGMA application is real but see X3 for its cost).",
|
||||
"severity": "MEDIUM",
|
||||
"sources": ["S8/O15"]
|
||||
}
|
||||
],
|
||||
"simpler_alternatives_found": [
|
||||
{
|
||||
"id": "ALT1",
|
||||
"alternative": "Single dedicated DB-writer thread/queue per process, or fully serialized writes (Bugsink-style single-writer architecture)",
|
||||
"evidence": "S11/O18 (community-accepted Python pattern), A7 Bugsink post (production system 'built around SQLite's concurrency model: for writes, a global lock; for reads, snapshot isolation' — no lock errors, no retry logic, no busy_timeout tuning), X3/X7 analysis",
|
||||
"cost_vs_preferred": "Removes BEGIN IMMEDIATE/retry/timeout tuning entirely; removes most SQLITE_BUSY surface; costs one queue + writer thread per process (vs per-call connections today)"
|
||||
},
|
||||
{
|
||||
"id": "ALT2",
|
||||
"alternative": "Plain deadline assertions (time.monotonic + PRAGMA wal_checkpoint(PASSIVE) tuple sampling) instead of pytest-benchmark",
|
||||
"evidence": "S10/O17 xdist auto-disable + single-function model; S6/O12 prescribe exactly the PASSIVE-tuple sampling pattern as the diagnostic primitive",
|
||||
"cost_vs_preferred": "Removes a dependency and a misleading harness; loses automatic regression tracking and JSON comparison reporting"
|
||||
},
|
||||
{
|
||||
"id": "ALT3",
|
||||
"alternative": "Persistent per-process connections (or small pool) instead of fresh connections per call",
|
||||
"evidence": "A5 (SO 3747232, HN 44530518: connect/close is expensive; reuse much faster); eliminates repeated sqlite-vec load cost (I3 curator.py:695)",
|
||||
"cost_vs_preferred": "Connection lifecycle becomes explicit app state (fork-safety, stale-connection recovery must be handled); but PRAGMA stack is applied once, not per call"
|
||||
},
|
||||
{
|
||||
"id": "ALT4",
|
||||
"alternative": "Question the WAL mandate itself: if Rune's workload is write-dominated multi-process, journal_mode=DELETE with a single writer path may be equal or faster (WAL adds write amplification)",
|
||||
"evidence": "A2 (WAL slower than DELETE for bulk inserts), A3 (WAL is about concurrency, not speed), S3/O8 (WAL did not raise concurrent-write ceiling)",
|
||||
"cost_vs_preferred": "Loses reader/writer concurrency (readers block during writes) — only viable if Rune's actual contention is writer/writer, which the acceptance test must MEASURE before assuming"
|
||||
}
|
||||
],
|
||||
"negative_results": [
|
||||
"WAL did not raise the concurrent-write ceiling in the closest public test harness (~500 simultaneous single-row inserts, S3/O8) — empirical negative on the 'WAL improves concurrent writes' premise.",
|
||||
"WAL mode measured SLOWER than journal_mode=DELETE for insert/bulk-update workloads (A2, r/sqlite) — write amplification is a real regression risk for write-dominated workloads.",
|
||||
"busy_timeout is silently ignored for deferred-transaction upgrade contention (A4) — a 'set timeout and retry' strategy fails in exactly the mixed read-then-write pattern common in application code.",
|
||||
"PASSIVE checkpoint busy column is always 0 (S6) — contention-monitoring schemes built on it report zero contention during active starvation (measurement negative).",
|
||||
"pytest-benchmark auto-disables under pytest-xdist (S10) — the two layers of the proposed harness are mutually exclusive in the parallel case the test needs."
|
||||
],
|
||||
"limitations_of_stage": [
|
||||
"Adversarial scope was counter-evidence search, not measurement: no benchmarks were run; all quantitative claims are source-attributed, and the strongest ones (A1, A2, A4) are mechanism-level rather than Rune-workload-specific.",
|
||||
"A2 (Reddit) and A6 (SO, 2-score answer) are community-sourced; used as documented failure reports, not as measurements.",
|
||||
"A7 (Bugsink) is a single vendor's architecture post for an event-processing workload; its single-writer pattern is evidence of a viable simpler alternative, not proof it fits Rune's TUI + background-job workload.",
|
||||
"S4's incident attribution remains contested (per OUTWARD_READING); used here only as a failure-mode inventory, not as a WAL-specific indictment.",
|
||||
"The 'preferred approach' attacked here was INFERRED from prior-stage artifacts (DEFINE capsule text was truncated; no explicit preferred_approach field existed), so attacks target the approach most consistent with all four completed stages. If the DEFINE artifact specifies a different preferred approach, X1-X8 must be re-aimed."
|
||||
],
|
||||
"next_stage_hint": "INNOVATION: (1) decide workload characterization FIRST — the acceptance test's first experiment should measure Rune's actual reader/writer vs writer/writer contention split before asserting any WAL benefit (X1/ALT4); (2) add a SIGKILL-mid-write crash scenario with post-reopen committed-data verification (X5/X6); (3) replace pytest-benchmark perf assertions with deadline assertions (X4/ALT2); (4) put the single-writer-queue alternative (ALT1/ALT3) into the test matrix as a baseline, not just the WAL PRAGMA stack."
|
||||
}
|
||||
@@ -0,0 +1,230 @@
|
||||
{
|
||||
"process_id": "research-262-r1",
|
||||
"issue": 262,
|
||||
"round": 1,
|
||||
"stage": "OUTWARD_READING",
|
||||
"title": "sqlite WAL performance in concurrent Python applications (acceptance-test question, repo-specific)",
|
||||
"method_note": "Primary sources fetched and read in full this stage plus in the prior partially-completed OUTWARD_READING session (ses_-ffe5f7d08ef0effe7822prgaw, which read S1-S3). No new search queries generated, per stage contract. Claims below carry source IDs (S1-S10); repo claims from INWARD (I1-I5) are referenced for mapping only.",
|
||||
"sources": {
|
||||
"S1": {
|
||||
"url": "https://sqlite.org/wal.html",
|
||||
"type": "official_docs",
|
||||
"authority": "high (canonical SQLite documentation)",
|
||||
"read_in": "prior session (ses_-ffe5f7d08ef0effe7822prgaw); claims verified against that session's extraction",
|
||||
"limitations": ["Documents C-library behavior; Python sqlite3 module wraps the same library so semantics carry over, but Python-side ergonomics (isolation_level, implicit transactions) are not covered by this source"]
|
||||
},
|
||||
"S2": {
|
||||
"url": "https://sqlite.org/c3ref/wal_checkpoint_v2.html",
|
||||
"type": "official_docs",
|
||||
"authority": "high (canonical SQLite C API reference)",
|
||||
"read_in": "prior session",
|
||||
"limitations": ["C API reference; PRAGMA wal_checkpoint exposes the same tuple (busy, log, checkpointed) per S5, but the C-API framing (pnLog/pnCkpt out-params) is not literally what Python callers see"]
|
||||
},
|
||||
"S3": {
|
||||
"url": "https://github.com/joedougherty/sqlite3_concurrent_writes_test_suite",
|
||||
"type": "repro_test_suite_github",
|
||||
"authority": "medium (small public repo: 22 stars, 3 forks, 20 commits; author's own caveats are candid)",
|
||||
"read_in": "prior session (README)",
|
||||
"limitations": ["No busy_timeout/timeout configuration", "Write-only contention; no reader/writer mix", "No WAL-size or checkpoint observation", "Small scale (ceiling found ~500 simultaneous single-row inserts)", "Tests threads/processes against one DB but not a separate-process RW+RO mix"]
|
||||
},
|
||||
"S4": {
|
||||
"url": "https://raw.githubusercontent.com/necat101/sqlite-deployment-safety-lab/master/README.md",
|
||||
"type": "repro_lab_github",
|
||||
"authority": "medium (README reports validated experiment output; experiments are Python scripts committed in repo; grounded in a real production incident via HN thread #47637353)",
|
||||
"limitations": ["README summarizes results; per-experiment scripts were not individually read this stage", "Experiment 2 note is the author's own: controlled tests show NO data loss without SIGTERM/unhandled-SQLITE_BUSY", "Production-incident generalization comes from one anecdotal incident (Ultrathink.art)"]
|
||||
},
|
||||
"S5": {
|
||||
"url": "https://www.sqliteforum.com/p/checkpoint-algorithms-and-wal-performance",
|
||||
"type": "engineering_writeup_newsletter",
|
||||
"authority": "medium-low (Substack-style explainer 'SQLite Forum' by Jenny Muralidharan, May 2026; technically consistent with S1/S2 but is not sqlite.org)",
|
||||
"limitations": ["Not an official SQLite source despite the domain name", "No measurements of its own; all claims qualitative", "Minor imprecision: says auto-checkpoint 'happens in the background by a reader connection' — S1 states the COMMITTING thread runs it (this source's framing is wrong per S1)"]
|
||||
},
|
||||
"S6": {
|
||||
"url": "https://github.com/mouadja02/skills/blob/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md",
|
||||
"type": "diagnostic_runbook",
|
||||
"authority": "medium (operational runbook; explicitly separates sourced facts from original operational guidance; cites sqlite.org docs and real issue trackers)",
|
||||
"limitations": ["Operational recommendations (alert ratios, sample counts, escalation order) are author-declared 'not SQLite guarantees'", "Issue references (Syncthing #10559, OpenCode #37495, Codex #30517) were not independently opened this stage"]
|
||||
},
|
||||
"S7": {
|
||||
"url": "https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo",
|
||||
"type": "engineering_writeup_repro",
|
||||
"authority": "medium-low (individual practitioner post, Jul 2026, with one substantive expert comment; methodology is coherent and cites sqlite.org/wal.html for the end-mark mechanism)",
|
||||
"limitations": ["No raw numbers published; claims are about the drill design, not measured results", "Single author, no peer review"]
|
||||
},
|
||||
"S8": {
|
||||
"url": "https://productionhardening.org/wal-optimization-concurrency-tuning/",
|
||||
"type": "engineering_writeup_reference_site",
|
||||
"authority": "low-medium (anonymous static Eleventy site, no named authors, no verifiable credentials; content is technically coherent and internally consistent with S1, but unattributed)",
|
||||
"limitations": ["Credibility unverified — no author, organization, or provenance for 'validated against SD-card degradation' claims", "Specific numbers (40-60% faster writes with synchronous=NORMAL, 15-30% penalty for FULL, 256MB mmap suggestion) are unattributed and uncorroborated", "Safe to use for mechanism-level claims that echo S1; do NOT cite its benchmark numbers without corroboration"]
|
||||
},
|
||||
"S9": {
|
||||
"url": "https://dev.to/lumin-playstar/sqlite-wal-mode-10x-performance-for-python-apps-4ic",
|
||||
"type": "tutorial_blog_low_authority",
|
||||
"authority": "low (individual tutorial, Mar 2026, 0 comments; headline '10x' claim is unsubstantiated)",
|
||||
"limitations": ["No benchmarks, no methodology, no workload description behind the '10x' figure", "Contains a factual error: claims auto-checkpoint runs 'in the background by a reader connection' — contradicts S1 (committing thread) and S2", "Suggested pattern 'conn.commit() after PRAGMA journal_mode=WAL' is unnecessary/confused", "Code also deletes -wal/-shm files directly in cleanup — flagged unsafe by S6's rules", "Use only as evidence of common developer belief, not as a factual source"]
|
||||
},
|
||||
"S10": {
|
||||
"url": "https://pypi.org/project/pytest-benchmark/ + https://pytest-benchmark.readthedocs.io/en/latest/ (index)",
|
||||
"type": "tooling_docs",
|
||||
"authority": "high (official docs + PyPI page for the canonical pytest benchmarking plugin; v5.3.0, BSD-2-Clause, production/stable)",
|
||||
"limitations": ["Micro-benchmark oriented: 'benchmarks functions and only that'; whole-program or multi-process scenarios need wrapper functions or per-call benchmarking", "Auto-disables under pytest-xdist — concurrency-related caveat for a concurrency test harness", "Docs page read was the index; calibration/comparison detail lives on sub-pages"]
|
||||
},
|
||||
"S11": {
|
||||
"url": "https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency (fetched via Stack Exchange API, question + top 4 answers)",
|
||||
"type": "qa_forum",
|
||||
"authority": "medium for community practice (Q score 115; top answer 214), low as factual source",
|
||||
"limitations": ["Q&A from 2008-era threading context; predates WAL-era defaults and modern Python sqlite3 behavior", "Community answers, not documentation"]
|
||||
}
|
||||
},
|
||||
"claims": [
|
||||
{
|
||||
"id": "O1",
|
||||
"source": "S1",
|
||||
"claim": "In WAL mode there is exactly ONE writer at a time (single WAL file); readers do not block writers and vice versa, but writer/writer contention remains and SQLITE_BUSY can still occur in WAL mode (exclusive-locking-mode holders, last-connection cleanup, crashed-connection recovery).",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Directly bounds what the issue-262 acceptance test can promise: WAL improves reader/writer concurrency, not writer/writer throughput."
|
||||
},
|
||||
{
|
||||
"id": "O2",
|
||||
"source": "S1",
|
||||
"claim": "Each reader has an 'end mark' (snapshot per read transaction); a checkpoint must stop at any reader's end mark, so a long-running read transaction prevents checkpoint progress and can starve checkpoints, growing the WAL unbounded (§2.2, §6).",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Core failure mode the acceptance test should reproduce: one forgotten reader -> unbounded WAL growth."
|
||||
},
|
||||
{
|
||||
"id": "O3",
|
||||
"source": "S1",
|
||||
"claim": "WAL read performance degrades as the WAL grows; default auto-checkpoint triggers at 1000 pages (~4MB) and runs on the COMMITTING thread, producing mostly-fast commits with occasional much-slower commits (§2.3).",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Gives the acceptance test a measurable tail-latency signal (checkpoint stall on committing thread) and a WAL-size regression metric."
|
||||
},
|
||||
{
|
||||
"id": "O4",
|
||||
"source": "S1",
|
||||
"claim": "WAL mode is PERSISTENT across connections (set once on any connection, §3.3); mitigations for checkpoint starvation are reader gaps or manual RESTART/TRUNCATE checkpoints (with reader-blocking downside); WAL has constraints: same-host only (shared-memory wal-index), not for network filesystems, and transactions >~100MB are a poor fit.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "task_gate.py:41-44 setting journal_mode=WAL once is sufficient for all processes on the same host; validates repo topology, bounds test scope (multi-process same-host only)."
|
||||
},
|
||||
{
|
||||
"id": "O5",
|
||||
"source": "S1",
|
||||
"claim": "WAL-reset data-race bug affected SQLite 3.7.0-3.51.2 (fixed 3.51.3, 2026-03-13; backports 3.44.6/3.50.7); requires >=2 connections in separate threads/processes writing/checkpointing at the same instant.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Rune's shape (multi-process writers + checkpoints) matches the bug's preconditions; acceptance test / recommendation should pin a minimum SQLite version."
|
||||
},
|
||||
{
|
||||
"id": "O6",
|
||||
"source": "S2",
|
||||
"claim": "Checkpoint modes: PASSIVE (default; never blocks, may finish incomplete), FULL (blocks until all readers on newest snapshot; blocks new writers), RESTART (FULL + next writer restarts WAL), TRUNCATE (RESTART + WAL to 0 bytes); all checkpoints take an exclusive checkpoint lock so a concurrent checkpoint from another process returns SQLITE_BUSY without invoking the busy-handler; the (busy, log, checkpointed) tuple reports frames.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "PRAGMA wal_checkpoint(PASSIVE) is the non-blocking observation primitive the acceptance test can use to assert checkpoint progress/WAL health."
|
||||
},
|
||||
{
|
||||
"id": "O7",
|
||||
"source": "S3",
|
||||
"claim": "Closest public prior-art acceptance harness: pytest + multiprocessing.Pool spawning N single-row-insert processes against one sqlite3 DB; failures surface as sqlite3.OperationalError 'database is locked', starting around 500 simultaneous inserts (default journal mode, no busy_timeout).",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Structural template for the issue-262 test (pytest + multiprocessing + row-count assertion + lock-error detection)."
|
||||
},
|
||||
{
|
||||
"id": "O8",
|
||||
"source": "S3",
|
||||
"claim": "Author's key finding: 'WAL mode mostly helps with concurrent reads. My testing showed I wasn't able to successfully insert more rows in parallel using WAL mode than without.' — WAL did not raise the concurrent-WRITE ceiling in that harness.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Corroborates O1 empirically; the acceptance test must NOT assert that WAL increases multi-writer throughput; differentiate on reader/writer mix instead."
|
||||
},
|
||||
{
|
||||
"id": "O9",
|
||||
"source": "S4",
|
||||
"claim": "Production incident (Ultrathink.art, via HN #47637353): 3 containers on a shared Docker volume accessed the same SQLite WAL DB; 2 orders lost after 11 overlapping Kamal deploys. Community consensus in thread: WAL allows concurrent readers but NOT concurrent writers; overlapping deploys + SIGTERM mid-transaction or unhandled SQLITE_BUSY cause real data loss; raw `cp` of a live DB can corrupt backups (use .backup API); deploy serialization is mandatory.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Failure-mode inventory for the acceptance test: multi-process writers on one DB, unhandled SQLITE_BUSY, SIGTERM mid-transaction."
|
||||
},
|
||||
{
|
||||
"id": "O10",
|
||||
"source": "S4",
|
||||
"claim": "Lab experiments (validated): Experiment 1 — 5 concurrent writer processes, 3 succeeded / 2 failed with lost writes, proving single-writer even in WAL; Experiment 2 — controlled overlapping processes show SQLite properly serializes writes and NO data is lost unless SIGTERM mid-transaction or unhandled SQLITE_BUSY; Experiment 3 — long-running readers block checkpoints and grow the WAL; Experiment 5 — busy_timeout 5000 makes writers wait up to 5s then fail with SQLITE_BUSY.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Executable repro patterns the acceptance test can adapt (esp. Exp 3 checkpoint-blocking and Exp 5 busy-timeout semantics)."
|
||||
},
|
||||
{
|
||||
"id": "O11",
|
||||
"source": "S5, S6",
|
||||
"claim": "Checkpoint mode semantics for practitioners: PASSIVE copies what it can without blocking (busy column always 0 — never mistake PASSIVE busy=0 for completion); FULL/RESTART/TRUNCATE guarantee completion but can block readers/writers; wal_autocheckpoint is a trigger threshold, not a guarantee that readers permit completion; production tuning commonly raises wal_autocheckpoint to 2000-10000 pages and schedules manual FULL checkpoints in low-traffic windows.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Directly informs both the acceptance-test assertions and any recommendation output (checkpoint cadence tuning for Rune)."
|
||||
},
|
||||
{
|
||||
"id": "O12",
|
||||
"source": "S6, S7",
|
||||
"claim": "Diagnostics pattern: sample PRAGMA wal_checkpoint(PASSIVE) tuple + WAL bytes + oldest-reader transaction age over time; a health check ('SELECT 1' green) says nothing about checkpoint progress; fix reader lifetimes (close iterators, bound transaction age) rather than looping aggressive TRUNCATE checkpoints; alert thresholds should be tied to disk budget/growth rate.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "The acceptance test can double as an operational diagnostic: assert checkpoint progress resumes within a deadline after the stale reader is released (exactly S6's prescribed regression test)."
|
||||
},
|
||||
{
|
||||
"id": "O13",
|
||||
"source": "S7",
|
||||
"claim": "Minimal starvation repro drill: connection A holds an open read transaction; connection B commits batches of writes for 60s; sample WAL bytes and checkpoint results every second; release A and observe checkpoint resume + WAL convergence. Gate form: Given one reader holds its transaction / When 10,000 writes commit / Then writes remain bounded, WAL growth alerts before disk budget / When reader closes / Then checkpoint progress resumes and WAL size converges.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Ready-made Given/When/Then skeleton for the issue-262 acceptance test."
|
||||
},
|
||||
{
|
||||
"id": "O14",
|
||||
"source": "S8",
|
||||
"claim": "Hardened connection pattern (echoes official PRAGMA docs): set PRAGMA stack on EVERY connection open (journal_mode=WAL, synchronous=NORMAL, busy_timeout, wal_autocheckpoint, cache_size, temp_store), read back and assert each value ('apply then assert'); use isolation_level=None + explicit BEGIN IMMEDIATE to acquire the write lock up front so contention fails fast and cleanly; wrap writers in retry with backoff.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Maps to Rune's per-call fresh-connection pattern (warm_router.py:76-935, curator.py): every connection must re-apply busy_timeout etc.; sqlite-vec per-connection load sits in the same setup path. Mechanism-level claims credible; specific numbers unverified."
|
||||
},
|
||||
{
|
||||
"id": "O15",
|
||||
"source": "S8",
|
||||
"claim": "Claimed failure-code matrix for WAL deployments: SQLITE_BUSY (writer-lock contention / blocked checkpoint), SQLITE_FULL (WAL exhausted disk), SQLITE_PROTOCOL (-shm contention across too many processes / stale lock), SQLITE_READONLY (directory not writable — WAL needs to create -wal/-shm siblings), SQLITE_IOERR / SQLITE_CORRUPT (storage failure; power loss during checkpoint on reordering storage).",
|
||||
"status": "PARTIALLY_VERIFIED",
|
||||
"relevance": "Failure modes worth encoding in the acceptance test (esp. SQLITE_BUSY residual cases, directory-writability precondition); provenance is an anonymous site — mechanism claims echo S1 but the matrix as a whole needs corroboration in ADVERSARIAL stage."
|
||||
},
|
||||
{
|
||||
"id": "O16",
|
||||
"source": "S9",
|
||||
"claim": "Common developer belief: enabling WAL yields '10x or even greater performance boost' for Python apps, especially writes and concurrent operations.",
|
||||
"status": "REFUTED_CONTEXT",
|
||||
"relevance": "The '10x' claim is unsubstantiated in-source (no benchmark/methodology), contains a factual error about auto-checkpoint running on a reader connection (contradicts S1: committing thread), and is empirically contradicted for concurrent WRITES by O8 (S3). Useful only as evidence that the acceptance test should measure, not assume, WAL gains."
|
||||
},
|
||||
{
|
||||
"id": "O17",
|
||||
"source": "S10",
|
||||
"claim": "pytest-benchmark provides a pytest fixture benchmarking any callable, with automatic calibration, comparison/regression tracking (--benchmark-compare, --benchmark-compare-fail), statistics, and JSON export; pedantic mode allows explicit rounds/iterations/setup. Caveats: benchmarks functions only (wrap code blocks), one function per test, and it auto-disables under pytest-xdist.",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Candidate harness for the acceptance test's performance assertions (per-call connection+sqlite-vec load cost, commit latency percentiles), with regression tracking."
|
||||
},
|
||||
{
|
||||
"id": "O18",
|
||||
"source": "S11",
|
||||
"claim": "Canonical Python-side concurrency answers: (a) per-thread connections hit 'database is locked' without WAL/busy_timeout; (b) passing a connection across threads raises ProgrammingError unless check_same_thread=False (then the app owns thread-safety); (c) recommended architectures are a single dedicated DB-writer thread fed by a queue (accepted answer), multiprocessing, or a pooling layer (SQLAlchemy).",
|
||||
"status": "CURRENT",
|
||||
"relevance": "Community-standard Python patterns; contrasts with Rune's multi-PROCESS per-call-connection topology, which none of these answers address — supporting the repo-specific gap the acceptance test targets."
|
||||
},
|
||||
{
|
||||
"id": "O19",
|
||||
"source": "S5, S9",
|
||||
"claim": "Both secondary sources repeat the incorrect claim that automatic checkpoints run 'in the background by a reader connection'.",
|
||||
"status": "REFUTED",
|
||||
"relevance": "Conflict resolved in favor of S1 (§2.3: the COMMITTING thread runs auto-checkpoints). Recorded so the ADVERSARIAL stage does not inherit the error via secondary sources."
|
||||
}
|
||||
],
|
||||
"mapping_to_repo": {
|
||||
"I1_rune_tui": "rune_tui.py:189 sniffs 'sqlite'/'OperationalError' in error messages — O1's residual-SQLITE_BUSY-in-WAL cases are what the TUI will surface; test should assert lock errors are user-visible/typed.",
|
||||
"I2_warm_router": "warm_router.py:76-935 opens fresh per-call connections mixing RW and file:...?mode=ro — O1 (single writer, readers never block), O14 (PRAGMA stack per connection), O2/O3 (readers hold end marks; per-call RO connections are short so starvation risk is from leaked/long iterators, not the per-call pattern itself).",
|
||||
"I3_curator": "curator.py:132-260 RO URI connections + RW connect — same mapping as I2; per-connect sqlite-vec load cost (curator.py:695 comment) is the performance axis S10/pytest-benchmark (O17) can measure.",
|
||||
"I4_auto_tasks": "auto_tasks.py background jobs = the 'other processes' in O5's data-race precondition and O9's overlapping-writer scenario; candidates for the multi-process writer pool in the acceptance test.",
|
||||
"I5_memory_store": "memory_store.py (sqlite-vec + FTS5 per connection) — per-connection extension load is connection-setup overhead to benchmark alongside WAL behavior (O17)."
|
||||
},
|
||||
"limitations_of_stage": [
|
||||
"Sources S1-S3 were read in a prior partially-completed OUTWARD_READING session and carried forward via that session's checkpoint (claims re-verified against the extraction text, not re-fetched).",
|
||||
"stackoverflow.com returned 403 to direct webfetch; question 393554 and top answers were retrieved via the official Stack Exchange API instead (full question + top 4 by score read).",
|
||||
"Secondary/low-priority discovery URLs not read (deliberately, scope control): charlesleifer.com post, theconsensus.dev WAL-reset reproducer, bencher.dev guide, syncthing forum thread, errcodes.dev, sqlfmt.app, coddy.tech, botmonster.com, deepwiki better-sqlite3, nitin-rachabathuni.com posts, acaciafund.org. All are corroboration candidates, none are load-bearing.",
|
||||
"S4's per-experiment Python scripts and S3's test files were not individually opened; README/claims-level reading only.",
|
||||
"S8 (productionhardening.org) credibility remains unverified (anonymous site); its quantitative claims are quarantined in O15 and flagged for ADVERSARIAL.",
|
||||
"No measurements were run this stage — this is a reading/extraction stage; all performance numbers cited come from sources, and the only external quantitative datapoint (S3's ~500-writer ceiling) is single-harness, single-machine."
|
||||
],
|
||||
"next_stage_hint": "ADVERSARIAL: strongest attack surfaces are (a) S8's unverified numbers, (b) S3's small-scale single-harness WAL-write finding vs O1's doc-level claim, (c) whether pytest-benchmark's micro-benchmark model fits a multi-process acceptance test at all (xdist auto-disable), (d) S9's 10x claim should be killed or corroborated by measurement in INNOVATION."
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{"type":"step_start","timestamp":1788905398746,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831221d7001INj5o9AxA","messageID":"msg_g001a0831204b30015PYufGjDD","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"96c8854018ff68999140dd458b2f5d8d0e3cb11c","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905411241,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312525b001kms07wLCB","messageID":"msg_g001a0831204b30015PYufGjDD","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"I'll start with the required skill search, and in parallel check session memory for prior context on this research process.","time":{"start":1788905411163,"end":1788905411239}}}
|
||||
{"type":"tool_use","timestamp":1788905411244,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"skill_search","callID":"call_61a89ba9088243caab59ec7e","state":{"status":"completed","input":{"query":"Adversarial research stage: seek evidence against a preferred technical approach (SQLite WAL for concurrency in Python), find failures, limitations, negative results, and simpler alternatives; deliverable is a structured adversarial.json stage artifact."},"output":"{\n \"status\": \"matched\",\n \"results\": [\n {\n \"skill_id\": \"xlsx-official\",\n \"name\": \"xlsx-official\",\n \"score\": 0.6173,\n \"reason\": \"The skill description matches these query terms: in, python, deliverable, is, artifact.\"\n },\n {\n \"skill_id\": \"firecrawl-search\",\n \"name\": \"firecrawl-search\",\n \"score\": 0.5646,\n \"reason\": \"The skill description matches these query terms: research, in, find, result.\"\n },\n {\n \"skill_id\": \"firecrawl-agent\",\n \"name\": \"firecrawl-agent\",\n \"score\": 0.4243,\n \"reason\": \"The skill description matches these query terms: structured, json.\"\n }\n ],\n \"loaded_skill_id\": null\n}","metadata":{"status":"matched","loadedSkillID":null,"truncated":false},"title":"Found 3 skills","time":{"start":1788905411240,"end":1788905411243}},"id":"prt_g001a083125262001hMmJSflZD","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831204b30015PYufGjDD"}}
|
||||
{"type":"tool_use","timestamp":1788905411515,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"memory","callID":"call_bfd0efbefebd4c32b3db47cb","state":{"status":"completed","input":{"operation":"search","query":"research 262 sqlite wal adversarial"},"output":"Found 10 matches (BM25-ranked, best first).\nA hit here is authoritative — use it even if a parallel/sibling query returned nothing.\nIf you need the FULL body (snippets are truncated), Read the path.\nIf you need an EXACT literal (a connection string, port, token, full command line, path) and the snippet/body only paraphrases or partially shows it, the curated memory may have dropped the precise form — query the history tool for the original message, which holds it verbatim.\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN/checkpoint.md\nScope: sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN, Type: checkpoint, Score: 19.753\n...Mention specific file paths and code locations._\n\nExecuting OUTWARD_READING for <<research>>-<<262>>-r1 (issue <<262>>: <<SQLite>> <<WAL>> performance under concurrency in Python apps; acceptance-test question). Source-ID scheme: S1=<<sqlite>>...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d08ef0effe7822prgaw/checkpoint.md\nScope: sessions/ses_-ffe5f7d08ef0effe7822prgaw, Type: checkpoint, Score: 18.352\n...Mention specific file paths and code locations._\n\nExecuting OUTWARD_READING for <<research>>-<<262>>-r1 (issue <<262>>: <<SQLite>> <<WAL>> performance under concurrency in Python apps; acceptance-test question). Progress so far:\n\n1. Recovered...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr/checkpoint.md\nScope: sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr, Type: checkpoint, Score: 17.112\n...OUTWARD_DISCOVERY stage for issue <<262>> (<<research>>-<<262>>-r1, <<SQLite>> <<WAL>> performance in concurrent Python apps) — repo grounding + 4 discovery searches done, URL inventory captured, outward_discovery.json artifact pending\n\n# Session checkpoint...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN/checkpoint-outward-reading-sources.md\nScope: sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN, Type: checkpoint, Score: 15.062\n# OUTWARD_READING source extraction — <<research>>-<<262>>-r1 (issue <<262>>)\n\nClaim extractions from primary-source reads, full detail. Source IDs follow the scheme established in §10 (S1=<<sqlite>>.org/<<wal>>.html, S2=<<sqlite>>...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN/checkpoint-outward-reading-open-notes.md\nScope: sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN, Type: checkpoint, Score: 14.808\n# §11 Open notes spillover — carried-forward items (<<research>>-<<262>>-r1)\n\nExtracted from checkpoint.md §11 at budget-trim; these are historical/carried-forward notes, not current blockers.\n\n- Corroboration candidate (NOT in discovery...\n\n### /home/nick/.local/share/mimocode/memory/projects/add96ab3-25dd-4c38-9fa3-34c01811d081/MEMORY.md\nScope: projects/add96ab3-25dd-4c38-9fa3-34c01811d081, Type: memory, Score: 12.100\n...sources.md`) with S-numbered source IDs so the <<ADVERSARIAL>> stage can reference claims.\n- Rune's <<SQLite>> usage (grounding for DB-related <<research>> questions): ~15 modules in src/rune/ each open fresh...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5fc20c77acffeZPFtNS5gw/tasks/T4.7/progress.md\nScope: sessions/ses_-ffe5fc20c77acffeZPFtNS5gw, Type: progress, Score: 9.061\n...Added per-canonical-database-path <<WAL>> activation locks, deadline-bounded retry with exponential backoff for <<SQLite>> `BUSY`/`LOCKED` only, requested busy-timeout restoration, and cleanup of partially initialized connections on failure.\n- tests...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5fc20c77acffeZPFtNS5gw/tasks/T4.6/progress.md\nScope: sessions/ses_-ffe5fc20c77acffeZPFtNS5gw, Type: progress, Score: 7.769\n...Fixed conversation-store paging and <<SQLite>> initialization, migration, and channel-creation concurrency.\n\n## §2 Subagent intent\nThis subagent was asked to address four code-quality findings in the Rune conversation store using strict...\n\n### /home/nick/.local/share/mimocode/memory/projects/global/MEMORY-rules-shipped-2026-09-07.md\nScope: projects/global, Type: memory, Score: 7.461\n...Nick: \"lets follow the order\" after the pipeline report) — ALL FIVE EXECUTED:** #151 structuralized (docs/<<adversarial>>-review.md + dispatch template + henxel) → #157 fixture pipeline (capture/redact/manifest/tamper-evidence; seed = #192 defect...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f84d8cf57ffeeV370GauT/checkpoint.md\nScope: sessions/ses_-ffe5f84d8cf57ffeeV370GauT, Type: checkpoint, Score: 7.047\n...one-time <<research>>-pending sweep + <<research>> round as dispatched headless stage (spec-gate pattern).\n- **IMPROVEMLine truncated
|
||||
{"type":"step_finish","timestamp":1788905411799,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831253bb0011k7AJ70AH","reason":"tool-calls","snapshot":"231173cce75546e05700e8dad40ba9737f6c29a2","messageID":"msg_g001a0831204b30015PYufGjDD","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":29826,"input":29079,"output":100,"reasoning":583,"cache":{"write":0,"read":64}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905424789,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831287920017f6DVvqCk","messageID":"msg_g001a083125729001OQQb1KdLL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"54125433a878edda9be92c7e9554d166f950138b","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905425731,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312883a001XFhKsxPyC","messageID":"msg_g001a083125729001OQQb1KdLL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"No skill match — continuing without one. Let me locate the prior stage artifacts on disk (DEFINE/OUTWARD_DISCOVERY/OUTWARD_READING) so I can attack the preferred approach with specifics.","time":{"start":1788905424954,"end":1788905425729}}}
|
||||
{"type":"tool_use","timestamp":1788905425800,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"read","callID":"call_8762659ad5bf4210ae4d2563","state":{"status":"completed","input":{"file_path":"/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN/checkpoint-outward-reading-sources.md"},"output":"<path>/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7cf348c4ffeSAHmubYWN/checkpoint-outward-reading-sources.md</path>\n<type>file</type>\n<content>\n1: # OUTWARD_READING source extraction — research-262-r1 (issue 262)\n2: \n3: Claim extractions from primary-source reads, full detail. Source IDs follow the scheme established in §10 (S1=sqlite.org/wal.html, S2=sqlite.org/c3ref/wal_checkpoint_v2.html, S3=github.com/joedougherty/sqlite3_concurrent_writes_test_suite — read in prior session ses_-ffe5f7d08ef0effe7822prgaw).\n4: \n5: ## S4 — github.com/necat101/sqlite-deployment-safety-lab (repro lab; HN #47637353)\n6: \n7: - Incident (via HN thread summary): Ultrathink.art lost 2 orders after 11 pushes in 2 hours with overlapping Kamal deploys; 3 containers simultaneously accessed the same SQLite WAL file on a shared Docker volume; orders 16–17 succeeded in Stripe but never reached the DB.\n8: - Experiment 1 (validated with output shown): even in WAL mode only ONE writer at a time; 5 concurrent writers → 3 succeeded, 2 failed with SQLITE_BUSY, 2 lost writes.\n9: - Experiment 2: in controlled tests SQLite serializes overlapping-deploy writes correctly with no loss; real data loss occurs when processes are SIGTERM'd mid-transaction or the app doesn't handle SQLITE_BUSY.\n10: - Experiment 3: long-running readers block checkpoints → WAL file grows.\n11: - Experiment 4: `cp` of a live DB can produce corrupt backups; use `sqlite3 db \".backup backup.db\"` / backup API.\n12: - Experiment 5: `timeout: 5000` → writers wait up to 5 s, then fail with SQLITE_BUSY; app must retry or handle the error.\n13: - Operational takeaways: deploy serialization is mandatory (e.g. GH Actions `concurrency` group); monitor WAL size; handle SQLITE_BUSY.\n14: - LIMITATIONS: single-author repro lab; README states Experiment 1 \"fully validated\" but Experiments 2–5 only \"validated locally — run them to see results\" (no per-run output for 2–5 in README); incident attribution (lost orders ↔ SQLite) is contested in the HN thread itself (\"operational failure, not SQLite failure\"); small scale.\n15: \n16: ## S5 — dev.to/odd_background_328 \"Reproduce SQLite WAL Checkpoint Starvation With One Forgotten Reader\" (posted Jul 20)\n17: \n18: - Claim: a SQLite service can keep answering health checks while its WAL grows without a successful checkpoint; ONE forgotten open read transaction suffices.\n19: - Drill: enable WAL; connection A opens a read transaction and holds it; connection B commits 10,000 writes over 60 s; sample WAL bytes + `PRAGMA wal_checkpoint(PASSIVE)` counters every second; release A and observe recovery.\n20: - Gate (Given/When/Then): reader holds txn → 10k writes → writes remain bounded, WAL-growth alert fires before disk budget; reader closes → checkpoint progress resumes and WAL converges.\n21: - Key quote: \"A green SELECT 1 says nothing about checkpoint progress.\"\n22: - Guidance: do NOT start with an automatic TRUNCATE loop (busy result is evidence of contention; aggressive checkpoints add latency); fix reader lifecycle (close iterators, max transaction age); tie alert thresholds to disk budget, not arbitrary file size.\n23: - Commenter (Mads Hansen) adds: track reader snapshot end-marks and WAL-growth-vs-free-disk runway as an SLO pair (max reader txn age + min runway); verify recovery under continued writes, not just idle; test exception/cancellation paths so abandoned iterators release their txn.\n24: - LIMITATIONS: blog post; no linked runnable repo; anecdotal + commenter-augmented; mirrors S1 §6 semantics rather than adding new measurements.\n25: \n26: ## S6 — sqliteforum.com/p/checkpoint-algorithms-and-wal-performance (\"Checkpoint Algorithms and WAL Performance Tuning\", Jenny Muralidharan, May 12, 2026)\n27: \n28: - Checkpoint = copying committed WAL frames into the main DB file (vs commit = visibility only).\n29: - Default auto-checkpoint: `PRAGMA wal_autocheckpoint = 1000` (pages).\n30: - Mode recap (consistent with S2): PASSIVE copies what it can, never blocks, incomplete common under read load; FULL waits for readers, more complete, higher latency; RESTART = FULL + resets WAL so new writes start over (file may stay allocated); TRUNCATE = RESTART + truncates WAL to 0 bytes (most expensive; maintenance windows).\n31: - Core trade-off: WAL writes are sequential appends; checkpointing reintroduces random I/O + sync overhead; write amplification (same logical update written to WAL AND DB file), noticeable on HDD/cloud storage.\n32: - Frequent-small vs large-infrequent checkpoints: frequent → smaller WAL, lower recovery overheLine truncated
|
||||
{"type":"tool_use","timestamp":1788905425804,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"glob","callID":"call_936ba7cf751c408aa621b66f","state":{"status":"completed","input":{"pattern":"**/research*262*/**"},"output":"No files found","metadata":{"count":0,"truncated":false},"title":"","time":{"start":1788905425732,"end":1788905425803}},"id":"prt_g001a083128846001tAelw7ybQ","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a083125729001OQQb1KdLL"}}
|
||||
{"type":"tool_use","timestamp":1788905425888,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"glob","callID":"call_9f9772631d3c4cba98c2bcce","state":{"status":"completed","input":{"pattern":"**/*outward*"},"output":"/mnt/workdrive/research-stage/research/issue-262/outward_reading.json\n/mnt/workdrive/research-stage/prompts/research-stages/outward_discovery.md\n/mnt/workdrive/research-stage/prompts/research-stages/outward_reading.md","metadata":{"count":3,"truncated":false},"title":"","time":{"start":1788905425730,"end":1788905425884}},"id":"prt_g001a083128844001CqbkeAumx","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a083125729001OQQb1KdLL"}}
|
||||
{"type":"step_finish","timestamp":1788905426105,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083128bdf001uSozyMfAo","reason":"tool-calls","snapshot":"16750ea667beb69726ef59eb1f8dafc959f02afc","messageID":"msg_g001a083125729001OQQb1KdLL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":31019,"input":30832,"output":187,"reasoning":0,"cache":{"write":0,"read":0}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905435116,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312afea001o17bpZXsx","messageID":"msg_g001a083128dd50011YlggGrYk","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"1753f57afdcc15d172bbc5f3f5022c10a46632d4","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905436685,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"read","callID":"call_60a03cd51b864728bdfac3eb","state":{"status":"completed","input":{"file_path":"/mnt/workdrive/research-stage/research/issue-262/outward_reading.json"},"output":"<path>/mnt/workdrive/research-stage/research/issue-262/outward_reading.json</path>\n<type>file</type>\n<content>\n1: {\n2: \"process_id\": \"research-262-r1\",\n3: \"issue\": 262,\n4: \"round\": 1,\n5: \"stage\": \"OUTWARD_READING\",\n6: \"title\": \"sqlite WAL performance in concurrent Python applications (acceptance-test question, repo-specific)\",\n7: \"method_note\": \"Primary sources fetched and read in full this stage plus in the prior partially-completed OUTWARD_READING session (ses_-ffe5f7d08ef0effe7822prgaw, which read S1-S3). No new search queries generated, per stage contract. Claims below carry source IDs (S1-S10); repo claims from INWARD (I1-I5) are referenced for mapping only.\",\n8: \"sources\": {\n9: \"S1\": {\n10: \"url\": \"https://sqlite.org/wal.html\",\n11: \"type\": \"official_docs\",\n12: \"authority\": \"high (canonical SQLite documentation)\",\n13: \"read_in\": \"prior session (ses_-ffe5f7d08ef0effe7822prgaw); claims verified against that session's extraction\",\n14: \"limitations\": [\"Documents C-library behavior; Python sqlite3 module wraps the same library so semantics carry over, but Python-side ergonomics (isolation_level, implicit transactions) are not covered by this source\"]\n15: },\n16: \"S2\": {\n17: \"url\": \"https://sqlite.org/c3ref/wal_checkpoint_v2.html\",\n18: \"type\": \"official_docs\",\n19: \"authority\": \"high (canonical SQLite C API reference)\",\n20: \"read_in\": \"prior session\",\n21: \"limitations\": [\"C API reference; PRAGMA wal_checkpoint exposes the same tuple (busy, log, checkpointed) per S5, but the C-API framing (pnLog/pnCkpt out-params) is not literally what Python callers see\"]\n22: },\n23: \"S3\": {\n24: \"url\": \"https://github.com/joedougherty/sqlite3_concurrent_writes_test_suite\",\n25: \"type\": \"repro_test_suite_github\",\n26: \"authority\": \"medium (small public repo: 22 stars, 3 forks, 20 commits; author's own caveats are candid)\",\n27: \"read_in\": \"prior session (README)\",\n28: \"limitations\": [\"No busy_timeout/timeout configuration\", \"Write-only contention; no reader/writer mix\", \"No WAL-size or checkpoint observation\", \"Small scale (ceiling found ~500 simultaneous single-row inserts)\", \"Tests threads/processes against one DB but not a separate-process RW+RO mix\"]\n29: },\n30: \"S4\": {\n31: \"url\": \"https://raw.githubusercontent.com/necat101/sqlite-deployment-safety-lab/master/README.md\",\n32: \"type\": \"repro_lab_github\",\n33: \"authority\": \"medium (README reports validated experiment output; experiments are Python scripts committed in repo; grounded in a real production incident via HN thread #47637353)\",\n34: \"limitations\": [\"README summarizes results; per-experiment scripts were not individually read this stage\", \"Experiment 2 note is the author's own: controlled tests show NO data loss without SIGTERM/unhandled-SQLITE_BUSY\", \"Production-incident generalization comes from one anecdotal incident (Ultrathink.art)\"]\n35: },\n36: \"S5\": {\n37: \"url\": \"https://www.sqliteforum.com/p/checkpoint-algorithms-and-wal-performance\",\n38: \"type\": \"engineering_writeup_newsletter\",\n39: \"authority\": \"medium-low (Substack-style explainer 'SQLite Forum' by Jenny Muralidharan, May 2026; technically consistent with S1/S2 but is not sqlite.org)\",\n40: \"limitations\": [\"Not an official SQLite source despite the domain name\", \"No measurements of its own; all claims qualitative\", \"Minor imprecision: says auto-checkpoint 'happens in the background by a reader connection' — S1 states the COMMITTING thread runs it (this source's framing is wrong per S1)\"]\n41: },\n42: \"S6\": {\n43: \"url\": \"https://github.com/mouadja02/skills/blob/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md\",\n44: \"type\": \"diagnostic_runbook\",\n45: \"authority\": \"medium (operational runbook; explicitly separates sourced facts from original operational guidance; cites sqlite.org docs and real issue trackers)\",\n46: \"limitations\": [\"Operational recommendations (alert ratios, sample counts, escalation order) are author-declared 'not SQLite guarantees'\", \"Issue references (Syncthing #10559, OpenCode #37495, Codex #30517) were not independently opened this stage\"]\n47: },\n48: \"S7\": {\n49: \"url\": \"https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo\",\n50: \"type\": \"engineering_writeup_repro\",\n51: Line truncated
|
||||
{"type":"tool_use","timestamp":1788905436749,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_b04a8064f5644683aa503748","state":{"status":"completed","input":{"command":"ls -la /mnt/workdrive/research-stage/research/issue-262/ 2>/dev/null; ls /mnt/workdrive/research-stage/research/ 2>/dev/null","description":"List research stage artifacts for issue 262"},"output":"total 56\ndrwxr-xr-x 3 nick nick 4096 Sep 8 23:07 .\ndrwxr-xr-x 21 nick nick 4096 Sep 8 22:32 ..\n-rw-r--r-- 1 nick nick 21893 Sep 8 23:07 outward_reading.json\ndrwxr-xr-x 2 nick nick 4096 Sep 8 23:09 runs\n-rw-r--r-- 1 nick nick 20013 Sep 8 23:09 task_tree.json\nbatch-processing\nbuild-mode\ncontract-testing\nfull-audit\ninterstitial-tools\nissue-245-research.md\nissue-260\nissue-261\nissue-262\nllm-craft-api\nllm-craft-deep\nquality-tools\nresearch-methodology\nrune-efficiency\nsafety-override\ntextual-craft\ntool-calling\nuncensored-models\nv1\nworkflow-audit\n","metadata":{"output":"total 56\ndrwxr-xr-x 3 nick nick 4096 Sep 8 23:07 .\ndrwxr-xr-x 21 nick nick 4096 Sep 8 22:32 ..\n-rw-r--r-- 1 nick nick 21893 Sep 8 23:07 outward_reading.json\ndrwxr-xr-x 2 nick nick 4096 Sep 8 23:09 runs\n-rw-r--r-- 1 nick nick 20013 Sep 8 23:09 task_tree.json\nbatch-processing\nbuild-mode\ncontract-testing\nfull-audit\ninterstitial-tools\nissue-245-research.md\nissue-260\nissue-261\nissue-262\nllm-craft-api\nllm-craft-deep\nquality-tools\nresearch-methodology\nrune-efficiency\nsafety-override\ntextual-craft\ntool-calling\nuncensored-models\nv1\nworkflow-audit\n","exit":0,"description":"List research stage artifacts for issue 262","truncated":false},"title":"List research stage artifacts for issue 262","time":{"start":1788905436745,"end":1788905436748}},"id":"prt_g001a08312b2a6001BzfLCmLae","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a083128dd50011YlggGrYk"}}
|
||||
{"type":"step_finish","timestamp":1788905436774,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312b64d0010NqXuz5Fy","reason":"tool-calls","snapshot":"ec9a1d809e9f4694e6953ec527a89f34ca2bfe5b","messageID":"msg_g001a083128dd50011YlggGrYk","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":32868,"input":15177,"output":91,"reasoning":0,"cache":{"write":0,"read":17600}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905444954,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312d658001PkctVco75","messageID":"msg_g001a08312b686001Zcu2O7F2A","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"af0a7f0e354a4cc806267fc39e4b2944ac87f2fc","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905446196,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312d6ee0029Yb6JFlLm","messageID":"msg_g001a08312b686001Zcu2O7F2A","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"I have the OUTWARD_READING artifact. Now let me check the adversarial stage prompt (for the expected artifact format) and the runs/task_tree for the current preferred approach.","time":{"start":1788905445102,"end":1788905446193}}}
|
||||
{"type":"tool_use","timestamp":1788905446204,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_91b6f2162f1e417a8da79ba4","state":{"status":"completed","input":{"command":"ls /mnt/workdrive/research-stage/research/issue-262/runs/ /mnt/workdrive/research-stage/prompts/research-stages/ 2>/dev/null","description":"List runs and stage prompts"},"output":"/mnt/workdrive/research-stage/prompts/research-stages/:\nadversarial.md\ndefine.md\ninnovation.md\ninward.md\noutward_discovery.md\noutward_reading.md\nqualify.md\nsynthesis.md\n\n/mnt/workdrive/research-stage/research/issue-262/runs/:\nstage_ADVERSARIAL.events.jsonl\nstage_ADVERSARIAL.mimo.err.log\nstage_OUTWARD_DISCOVERY.events.jsonl\nstage_OUTWARD_DISCOVERY.mimo.err.log\nstage_OUTWARD_READING.events.jsonl\nstage_OUTWARD_READING.mimo.err.log\n","metadata":{"output":"/mnt/workdrive/research-stage/prompts/research-stages/:\nadversarial.md\ndefine.md\ninnovation.md\ninward.md\noutward_discovery.md\noutward_reading.md\nqualify.md\nsynthesis.md\n\n/mnt/workdrive/research-stage/research/issue-262/runs/:\nstage_ADVERSARIAL.events.jsonl\nstage_ADVERSARIAL.mimo.err.log\nstage_OUTWARD_DISCOVERY.events.jsonl\nstage_OUTWARD_DISCOVERY.mimo.err.log\nstage_OUTWARD_READING.events.jsonl\nstage_OUTWARD_READING.mimo.err.log\n","exit":0,"description":"List runs and stage prompts","truncated":false},"title":"List runs and stage prompts","time":{"start":1788905446201,"end":1788905446204}},"id":"prt_g001a08312d705001AKpK6LhD5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08312b686001Zcu2O7F2A"}}
|
||||
{"type":"tool_use","timestamp":1788905446210,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"grep","callID":"call_9ca5a9bba0aa46b98563e488","state":{"status":"completed","input":{"path":"/mnt/workdrive/research-stage/research/issue-262/task_tree.json","pattern":"preferred|approach|recommendation"},"output":"No files found","metadata":{"matches":0,"truncated":false},"title":"preferred|approach|recommendation","time":{"start":1788905446196,"end":1788905446208}},"id":"prt_g001a08312d8f8001gASGIBhXk","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08312b686001Zcu2O7F2A"}}
|
||||
{"type":"step_finish","timestamp":1788905446240,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312db41001jx0uGiZMV","reason":"tool-calls","snapshot":"c9a48939471280c482f6ac6f70f3b53f5919dcc2","messageID":"msg_g001a08312b686001Zcu2O7F2A","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":38950,"input":5930,"output":188,"reasoning":0,"cache":{"write":0,"read":32832}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905454515,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312fbb10014AY39vq9f","messageID":"msg_g001a08312db7e001nnXLIH18i","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"ce457c5883c117cb556d4248bc78bc4f81aaaecf","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905454875,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"read","callID":"call_8c3c5131c7df4897a80feb34","state":{"status":"completed","input":{"file_path":"/mnt/workdrive/research-stage/prompts/research-stages/adversarial.md"},"output":"<path>/mnt/workdrive/research-stage/prompts/research-stages/adversarial.md</path>\n<type>file</type>\n<content>\n1: # Research Stage: ADVERSARIAL\n2: \n3: ## Process capsule\n4: - Issue: {{ISSUE_NUMBER}}\n5: - Round: {{ROUND}}\n6: - Stage: ADVERSARIAL (of 8)\n7: - Prior artifacts: {{PRIOR_ARTIFACTS}}\n8: - Blocking unknowns: {{BLOCKING_UNKNOWNS}}\n9: \n10: ## Your task\n11: Actively seek evidence AGAINST the current preferred approach.\n12: \n13: ## You MUST\n14: search for failures, limitations, simpler alternatives, negative results\n15: \n16: ## You MUST NOT\n17: do NOT advocate for the preferred approach\n18: \n19: ## Output\n20: Produce your stage artifact as structured text. End with:\n21: ```\n22: StageCompleted: ADVERSARIAL\n23: ```\n24: \n25: If you cannot complete this stage, end with:\n26: ```\n27: StageFailed: ADVERSARIAL\n28: Reason: <why>\n29: ```\n\n(End of file - total 29 lines)\n</content>","metadata":{"preview":"# Research Stage: ADVERSARIAL\n\n## Process capsule\n- Issue: {{ISSUE_NUMBER}}\n- Round: {{ROUND}}\n- Stage: ADVERSARIAL (of 8)\n- Prior artifacts: {{PRIOR_ARTIFACTS}}\n- Blocking unknowns: {{BLOCKING_UNKNOWNS}}\n\n## Your task\nActively seek evidence AGAINST the current preferred approach.\n\n## You MUST\nsearch for failures, limitations, simpler alternatives, negative results\n\n## You MUST NOT\ndo NOT advocate for the preferred approach\n\n## Output\nProduce your stage artifact as structured text. End with:","truncated":false,"loaded":[]},"title":"prompts/research-stages/adversarial.md","time":{"start":1788905454862,"end":1788905454873}},"id":"prt_g001a08312fbb20019jx0WwNUg","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08312db7e001nnXLIH18i"}}
|
||||
{"type":"step_finish","timestamp":1788905454897,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08312fd1a0027Las54K1r","reason":"tool-calls","snapshot":"1cda5d9f4b6b8ad3bae3b7f608d14459249b8d52","messageID":"msg_g001a08312db7e001nnXLIH18i","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":39053,"input":241,"output":28,"reasoning":0,"cache":{"write":0,"read":38784}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905483646,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083136d7b001e2Y5ehfSm","messageID":"msg_g001a08312fd4d001V7pti0oTL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"4d57ddb88c46510b72e7e0696ae6430cffe5c239","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905484633,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313712f001dEBl629JH","messageID":"msg_g001a08312fd4d001V7pti0oTL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"The stage prompt matches the capsule. The preferred approach (from DEFINE + OUTWARD_READING) is roughly: **WAL mode + per-connection PRAGMA stack + busy_timeout retry in Rune's multi-process topology, with an acceptance test built on pytest-benchmark + multiprocessing**. My adversarial job is to attack that. I'll load the firecrawl-search skill to run targeted counter-evidence searches.","time":{"start":1788905484591,"end":1788905484626}}}
|
||||
{"type":"tool_use","timestamp":1788905484642,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"skill","callID":"call_fe257c42d788479b826ad6a6","state":{"status":"completed","input":{"name":"firecrawl-search"},"output":"<skill_content name=\"firecrawl-search\">\n# Skill: firecrawl-search\n\n# firecrawl search\n\nWeb search with optional content scraping. Returns search results as JSON, optionally with full page content.\n\n## When to use\n\n- You don't have a specific URL yet\n- You need to find pages, answer questions, or discover sources\n- First step in the [workflow escalation pattern](firecrawl-cli): search → scrape → map → crawl → interact\n\n## Quick start\n\n```bash\n# Basic search\nfirecrawl search \"your query\" -o .firecrawl/result.json --json\n\n# Search and scrape full page content from results\nfirecrawl search \"your query\" --scrape -o .firecrawl/scraped.json --json\n\n# News from the past day\nfirecrawl search \"your query\" --sources news --tbs qdr:d -o .firecrawl/news.json --json\n```\n\n## Options\n\n| Option | Description |\n| ------------------------------------ | --------------------------------------------- |\n| `--limit <n>` | Max number of results |\n| `--sources <web,images,news>` | Source types to search |\n| `--categories <github,research,pdf>` | Filter by category |\n| `--tbs <qdr:h\\|d\\|w\\|m\\|y>` | Time-based search filter |\n| `--location` | Location for search results |\n| `--country <code>` | Country code for search |\n| `--scrape` | Also scrape full page content for each result |\n| `--scrape-formats` | Formats when scraping (default: markdown) |\n| `-o, --output <path>` | Output file path |\n| `--json` | Output as JSON |\n\n## Tips\n\n- **`--scrape` fetches full content** — don't re-scrape URLs from search results. This saves credits and avoids redundant fetches.\n- Always write results to `.firecrawl/` with `-o` to avoid context window bloat.\n- Use `jq` to extract URLs or titles: `jq -r '.data.web[].url' .firecrawl/search.json`\n- Naming convention: `.firecrawl/search-{query}.json` or `.firecrawl/search-{query}-scraped.json`\n\n## See also\n\n- [firecrawl-scrape](../firecrawl-scrape/SKILL.md) — scrape a specific URL\n- [firecrawl-map](../firecrawl-map/SKILL.md) — discover URLs within a site\n- [firecrawl-crawl](../firecrawl-crawl/SKILL.md) — bulk extract from a site\n\nBase directory for this skill: file:///home/nick/.agents/skills/firecrawl-search\nRelative paths in this skill (e.g., scripts/, reference/) are relative to this base directory.\nNote: file list is sampled.\n\n<skill_files>\n\n</skill_files>\n</skill_content>","metadata":{"name":"firecrawl-search","dir":"/home/nick/.agents/skills/firecrawl-search","truncated":false},"title":"Loaded skill: firecrawl-search","time":{"start":1788905484631,"end":1788905484641}},"id":"prt_g001a083137141001DmVyapp46","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08312fd4d001V7pti0oTL"}}
|
||||
{"type":"step_finish","timestamp":1788905484668,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083137162001yjJsm0ml3","reason":"tool-calls","snapshot":"c1224f82420c8f21626ee984912086d836972431","messageID":"msg_g001a08312fd4d001V7pti0oTL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":40122,"input":283,"output":799,"reasoning":0,"cache":{"write":0,"read":39040}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905491339,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083138b89001bOnp5zOS3","messageID":"msg_g001a0831371b5001loYUZE0tL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"5a03f7d0004616a4ba7bbe4c7b29cd4722c2081f","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905498635,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083138b8a001di903lSGs","messageID":"msg_g001a0831371b5001loYUZE0tL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"Now I'll run counter-evidence searches in parallel — targeting WAL write-throughput negatives, busy_timeout pitfalls, per-connection PRAGMA costs, and the harness/tooling fit, plus simpler alternatives (single-writer thread, serializing writes).","time":{"start":1788905491338,"end":1788905498633}}}
|
||||
{"type":"tool_use","timestamp":1788905499996,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_ec656423485b4c5ea079da25","state":{"status":"completed","input":{"command":"cd /mnt/workdrive/research-stage/research/issue-262/.firecrawl && firecrawl search \"pytest-benchmark multi-process concurrency testing limitations xdist disabled\" --limit 5 -o harness-limitations.json --json 2>&1 | tail -1; echo ---; firecrawl search \"sqlite WAL index shm corruption multiple processes python data loss unreferenced wal\" --limit 6 -o wal-risks.json --json 2>&1 | tail -1","description":"Search harness limits and WAL operational risks","timeout":180000},"output":"---\nzsh:cd:1: no such file or directory: /mnt/workdrive/research-stage/research/issue-262/.firecrawl\n","metadata":{"output":"---\nzsh:cd:1: no such file or directory: /mnt/workdrive/research-stage/research/issue-262/.firecrawl\n","exit":0,"description":"Search harness limits and WAL operational risks","truncated":false},"title":"Search harness limits and WAL operational risks","time":{"start":1788905498646,"end":1788905499995}},"id":"prt_g001a083139ec9001NB2N8SFha","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831371b5001loYUZE0tL"}}
|
||||
{"type":"tool_use","timestamp":1788905500109,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_067bd5ba138c4334a25cd61c","state":{"status":"completed","input":{"command":"cd /mnt/workdrive/research-stage/research/issue-262/.firecrawl && firecrawl search \"python sqlite3 opening connection expensive per-connection PRAGMA overhead WAL sqlite-vec load\" --limit 6 -o conn-overhead.json --json 2>&1 | tail -1; echo ---; firecrawl search \"sqlite single writer thread queue instead of WAL multi-process alternative architecture\" --limit 6 -o alternatives.json --json 2>&1 | tail -1","description":"Search connection overhead and simpler alternatives","timeout":180000},"output":"---\nzsh:cd:1: no such file or directory: /mnt/workdrive/research-stage/research/issue-262/.firecrawl\n","metadata":{"output":"---\nzsh:cd:1: no such file or directory: /mnt/workdrive/research-stage/research/issue-262/.firecrawl\n","exit":0,"description":"Search connection overhead and simpler alternatives","truncated":false},"title":"Search connection overhead and simpler alternatives","time":{"start":1788905498644,"end":1788905500108}},"id":"prt_g001a08313967a001jITwnVO1A","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831371b5001loYUZE0tL"}}
|
||||
{"type":"tool_use","timestamp":1788905501460,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_ffe2cdb1052d4e8b97db9e6a","state":{"status":"completed","input":{"command":"mkdir -p /mnt/workdrive/research-stage/research/issue-262/.firecrawl && cd /mnt/workdrive/research-stage/research/issue-262/.firecrawl && firecrawl search \"sqlite WAL mode concurrent writers slower than journal mode DELETE benchmark negative result\" --limit 6 -o wal-negative.json --json 2>&1 | tail -1; echo ---; firecrawl search \"sqlite busy_timeout doesn't work with BEGIN IMMEDIATE deferred transaction SQLITE_BUSY pitfall\" --limit 6 -o busy-pitfalls.json --json 2>&1 | tail -1","description":"Search WAL negative results and busy_timeout pitfalls","timeout":180000},"output":"---\n","metadata":{"output":"---\n","exit":0,"description":"Search WAL negative results and busy_timeout pitfalls","truncated":false},"title":"Search WAL negative results and busy_timeout pitfalls","time":{"start":1788905500325,"end":1788905501458}},"id":"prt_g001a083138be4001qn56itNY7","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831371b5001loYUZE0tL"}}
|
||||
{"type":"step_finish","timestamp":1788905501486,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313b314001ybSFCN4Es","reason":"tool-calls","snapshot":"63b4d009be3e6fe0ec5ec346a2e224e7bab36d08","messageID":"msg_g001a0831371b5001loYUZE0tL","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":40494,"input":681,"output":453,"reasoning":0,"cache":{"write":0,"read":39360}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905510069,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313d4b2001PKL4UMl98","messageID":"msg_g001a08313b34b001Pm3JMbie4","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"71ff2249362e7066ecb1d8e3cff29030cd925094","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905511223,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313d54c001k8UYkVzV1","messageID":"msg_g001a08313b34b001Pm3JMbie4","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"Parallel `cd` race — the second/third calls ran before the directory existed. Let me check what the first call actually produced, then rerun the two failed searches sequentially.","time":{"start":1788905510220,"end":1788905511221}}}
|
||||
{"type":"tool_use","timestamp":1788905511231,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_3f4481b4ae294084a74415c9","state":{"status":"completed","input":{"command":"ls -la /mnt/workdrive/research-stage/research/issue-262/.firecrawl/ 2>/dev/null; head -c 300 /mnt/workdrive/research-stage/research/issue-262/.firecrawl/wal-negative.json 2>/dev/null","description":"Check firecrawl output files"},"output":"total 20\ndrwxr-xr-x 2 nick nick 4096 Sep 8 23:11 .\ndrwxr-xr-x 4 nick nick 4096 Sep 8 23:11 ..\n-rw-r--r-- 1 nick nick 4526 Sep 8 23:11 busy-pitfalls.json\n-rw-r--r-- 1 nick nick 3077 Sep 8 23:11 wal-negative.json\n{\"success\":true,\"data\":{\"web\":[{\"url\":\"https://sqlite.org/forum/info/117c91891cf7ac15\",\"title\":\"WAL mode speed vs normal comparison - SQLite User Forum\",\"description\":\"WAL is about concurrency, not speed. How could it be faster, for a single connection? Has to potentially re-assemble a table (or ind","metadata":{"output":"total 20\ndrwxr-xr-x 2 nick nick 4096 Sep 8 23:11 .\ndrwxr-xr-x 4 nick nick 4096 Sep 8 23:11 ..\n-rw-r--r-- 1 nick nick 4526 Sep 8 23:11 busy-pitfalls.json\n-rw-r--r-- 1 nick nick 3077 Sep 8 23:11 wal-negative.json\n{\"success\":true,\"data\":{\"web\":[{\"url\":\"https://sqlite.org/forum/info/117c91891cf7ac15\",\"title\":\"WAL mode speed vs normal comparison - SQLite User Forum\",\"description\":\"WAL is about concurrency, not speed. How could it be faster, for a single connection? Has to potentially re-assemble a table (or ind","exit":0,"description":"Check firecrawl output files","truncated":false},"title":"Check firecrawl output files","time":{"start":1788905511228,"end":1788905511230}},"id":"prt_g001a08313d565001NpxHCcAwF","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08313b34b001Pm3JMbie4"}}
|
||||
{"type":"step_finish","timestamp":1788905511260,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313d93f001oKgieE900","reason":"tool-calls","snapshot":"eb96a1349433369a6b514c15cf46aea184703371","messageID":"msg_g001a08313b34b001Pm3JMbie4","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":40750,"input":501,"output":185,"reasoning":0,"cache":{"write":0,"read":40064}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905517314,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313f100001DH0lsLuI4","messageID":"msg_g001a08313d97f001W7IBNIhb5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"0eb1d789c0f9925a18e2d8d167aefca95e129892","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905521145,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08313f101001JY0w2w6B5","messageID":"msg_g001a08313d97f001W7IBNIhb5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"The first call's two searches succeeded despite the odd output. Now rerun the four remaining searches with the directory existing this time:","time":{"start":1788905517313,"end":1788905521143}}}
|
||||
{"type":"tool_use","timestamp":1788905523556,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_b745bb492612472283349aaa","state":{"status":"completed","input":{"command":"firecrawl search \"pytest-benchmark limitations multi-process concurrency testing pytest-xdist auto-disable\" --limit 5 -o harness-limitations.json --json 2>&1 | tail -1; echo ---; firecrawl search \"sqlite WAL shm wal-index corruption risks multiple processes data loss\" --limit 6 -o wal-risks.json --json 2>&1 | tail -1","description":"Search harness limits and WAL risks","timeout":180000,"workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"---\n","metadata":{"output":"---\n","exit":0,"description":"Search harness limits and WAL risks","truncated":false},"title":"Search harness limits and WAL risks","time":{"start":1788905522231,"end":1788905523555}},"id":"prt_g001a08313f800001BpIgGCqtX","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08313d97f001W7IBNIhb5"}}
|
||||
{"type":"tool_use","timestamp":1788905523560,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_be4821f5ed6f4df4a83de749","state":{"status":"completed","input":{"command":"firecrawl search \"python sqlite3 per-connection overhead opening connection each time expensive performance\" --limit 6 -o conn-overhead.json --json 2>&1 | tail -1; echo ---; firecrawl search \"sqlite single writer thread queue alternative to WAL for multi-process writes\" --limit 6 -o alternatives.json --json 2>&1 | tail -1","description":"Search connection overhead and simpler alternatives","timeout":180000,"workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"---\n","metadata":{"output":"---\n","exit":0,"description":"Search connection overhead and simpler alternatives","truncated":false},"title":"Search connection overhead and simpler alternatives","time":{"start":1788905522473,"end":1788905523559}},"id":"prt_g001a08313f158001WpPCl1Je7","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08313d97f001W7IBNIhb5"}}
|
||||
{"type":"step_finish","timestamp":1788905523580,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083140968001zC9TSv5qw","reason":"tool-calls","snapshot":"e9b0b1aaaa9400ec8170955964984090ebac2a55","messageID":"msg_g001a08313d97f001W7IBNIhb5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":41143,"input":286,"output":281,"reasoning":0,"cache":{"write":0,"read":40576}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905525878,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083141275001fTHxSURrz","messageID":"msg_g001a08314099c0018F6qzVNPB","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"83952808b97a347603b2ded0a85837c28a25ce76","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905527814,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_e0646af121c44927993d1382","state":{"status":"completed","input":{"command":"for f in conn-overhead alternatives harness-limitations wal-risks; do echo \"=== $f ===\"; jq -r '.data.web[]? | \"\\(.title) | \\(.url) | \\(.description // \"\" | .[0:160])\"' $f.json 2>/dev/null; done","description":"Extract titles/URLs/descriptions from all search results","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"=== conn-overhead ===\nHow expensive sqlite3.connect and close in SQLite? - Stack Overflow | https://stackoverflow.com/questions/3747232/how-expensive-sqlite3-connect-and-close-in-sqlite | Connections are fairly expensive – they correspond to opening the file – but cursors aren't very so use as many as you need.python - Efficiency of reopening sql\nSQLite async connection pool for high-performance - Hacker News | https://news.ycombinator.com/item?id=44530518 | Opening and closing SQLite connections is expensive. If we can re-use the same instance things go a lot faster. anacrolix on July 15, 2025 ...\nTips for getting SQLite under Python to perform better with more RAM? | https://sqlite.org/forum/info/4393a42b3b5e2382 | I'm interested in getting better performance out of SQLite on machines with more RAM, using the Python sqlite3 module from the standard ...Questions about runni\nGetting the most out of SQLite3 with Python | https://remusao.github.io/posts/few-tips-sqlite-perf.html | # Getting the most out of SQLite3 with Python\n## Use Bulk Operations\n```\nconnection.executemany(\n 'INSERT INTO my_table VALUE (?)',\n iter_data()\n)\n```\n\n- \nsqlite3 — DB-API 2.0 interface for SQLite databases — Python 3.14.7 ... | https://docs.python.org/3/library/sqlite3.html | # `sqlite3` — DB-API 2.0 interface for SQLite databases [¶](https://docs.python.org/3/library/sqlite3.html#module-sqlite3)\n## Reference [¶](https://docs.python.\nSQLite Optimizations For Ultra High-Performance - PowerSync | https://powersync.com/blog/sqlite-optimizations-for-ultra-high-performance | # SQLite Optimizations For Ultra High-Performance\n## Key SQLite Performance Optimizations To Consider\n### **#** 1: Enable Write-Ahead Logging (WAL) And Disable \n=== alternatives ===\nWhat does, if many threads and/or processes need to write ... - SQLite | https://sqlite.org/forum/info/6ed6824176b9c773 | # What does, if many threads and/or processes need to write the database at the same instant, mean?\n### (2) By [ThanksRyan](https://sqlite.org/forum/timeline?ss\nI've yet to see how you can use SQLite for a multi-user multi-write app ... | https://news.ycombinator.com/item?id=31473373 | SQLite uses a queue (in WAL mode) in order to handle concurrent writes. In WAL mode it can handle a single writer with concurrent readers. A single thread; no .\nConfused about SQLite and concurrency : r/learnprogramming | https://www.reddit.com/r/learnprogramming/comments/1l82ohn/confused_about_sqlite_and_concurrency/ | So sqlite, with WAL enabled, supports multiple readers at the same time, and supports reading and writing at the same time. The only thing it ...Question regard\nSingle-writer Database Architecture with SQLite - Bugsink | https://www.bugsink.com/blog/database-transactions/ | SQLite allows only one writer at a time. Even in WAL mode, concurrent write transactions are not possible – any attempt to write while another ...\nSQLite alternative with concurrent writing (Delphi) - Stack Overflow | https://stackoverflow.com/questions/9264772/sqlite-alternative-with-concurrent-writing-delphi | You may consider using FireBird which has a more complex (and tuned) architecture for client-server. SQLite3 default writing method is expected ...SQLite Concur\nThe Write Stuff: Concurrent Write Transactions in SQLite | https://oldmoe.blog/2024/07/08/the-write-stuff-concurrent-write-transactions-in-sqlite/ | SQLite, using the Write-Ahead-Log (WAL) journaling mode, supports an unlimited number of readers and a single writer any given moment.\n=== harness-limitations ===\nRunning tests across multiple CPUs — pytest-xdist documentation | https://pytest-xdist.readthedocs.io/en/stable/distribution.html | - Running tests across multiple CPUs\n\n# Running tests across multiple CPUs [](https://pytest-xdist.readthedocs.io/en/stable/distribution.html#running-tests-acr\nHow to run pytest tests in parallel? - python - Stack Overflow | https://stackoverflow.com/questions/45733763/how-to-run-pytest-tests-in-parallel | UPDATE: The solution below is to demonstrate concurrent pytests are possible, but pytest-parallel is currently unmaintained. pytest-xdist is a ...pytest fixture\nIs there an easy way to disable thread parallelism for tests in one file? | https://github.com/pytest-dev/pytest/discussions/12188 | If you're using the pytest-xdist plugin … you can disable parallelism by specifyiLine truncated
|
||||
{"type":"step_finish","timestamp":1788905527838,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083141a05001RxbgaQlrs","reason":"tool-calls","snapshot":"d7d8bb5768fe0a6303d6bc22958e839b68e60452","messageID":"msg_g001a08314099c0018F6qzVNPB","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":41265,"input":255,"output":114,"reasoning":0,"cache":{"write":0,"read":40896}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905533224,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083142f26001lWw0liYPF","messageID":"msg_g001a083141a39001hzKKXS4T5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"365ae35a1d223f79995e18abef76315989693620","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905534631,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_80a9aedb617c47f49f4f643e","state":{"status":"completed","input":{"command":"for f in wal-negative busy-pitfalls; do echo \"=== $f ===\"; jq -r '.data.web[]? | \"\\(.title) | \\(.url) | \\(.description // \"\" | .[0:160])\"' $f.json 2>/dev/null; done","description":"Extract results from first-batch searches","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"=== wal-negative ===\nWAL mode speed vs normal comparison - SQLite User Forum | https://sqlite.org/forum/info/117c91891cf7ac15 | WAL is about concurrency, not speed. How could it be faster, for a single connection? Has to potentially re-assemble a table (or index) pages ...WAL journal and\nStop the SQLite Performance Wars: Your Database Can Be 10x Faster ... | https://javascript.plainenglish.io/stop-the-sqlite-performance-wars-your-database-can-be-10x-faster-and-its-not-magic-156022addc75 | # Stop the SQLite Performance Wars: Your Database Can Be 10x Faster (and it’s not magic!) ✨🚀\n## The Great Showdown: Rollback vs. The WAL Wizardry\n- **With WAL:*\nWAL Mode, SQLite3 Bulk updates/inserts : r/sqlite - Reddit | https://www.reddit.com/r/sqlite/comments/1ecjvst/wal_mode_sqlite3_bulk_updatesinserts/ | WAL mode is slower than JOURNAL_MODE=DELETE for inserts. WAL stands for Write Ahead Log. not perform the same thing because another process ...Sqlite wal mode r\nSQLite's WAL mode is fast fast - YouTube | https://www.youtube.com/watch?v=qf0GqRz-c74 | Want to learn more SQLite? Check out the full course: https://highperformancesqlite.com. Get your free SQLite reference guide: ...\nmysql - Why is SQLite WAL mode so much faster than default DELETE ... | https://superuser.com/questions/1938008/why-is-sqlite-wal-mode-so-much-faster-than-default-delete-mode-for-concurrent-wr | The write performance improved drastically, almost by a factor of 4 or 5, and the disk activity dropped significantly. I understand that WAL ...\nSQLite: enable WAL mode and busy_timeout for concurrent write ... | https://github.com/cashubtc/nutshell/issues/907 | # SQLite: enable WAL mode and busy_timeout for concurrent write performance#907\n## Problem\n```\n2026-02-25 19:27:31 | ERROR | cashu.mint.app:catch_exceptions:107\n=== busy-pitfalls ===\nWhat to do about SQLITE_BUSY errors despite setting a timeout | https://berthub.eu/articles/posts/a-brief-post-on-sqlite3-database-locked-despite-timeout/ | # SQLite transactions\nYou can also force this decision with BEGIN IMMEDIATE, which always starts a write transaction.\n\n```sql\npragma journal_mode=\"wal\"; -- only\nWhat to do about SQLITE_BUSY errors despite setting a timeout | https://lobste.rs/s/yapvon/what_do_about_sqlite_busy_errors_despite | TLDR: if you're seeing SQLITE_BUSY errors, try using BEGIN IMMEDIATE for transactions that you know are going to be a write. It turns out I've ...\nIn SQLite, transactions by default start in “deferred” mode. This means ... | https://news.ycombinator.com/item?id=45781519 | The fix is to set a busy_timeout and to begin any transaction ... Note that busy_timeout is not applicable to SQLite in this case (the SQLITE_BUSY issued ...\nHelp understanding the effect of BEGIN IMMEDIATE - SQLite | https://sqlite.org/forum/forumpost/04ed1d235b | # Help understanding the effect of BEGIN IMMEDIATE\n### (1) By Simon Willison ( [simonw](https://sqlite.org/forum/timeline?ss=v&y=f&vfx&u=simonw)) on 2024-06-21 \nImplementing busy-waiting on SQLite | https://sqlite-users.sqlite.narkive.com/66NfRrlL/implementing-busy-waiting-on-sqlite | If the transaction contains a command that will change the database (eg delete, update or insert), then use \"begin immediate\" to start the transaction, so that \nSimon Willison on sqlite-busy | https://simonwillison.net/tags/sqlite-busy/ | The fix is to use BEGIN IMMEDIATE if you know your transaction is going to make a write. Bert provides the clearest explanation I've seen yet of ...\n","metadata":{"output":"=== wal-negative ===\nWAL mode speed vs normal comparison - SQLite User Forum | https://sqlite.org/forum/info/117c91891cf7ac15 | WAL is about concurrency, not speed. How could it be faster, for a single connection? Has to potentially re-assemble a table (or index) pages ...WAL journal and\nStop the SQLite Performance Wars: Your Database Can Be 10x Faster ... | https://javascript.plainenglish.io/stop-the-sqlite-performance-wars-your-database-can-be-10x-faster-and-its-not-magic-156022addc75 | # Stop the SQLite Performance Wars: Your Database Can Be 10x Faster (and it’s not magic!) ✨🚀\n## The Great Showdown: Rollback vs. The WAL Wizardry\n- **With WAL:*\nWAL Mode, SQLite3 Bulk updates/inserts : r/sqlite - Reddit | https://www.reddit.com/r/sqlite/comments/1ecjvst/wal_mode_sqlite3_bulk_updatesinserts/ | WAL mode is slower than JOURNAL_MODE=DELETE for inserts. WAL stands for Write Ahead Log. not pLine truncated
|
||||
{"type":"step_finish","timestamp":1788905534655,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831434a7001PbC93wI5w","reason":"tool-calls","snapshot":"4a50b73dd7338e8e16d282052f4fb6217bd1b57e","messageID":"msg_g001a083141a39001hzKKXS4T5","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":42953,"input":1696,"output":105,"reasoning":0,"cache":{"write":0,"read":41152}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905539502,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831447ac001wdkqAGKji","messageID":"msg_g001a0831434df001tH517JJfh","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"89f2598119aabe94bc54520d7c7366f9eb476401","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905544071,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831447ad001AmNYELAPc","messageID":"msg_g001a0831434df001tH517JJfh","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"Good yield. Let me scrape the four highest-value attack sources: Bugsink single-writer architecture (alternative), avi.im WAL checksum silent-loss post, the Reddit \"WAL slower for inserts\" thread, and berthub SQLITE_BUSY-despite-timeout.","time":{"start":1788905539501,"end":1788905544069}}}
|
||||
{"type":"tool_use","timestamp":1788905547979,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_8f755f60ea9347cf86745c25","state":{"status":"completed","input":{"command":"firecrawl scrape \"https://www.bugsink.com/blog/database-transactions/\" -o s-bugsink.md 2>&1 | tail -1; firecrawl scrape \"https://avi.im/blag/2025/sqlite-wal-checksum/\" -o s-aviim.md 2>&1 | tail -1","description":"Scrape Bugsink alternative-architecture post and WAL checksum post","timeout":180000,"workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"Scrape ID: 01a08314-5b6d-762e-a22f-18380cbd0cfd\nScrape ID: 01a08314-6320-722e-88eb-8f82e4152b05\n","metadata":{"output":"Scrape ID: 01a08314-5b6d-762e-a22f-18380cbd0cfd\nScrape ID: 01a08314-6320-722e-88eb-8f82e4152b05\n","exit":0,"description":"Scrape Bugsink alternative-architecture post and WAL checksum post","truncated":false},"title":"Scrape Bugsink alternative-architecture post and WAL checksum post","time":{"start":1788905547974,"end":1788905547978}},"id":"prt_g001a083144813001NxZitAm40","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831434df001tH517JJfh"}}
|
||||
{"type":"tool_use","timestamp":1788905549913,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_d9424454209242f0969c9e39","state":{"status":"completed","input":{"command":"firecrawl scrape \"https://berthub.eu/articles/posts/a-brief-post-on-sqlite3-database-locked-despite-timeout/\" -o s-berthub.md 2>&1 | tail -1; firecrawl scrape \"https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database\" -o s-so-corrupt.md 2>&1 | tail -1","description":"Scrape berthub busy pitfall and SO corruption thread","timeout":180000,"workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"Scrape ID: 01a08314-5b5f-759d-be55-47f4a578cc0a\nScrape ID: 01a08314-6606-7198-b8b8-58aa8adf5e8c\n","metadata":{"output":"Scrape ID: 01a08314-5b5f-759d-be55-47f4a578cc0a\nScrape ID: 01a08314-6606-7198-b8b8-58aa8adf5e8c\n","exit":0,"description":"Scrape berthub busy pitfall and SO corruption thread","truncated":false},"title":"Scrape berthub busy pitfall and SO corruption thread","time":{"start":1788905549908,"end":1788905549912}},"id":"prt_g001a0831450310016KtqcDazj","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831434df001tH517JJfh"}}
|
||||
{"type":"step_finish","timestamp":1788905549937,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083147059001FwcIAtJ0V","reason":"tool-calls","snapshot":"c9895665bc2c9202df9f8c6281aade46af658519","messageID":"msg_g001a0831434df001tH517JJfh","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":44174,"input":970,"output":324,"reasoning":0,"cache":{"write":0,"read":42880}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905552887,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083147bf5001AvTnvtWH5","messageID":"msg_g001a0831470ad001VulHYQLya","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"8a3e5ae690e447f6c9916c074d2f99c8bf9d3a5d","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905554124,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_8bd5ed5726244e3c95b317fa","state":{"status":"completed","input":{"command":"for f in s-bugsink s-aviim s-berthub s-so-corrupt; do echo \"=== $f: $(wc -c < $f.md 2>/dev/null) bytes ===\"; done","description":"Check scraped file sizes","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"=== s-bugsink: 16782 bytes ===\n=== s-aviim: 6784 bytes ===\n=== s-berthub: 12936 bytes ===\n=== s-so-corrupt: 40664 bytes ===\n","metadata":{"output":"=== s-bugsink: 16782 bytes ===\n=== s-aviim: 6784 bytes ===\n=== s-berthub: 12936 bytes ===\n=== s-so-corrupt: 40664 bytes ===\n","exit":0,"description":"Check scraped file sizes","truncated":false},"title":"Check scraped file sizes","time":{"start":1788905554120,"end":1788905554122}},"id":"prt_g001a083147bf6002C58Vk2Oe0","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a0831470ad001VulHYQLya"}}
|
||||
{"type":"step_finish","timestamp":1788905554147,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831480cb001EN9n047PO","reason":"tool-calls","snapshot":"64ece0dcea8954cdf6de7a304265e3c59d10f2c7","messageID":"msg_g001a0831470ad001VulHYQLya","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":44392,"input":400,"output":88,"reasoning":0,"cache":{"write":0,"read":43904}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905559919,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314976d001RFBPpDvUv","messageID":"msg_g001a083148105001P7DZJ37m6","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"183a84adc5763d7e1182b96d7b5093f9829b9eb5","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905562693,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_d3758014e12d46aa98e4e3a2","state":{"status":"completed","input":{"command":"grep -B2 -A 25 -i \"checksum\" s-aviim.md | head -70","description":"Extract WAL checksum silent loss claims","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"[About](https://avi.im/blag/about)[Now](https://avi.im/blag/now)\n\n# PSA: SQLite WAL checksums fail silently and may lose data\n\n22 Jul 2025\n\nThis is a follow-up post to my [PSA: SQLite does not do checksums](https://avi.im/blag/2024/sqlite-bit-flip) and [PSA: Most databases do not do checksums by default](https://avi.im/blag/2024/databases-checksum). In the previous posts I mentioned that SQLite does not do checksums by default, but it has checksums in WAL mode. However, on checksum errors, instead of raising error, it drops all the subsequent frames. Even if they are not corrupt. This is not a bug; it’s intentional.\n\nDisclosure: I work at Turso, which maintains a SQLite fork, libSQL. Since libSQL is a fork, it also has the same issue.\n\n## SQLite WAL\n\nSQLite introduced WAL in 2010. It’s not the default mode, but you’re likely using it if you want higher write throughput. Whenever you make writes, they are first written to the WAL file. Then, during checkpoint operations, the database pages are written from the WAL to the main DB file. Each page in the WAL is called a frame. Each frame has a header, which comprises the frame number, page number, commit marker, and checksums.\n\n\n\nThe way checksums work in WAL is interesting. They use rolling checksums, meaning the checksum of the n+1 frame is computed with the checksum of the nth frame. In other words, a frame’s checksum depends on the previous frame.\n\n\n\n## Recovery\n\nIf one frame is found to have a checksum mismatch, you can’t be sure that the next frame isn’t corrupted either. What’s interesting is that when a frame is found to have a missing or invalid checksum, SQLite drops that frame and all the subsequent frames. This is [documented](https://www.sqlite.org/walformat.html#recovery):\n\n> Recovery works by doing a single pass over the WAL, from beginning to end. The checksums are verified on each frame of the WAL as it is read. The scan stops at the end of the file or at the first invalid checksum. The mxFrame field is set to the index of the last valid commit frame in WAL.\n\nEarlier I mentioned SQLite does not do checksums by default, so it won’t ever notice if a page is corrupt. So when is WAL checksum verification triggered? A WAL may contain multiple frames for the same page number. To make lookups faster, SQLite maintains an index called the WAL Index. This is the `.db-shm` file you often see. During the building of this index, SQLite checks the checksums.\n\nYou can verify this in the code as well. The recovery process happens in [`walIndexRecover`](https://github.com/sqlite/sqlite/blob/version-3.50.3/src/wal.c#L1384), this calls [`walDecodeFrame`](https://github.com/sqlite/sqlite/blob/version-3.50.3/src/wal.c#L1000) which has this:\n\n```c\n/* A frame is only valid if a checksum of the WAL header,\n** all prior frames, the first 16 bytes of this frame-header,\n** and the frame-data matches the checksum in the last 8\n** bytes of this frame-header.\n*/\nnativeCksum = (pWal->hdr.bigEndCksum==SQLITE_BIGENDIAN);\nwalChecksumBytes(nativeCksum, aFrame, 8, aCksum, aCksum);\nwalChecksumBytes(nativeCksum, aData, pWal->szPage, aCksum, aCksum);\nif( aCksum[0]!=sqlite3Get4byte(&aFrame[16])\n || aCksum[1]!=sqlite3Get4byte(&aFrame[20])\n){\n /* Checksum failed. */\n return 0;\n}\n```\n\nTo trigger this issue, the following needs to happen:\n\n1. You have SQLite `.db` and `.db-wal` files, but no accompanying `.db-shm` file. Maybe your friend shared it with you, or you downloaded some data off the internet.\n2. Unclean shutdown during WAL write. The WAL index is updated after a successful write. Maybe after the WAL write, the process crashed, and the index wasn’t updated. On the next start, SQLite rebuilds the index.\n\nDuring this process, if there’s a checksum mismatch on a frame, that frame and the rest of the WAL frames are dropped. Even if they are not corrupt (technically)! Note that SQLite always checkpoints and truncates the WAL file on the last connection close.\n\n## Demo\n\n\n\nAlice would have lost money, [again](https://avi.im/blag/2024/sqlite-bit-flip). Poor Alice.\n\n## Thoughts\n\n1. I really don’t like that SQLite doesn’t throw any error on detection of corruption\n2. Since it automatically checkpoints every time, the data is lost too\n\nI’m not sure why this is the default behavior. BackLine truncated
|
||||
{"type":"tool_use","timestamp":1788905562697,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_e7f374e7d3a3413ead2b0949","state":{"status":"completed","input":{"command":"grep -A 40 -i \"single-writer\" s-bugsink.md | head -80","description":"Extract single-writer architecture argument from Bugsink","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"# The single-writer Database Architecture\n\n\n\nKlaas van Schelven;\n\nMarch 24, 2025 - 9 min read\n\n\\| tags: [architecture](https://www.bugsink.com/blog/tags/architecture/)\n\n\n\nConveyor belt with lady-bugs. Representing the idea of processing events in a predictable, sequential manner.\n\n\n**TL;DR**: Bugsink uses a **single-writer architecture** to keep database state consistent and predictable.\nThis model is **built around SQLite’s concurrency model**: for writes, a global lock; for reads, snapshot isolation.\nBugsink’s specific use case ( **event processing**) makes this model a perfect fit.\n\n### Introduction & Design Goals\n\nIn this article, we’ll take a look at Bugsink’s transaction model, and how it uses SQLite’s unique properties to\ncreate a simple, stable, and efficient system.\n\nBugsink is a self-hosted error tracker. This means that it’s built to be **simple to operate and safe to run**: everybody\nshould be able to set it up and keep it running without too much hassle.\n\nIt’s also designed to be **simple to maintain**: I’m a single developer taking on a market in which VC-backed _unicorns_ operate. This\nmeans that I need to be able to reason about the system’s behavior quickly and confidently, even if I haven’t touched\nthat particular part of the code in months.\n\nHere’s how the broader design goals translate into the transaction model:\n\n- **Stability**: No weird edge cases, no locking errors, no surprises under load.\n\n- **Data Integrity**: The transaction model should ensure that data is never left in an inconsistent state, even if something goes wrong.\n(this is a bit of an open door, but it’s worth stating explicitly).\n\n- **Simplicity**: The transaction model should be simple to understand and implement. There’s one way to do it, it’s used\neverywhere, and it’s easy to reason about later. Think once, apply everywhere.\n\n- **Alignment with SQLite**: Lean into what SQLite is good at. Treat its limits as “features in disguise”, shaping\nforces that guide the design. Don’t fight the datbase.\n\n- **Fit with Bugsink’s Architecture**:\nBugsink makes strong, opinionated choices, and the transaction model leans into them. Also: the way we interact with\nthe database might just influence the way we structure the application.\n\n\nAll of these goals point in the same direction: I want a system that works correctly, but without adding extra overhead\nto my development process.\n\nContrast this with the typical “just don’t want to think about transactions at all” approach, where you just do CRUD\noperations throughout the code. That may just work, until it doesn’t. And that’s not acceptible to me.\n\nStill, the underlying objective of not having to think about transactions all the time _is_ very valuable. The\n","metadata":{"output":"# The single-writer Database Architecture\n\n\n\nKlaas van Schelven;\n\nMarch 24, 2025 - 9 min read\n\n\\| tags: [architecture](https://www.bugsink.com/blog/tags/architecture/)\n\n\n\nConveyor belt with lady-bugs. Representing the idea of processing events in a predictable, sequential manner.\n\n\n**TL;DR**: Bugsink uses a **single-writer architecture** to keep database state consistent and predictable.\nThis model is **built around SQLite’s concurrency model**: for writes, a global lock; for reads, snapshot isolation.\nBugsink’s specific use case ( **event processing**) makes this model a perfect fit.\n\n### Introduction & Design Goals\n\nIn this article, we’ll take a look at Bugsink’s transaction model, and how it uses SQLite’s unique properties to\ncreate a simple, stable, and efficient system.\n\nBugsink is a self-hosted error tracker. This means that it’s built to be **simple to operate and safe to run**: everybody\nshould be able to set it up and keep it running without too much hassle.\n\nIt’s also designed to be **simple to maintain**: I’m a single developer taking on a market in which VC-backed _unicorns_ operate. This\nmeans that I need to be able to reason about the system’s behavior quickly and confidently, even if I haven’t touched\nthat particular part of the codLine truncated
|
||||
{"type":"step_finish","timestamp":1788905562746,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314a248001Dk6TxQKxU","reason":"tool-calls","snapshot":"b698b3b7c85170c167f40520fddf187aa13ac83f","messageID":"msg_g001a083148105001P7DZJ37m6","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":44724,"input":26992,"output":132,"reasoning":0,"cache":{"write":0,"read":17600}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905568214,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314b7d5001nUoVC7jkD","messageID":"msg_g001a08314a299001twziD4Pzr","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"5e7c6d211105d84b6cba6f19ab85725e9a85a3da","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905570269,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_647bf9e4fed641c7943b9207","state":{"status":"completed","input":{"command":"grep -B2 -A 20 -i \"immediate\" s-berthub.md | head -60; echo \"=== SO corrupt key parts ===\"; grep -B2 -A 10 -iE \"corrupt|crashed after\" s-so-corrupt.md | head -50","description":"Extract BEGIN IMMEDIATE pitfall and corruption cases","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"Last week however, I ran into one of my projects unexpectedly getting [SQLITE\\_BUSY](https://www.sqlite.org/rescode.html#busy) errors. And then someone urged me to run ‘a real database’ (PostgreSQL), and that hurt.\n\n> The tl;dr on this, to prevent SQLITE\\_BUSY errors even when setting a timeout, don’t ever upgrade transactions to read-write. If you know you are going to write in a transaction, use ‘BEGIN IMMEDIATE’, or start off with the write. But do read on for why this is so, and how other databases struggle with this problem as well.\n>\n> Thanks are due to PostgreSQL developer & backdoor-slayer [Andres Freund for sharing his wisdom on Mastodon](https://mastodon.social/@AndresFreundTec/114009633982257113), which found its way into this post. Mistakes remain mine though!\n\nBefore we start, do know I love both PostgreSQL and SQLite, these are two very impressive projects, and we are extremely lucky that we get to benefit from all this excellence.\n\n# The problem\n\nWhen running in [WAL mode](https://www.sqlite.org/wal.html) (which you should), SQLite makes some explicit and detailed concurrency promises: “Readers do not block writers and a writer does not block readers. Reading and writing can proceed concurrently”. The devil is in those details however.\n\nNow, we can easily deal with _waiting_ for the database to do something. Often there aren’t that many writes, and if occasionally two writes have to wait for each other, this is not a problem, especially since SQLite is extremely fast anyhow. SQLite’s single writer mode will often in practice be faster than other server’s multiple writer models, if only because it has no interprocess/network latency penalty. Meanwhile, SQLite offers various timeout settings and functions to deal with waiting for write access.\n\nWhat is harder to deal with however is when queries or inserts don’t wait but immediately dump a SQLITE\\_BUSY error on you, despite setting a timeout. It can be hard to recover from that.\n\nSo why does this happen?\n\n# SQLite transactions\n\nSQLite allows you to [BEGIN a transaction](https://www.sqlite.org/lang_transaction.html) without telling it what kind of transaction this will be: read-only or a read-write transaction. SQLite actually determines this based on the first statement you execute within the transaction. If that is an UPDATE or a DELETE or anything else that changes things, you get a write capable transaction. Otherwise you get a read-only transaction. You can also force this decision with BEGIN IMMEDIATE, which always starts a write transaction.\n\nTo demonstrate this, we’ll first setup a database:\n\n```sql\npragma journal_mode=\"wal\"; -- only have to do this once\ncreate table t (v INT) strict;\n.timeout 10000 -- 10 seconds\n```\n\nNext up, let’s open two parallel connections:\n\n```\nbegin immediate; |\ninsert into t values (1); | begin immediate; -- blocks\ncommit; | -- we are unblocked\n | insert into t values(2);\n | commit;\n```\n\nThis is all good. It may be disappointing that SQLite only allows one simultaneous writer, but at least this is clear, and by waiting for a bit, our writes do happen (sequentially). If we leave the transaction on the left open for too long, the right side will get a SQLITE\\_BUSY error:\n\n```\nRuntime error: database is locked (5)\n```\n\nFiguring out the right timeout is not easy. But, if you get a timeout, you can reconsider, and perhaps decide to wait even longer.\n\n# Getting into trouble\n\nAs noted, if you BEGIN a transaction in SQLite without specifying ‘immediate’, SQLite actually only begins a transaction after you submit the first statement, and it will pick the _kind_ of transaction based on that first statement (read-only or read-write).\n\nIf you later in a read-only transaction try to write to the database somehow, SQLite will attempt to _upgrade_ your transaction to a write transaction. And this is where we can run into problems:\n\n```\n | begin;\nbegin; | insert into t values(2);\nselect count(1) from t; | -- we are in a WRITE transaction\ninsert into t values(3); |\nRuntime error: database is locked (5) -- immediately\n=== SO corrupt key parts ===\nAlready have an account? [Log in](https://stackoverflow.com/users/login)\n\n[Skip to main content](https://stackoverflow.com/questiLine truncated
|
||||
{"type":"step_finish","timestamp":1788905570291,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314bfdd001lC8YjBoSY","reason":"tool-calls","snapshot":"62bd298e8705720471d5a682bf309a04c9ac4d6a","messageID":"msg_g001a08314a299001twziD4Pzr","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":46805,"input":26984,"output":109,"reasoning":0,"cache":{"write":0,"read":19712}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905573568,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314ccbd001hCGtVVKNj","messageID":"msg_g001a08314c015001OhlxH8yRd","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"f3791436bd633227930d2a8402c57a7b17552378","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905575755,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_d61d53493ce4440682872e7a","state":{"status":"completed","input":{"command":"grep -A 30 -i \"crashed after having opened\" s-so-corrupt.md | head -40; echo ===; grep -B2 -A 15 -iE \"checkpoint starvation|WAL mode is slower|WAL mode is about\" s-bugsink.md s-aviim.md 2>/dev/null | head -20","description":"Extract SO corruption answer details","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"I ask because ever since I've adopted WAL, I frequently am seeing reports of malformed databases. This seems to mostly occur if a process crashed after having opened a connection (doesn't matter if it's opened with a `SQLITE_OPEN_READONLY` flag or not) and another process had already opened a connection or later opened one. I can't always reproduce this reliably but it seems it has something to do with the -shm and -wal index files having been created by one process and the other process either had a copy of its own in memory or there was some mismatch produced somehow. Not that this should be the case, but could it be that the -shm file used by the new process somehow modifies it (or the .db file) without the first process finding out, and thus leading to a corrupt database (as already noted under 2.4 of How to Corrupt SQLite)?\n\nMy only guess is that having two processes write to the same db is the root cause of these corrupt instances. If this is true, how are we to coordinate between two separate processes without complex inter-process communication in place? Any ideas? I don't want to resort to using `journal_mode=DELETE` given I've got a highly multi-threaded application which otherwise benefits from concurrent readers and a single writer.\n\nBy the way, this is how I open a reader (multiple readers are opened by multiple threads concurrently):\n\n```objectivec\nCopy\nNSString *path = ...\n\nsqlite3 *readOnlyDB = NULL;\n\nBOOL dbOpened = (sqlite3_open_v2(path.UTF8String, &readOnlyDB, SQLITE_OPEN_READONLY | SQLITE_OPEN_WAL, NULL) == SQLITE_OK);\n\nsqlite3_exec(readOnlyDB, \"PRAGMA read_uncommitted=1; PRAGMA query_only=1; PRAGMA synchronous=normal;\", NULL, NULL, NULL);\nsqlite3_unicode_init(readOnlyDB);\nsqlite3_busy_timeout(readOnlyDB, 2000)\n\n// I register custom functions here for the connection\n```\n\nAnd this is how I am opening a writer (a single writer exists for a single process):\n\n```objectivec\nCopy\nBOOL dbOpened = (sqlite3_open_v2(path.UTF8String, &dbConnection, SQLITE_OPEN_READWRITE | SQLITE_OPEN_CREATE, NULL) == SQLITE_OK);\n\nsqlite3_exec(dbConnection, \"PRAGMA main.journal_mode=WAL; PRAGMA synchronous=normal;\", NULL, NULL, NULL);\nsqlite3_unicode_init(dbConnection);\nsqlite3_busy_timeout(dbConnection, 2000);\n\nzsh:1: == not found\n","metadata":{"output":"I ask because ever since I've adopted WAL, I frequently am seeing reports of malformed databases. This seems to mostly occur if a process crashed after having opened a connection (doesn't matter if it's opened with a `SQLITE_OPEN_READONLY` flag or not) and another process had already opened a connection or later opened one. I can't always reproduce this reliably but it seems it has something to do with the -shm and -wal index files having been created by one process and the other process either had a copy of its own in memory or there was some mismatch produced somehow. Not that this should be the case, but could it be that the -shm file used by the new process somehow modifies it (or the .db file) without the first process finding out, and thus leading to a corrupt database (as already noted under 2.4 of How to Corrupt SQLite)?\n\nMy only guess is that having two processes write to the same db is the root cause of these corrupt instances. If this is true, how are we to coordinate between two separate processes without complex inter-process communication in place? Any ideas? I don't want to resort to using `journal_mode=DELETE` given I've got a highly multi-threaded application which otherwise benefits from concurrent readers and a single writer.\n\nBy the way, this is how I open a reader (multiple readers are opened by multiple threads concurrently):\n\n```objectivec\nCopy\nNSString *path = ...\n\nsqlite3 *readOnlyDB = NULL;\n\nBOOL dbOpened = (sqlite3_open_v2(path.UTF8String, &readOnlyDB, SQLITE_OPEN_READONLY | SQLITE_OPEN_WAL, NULL) == SQLITE_OK);\n\nsqlite3_exec(readOnlyDB, \"PRAGMA read_uncommitted=1; PRAGMA query_only=1; PRAGMA synchronous=normal;\", NULL, NULL, NULL);\nsqlite3_unicode_init(readOnlyDB);\nsqlite3_busy_timeout(readOnlyDB, 2000)\n\n// I register custom functions here for the connection\n```\n\nAnd this is how I am opening a writer (a single writer exists for a single process):\n\n```objectivec\nCopy\nBOOL dbOpened = (sqlite3_open_v2(path.UTF8String, &dbConnection, SQLITE_OPEN_READWRITE | SQLITE_OPEN_CREATE, NULL) == SQLITE_OK);\n\nsqlite3_exec(dbConnectLine truncated
|
||||
{"type":"step_finish","timestamp":1788905575783,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314d54b001L4WpBgWnq","reason":"tool-calls","snapshot":"667b75853c393777ca625d45f93b3738730c4b02","messageID":"msg_g001a08314c015001OhlxH8yRd","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":48506,"input":1670,"output":116,"reasoning":0,"cache":{"write":0,"read":46720}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905581960,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314ed870017dspIsbk9","messageID":"msg_g001a08314d588001BmS6r6hEM","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"1ee9f088ea96542a324add7b8443ebd120026db5","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905583878,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_a0d2d6b4192d406eb80ecc17","state":{"status":"completed","input":{"command":"grep -A 25 -iE \"^#{1,3} |Answer\" s-so-corrupt.md | grep -A 25 -iE \"corrupt an|How to Corrupt|answer\" | head -40","description":"Find accepted answer in SO corruption question","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":" Detailed answers to any questions you might have](https://stackoverflow.com/help)\n - [Meta\\\\\n \\\\\n Discuss the workings and policies of this site](https://meta.stackoverflow.com/)\n - [About Us\\\\\n \\\\\n Learn more about Stack Overflow the company, and our products](https://stackoverflow.co/)\n\n2. [Site switcher](https://stackexchange.com/)\nA list of all 184 Stack Overflow communities\n\n3. ### [current community](https://stackoverflow.com/)\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n--\n[Use comments to ask for more information or suggest improvements. Avoid answering questions in comments.](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database# \"Use comments to ask for more information or suggest improvements. Avoid answering questions in comments.\") \\| [Show **1** more comment](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database# \"Expand to show all comments on this post\")\n\n## 1 Answer 1\n\nSorted by:\n[Reset to default](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database?answertab=scoredesc#tab-top)\n\nHighest score (default)\n\nTrending (recent votes count more)\n\nDate modified (newest first)\n\n","metadata":{"output":" Detailed answers to any questions you might have](https://stackoverflow.com/help)\n - [Meta\\\\\n \\\\\n Discuss the workings and policies of this site](https://meta.stackoverflow.com/)\n - [About Us\\\\\n \\\\\n Learn more about Stack Overflow the company, and our products](https://stackoverflow.co/)\n\n2. [Site switcher](https://stackexchange.com/)\nA list of all 184 Stack Overflow communities\n\n3. ### [current community](https://stackoverflow.com/)\n\n\n\n\n\n\n\n\n\n\n\n\n\n\n--\n[Use comments to ask for more information or suggest improvements. Avoid answering questions in comments.](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database# \"Use comments to ask for more information or suggest improvements. Avoid answering questions in comments.\") \\| [Show **1** more comment](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database# \"Expand to show all comments on this post\")\n\n## 1 Answer 1\n\nSorted by:\n[Reset to default](https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database?answertab=scoredesc#tab-top)\n\nHighest score (default)\n\nTrending (recent votes count more)\n\nDate modified (newest first)\n\n","exit":0,"description":"Find accepted answer in SO corruption question","truncated":false},"title":"Find accepted answer in SO corruption question","time":{"start":1788905583874,"end":1788905583876}},"id":"prt_g001a08314ed880016O3yxzWPB","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08314d588001BmS6r6hEM"}}
|
||||
{"type":"step_finish","timestamp":1788905583896,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08314f506001wfG99GDjE","reason":"tool-calls","snapshot":"a37aca81e5966c04c15bf87a7b3fe4cae990b066","messageID":"msg_g001a08314d588001BmS6r6hEM","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":49117,"input":577,"output":92,"reasoning":0,"cache":{"write":0,"read":48448}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905591557,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083151303001kJMSectOk","messageID":"msg_g001a08314f5380019e2Ens960","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"faf6f30f0eb3504220d447d0f5a412239d7589b6","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905593176,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"bash","callID":"call_9aa7bbb19ae049fea1efd2ba","state":{"status":"completed","input":{"command":"grep -A 40 \"## 1 Answer 1\" s-so-corrupt.md | tail -35","description":"Read SO accepted answer body","workdir":"/mnt/workdrive/research-stage/research/issue-262/.firecrawl"},"output":"\nTrending (recent votes count more)\n\nDate modified (newest first)\n\nDate created (oldest first)\n\n\nThis answer is useful\n\n2\n\nThis answer is not useful\n\nSave this answer.\n\nLoading when this answer was accepted…\n\n[Timeline](https://stackoverflow.com/posts/49579461/timeline)\n\nShow activity on this post.\n\nI have had a similar issue with SQLite3 using Python client on Linux: DB file getting malformed when client crashes while inside an open transaction, while another concurrent process performs read/write query.\n\nThat issue resolved after I added exception handler to make sure transaction closes before crashing process terminates.\n\n[Share](https://stackoverflow.com/a/49579461)\n\nShare a link to this answer\n\nCopy link [CC BY-SA 3.0](https://creativecommons.org/licenses/by-sa/3.0/ \"The current license for this post: CC BY-SA 3.0\")\n\nShort permalink to this answer\n\n[Improve this answer](https://stackoverflow.com/posts/49579461/edit \"\")\n","metadata":{"output":"\nTrending (recent votes count more)\n\nDate modified (newest first)\n\nDate created (oldest first)\n\n\nThis answer is useful\n\n2\n\nThis answer is not useful\n\nSave this answer.\n\nLoading when this answer was accepted…\n\n[Timeline](https://stackoverflow.com/posts/49579461/timeline)\n\nShow activity on this post.\n\nI have had a similar issue with SQLite3 using Python client on Linux: DB file getting malformed when client crashes while inside an open transaction, while another concurrent process performs read/write query.\n\nThat issue resolved after I added exception handler to make sure transaction closes before crashing process terminates.\n\n[Share](https://stackoverflow.com/a/49579461)\n\nShare a link to this answer\n\nCopy link [CC BY-SA 3.0](https://creativecommons.org/licenses/by-sa/3.0/ \"The current license for this post: CC BY-SA 3.0\")\n\nShort permalink to this answer\n\n[Improve this answer](https://stackoverflow.com/posts/49579461/edit \"\")\n","exit":0,"description":"Read SO accepted answer body","truncated":false},"title":"Read SO accepted answer body","time":{"start":1788905593172,"end":1788905593175}},"id":"prt_g001a083151304001Yk3UhP4bD","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","messageID":"msg_g001a08314f5380019e2Ens960"}}
|
||||
{"type":"step_finish","timestamp":1788905593198,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083151958001a4RPLPIft","reason":"tool-calls","snapshot":"87d88058f3d28832df4234795c8997ad06635c53","messageID":"msg_g001a08314f5380019e2Ens960","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":49482,"input":393,"output":65,"reasoning":0,"cache":{"write":0,"read":49024}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905599306,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a083153149001Gg4u23dcl","messageID":"msg_g001a0831519940014fuQoOyZT","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","snapshot":"beac9ddc7adc19d056f915a66647c6a62a8100e1","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905682363,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a08315314a001vJ1fs08C4","messageID":"msg_g001a0831519940014fuQoOyZT","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"text","text":"I have enough adversarial evidence. Let me write the `adversarial.json` artifact now.","time":{"start":1788905599306,"end":1788905682360}}}
|
||||
{"type":"tool_use","timestamp":1788905682366,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"type":"tool","tool":"write","callID":"call_c90b0654cc9f4bcea797ca87","state":{"status":"completed","input":{"content":"{\n \"process_id\": \"research-262-r1\",\n \"issue\": 262,\n \"round\": 1,\n \"stage\": \"ADVERSARIAL\",\n \"title\": \"sqlite WAL performance in concurrent Python applications (acceptance-test question, repo-specific)\",\n \"method_note\": \"New searches this stage (6 firecrawl queries, 4 full-page scrapes) targeted EXCLUSIVELY at counter-evidence to the emerging preferred approach inferred from DEFINE + INWARD + OUTWARD_READING: 'WAL mode + per-connection PRAGMA stack (busy_timeout, synchronous=NORMAL) + BEGIN IMMEDIATE + retry, validated by a pytest(-benchmark) acceptance test over Rune's multi-process topology.' Sources S1-S11 from OUTWARD_READING are referenced by ID; new adversarial sources are A1-A7. No advocacy for the preferred approach is included, per stage contract.\",\n \"preferred_approach_under_attack\": \"Enable WAL on Rune's SQLite databases; apply a hardened PRAGMA stack (busy_timeout, synchronous=NORMAL, wal_autocheckpoint) on every fresh per-call connection; use BEGIN IMMEDIATE for known-write transactions; retry on SQLITE_BUSY; validate with a pytest-based multi-process acceptance test (pytest-benchmark for perf assertions) asserting checkpoint progress after stale-reader release.\",\n \"attacks\": [\n {\n \"id\": \"X1\",\n \"target\": \"Core premise: WAL improves Rune's concurrency/performance\",\n \"attack\": \"WAL does not help Rune's actual bottleneck and may regress writes. (a) WAL adds an extra copy of every committed page (write amplification): commits go to the WAL AND must later be copied back to the main DB by checkpoints, so write throughput can be LOWER than journal_mode=DELETE for insert-heavy workloads (A2 reddit r/sqlite; A3 sqlite.org/forum 117c91891cf7ac15 'WAL is about concurrency, not speed'). (b) OUTWARD_READING's own S3 found WAL did NOT raise the concurrent-write ceiling (~500 simultaneous inserts failed identically with and without WAL, O8) — the repo's own workload (per-call fresh connections writing, I2/I4) is exactly the write-heavy multi-writer case WAL cannot scale: exactly one writer at a time (S1/O1). (c) S4's production incident (O9) shows multi-process writers on shared storage losing committed orders even in WAL. If Rune's pain is writer/writer contention, WAL is not the treatment and the acceptance test built around WAL success criteria measures the wrong thing.\",\n \"severity\": \"HIGH\",\n \"sources\": [\"A2\", \"A3\", \"S3/O8\", \"S1/O1\", \"S4/O9\"]\n },\n {\n \"id\": \"X2\",\n \"target\": \"busy_timeout as the primary SQLITE_BUSY mitigation\",\n \"attack\": \"busy_timeout has documented holes that retry logic alone does not patch. (a) In deferred transactions, a read that upgrades to write later gets SQLITE_BUSY IMMEDIATELY, ignoring busy_timeout entirely — the classic fix is BEGIN IMMEDIATE for known-write transactions (A4 berthub.eu, confirmed by sqlite.org forum + Simon Willison notes; also HN 45781519). This contradicts any design that applies busy_timeout and expects writers to queue: only BEGIN IMMEDIATE transactions actually wait. (b) S6's diagnostic runbook: PASSIVE checkpoints ALWAYS return busy=0 — a monitoring/assertion scheme reading the busy column will systematically report 'no contention' during starvation. (c) WAL checkpoints bypass the busy handler in some paths: concurrent checkpoint attempts return SQLITE_BUSY without invoking the busy handler at all (S2/O6), so connection-level busy_timeout does not help checkpoint coordination; explicit retry-at-app-level is mandatory, not optional. The preferred approach as stated ('set busy_timeout, retry') is insufficient; the test must distinguish deferred-upgrade BUSY (immediate, un-timed) from writer-queue BUSY (timed).\",\n \"severity\": \"HIGH\",\n \"sources\": [\"A4\", \"S2/O6\", \"S6/O11\"]\n },\n {\n \"id\": \"X3\",\n \"target\": \"Per-connection PRAGMA stack + fresh connections per call (Rune's topology, reinforced by S8/O14)\",\n \"attack\": \"The fresh-connection-per-call pattern is itself the cost center, and the preferred approach bakes it in rather than questioning it. Connections are expensive (they correspond to opening the file); reopening per call has measurable overhead (A5 SO 3747232; HN 44530518 'opening and closing SQLite connections is expensive... reuse is much faster'). A simpler alternative that the preferred approach does not consider: a single dedicated DB-writer thread fed by a queue (community-standard answer, S11/O18) or a persistent connection/pool per process eliminates BOTH the per-connect PRAGMA stack cost AND the sqlite-vec per-connection extension-load cost (curator.py:695, I3/I5 mapping) that the acceptance test would otherwise just accept as fixLine truncated
|
||||
{"type":"step_finish","timestamp":1788905682391,"sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","part":{"id":"prt_g001a0831675be001fphLKBRdV","reason":"tool-calls","snapshot":"790d5870f5536fd57bdfc04ba415bf0229cca1c1","messageID":"msg_g001a0831519940014fuQoOyZT","sessionID":"ses_-ffe5f7cedfc3cffe4Jz3Ie6ag","type":"step-finish","tokens":{"total":53142,"input":225,"output":3445,"reasoning":0,"cache":{"write":0,"read":49472}},"cost":0}}
|
||||
@@ -0,0 +1,31 @@
|
||||
{"type":"step_start","timestamp":1788903183369,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f05406001xvHVF7Vb7","messageID":"msg_g001a082efdc65001R24Irp61d","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"0119ac241b8e376eaada712253a14b1411ab27bd","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903228162,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f0f5df001lGozOPGD5","messageID":"msg_g001a082efdc65001R24Irp61d","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"I'll start by searching for a matching skill (required for first query), then ground the queries in the repo's SQLite usage before discovering external prior art.","time":{"start":1788903224799,"end":1788903228159}}}
|
||||
{"type":"tool_use","timestamp":1788903228165,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"skill_search","callID":"call_151a6232c2a649fb9e492ac4","state":{"status":"completed","input":{"query":"Action: run outward discovery for a structured research pipeline — generate web search strategies and discover/classify prior-art URLs (no full reading) about SQLite WAL performance in concurrent Python applications for an acceptance-test design question. Input: research contract (issue 262) + repo files (memory_store.py etc). Output: structured stage artifact (outward_discovery.json) with queries, URLs, source-type classification. Audience: downstream research stages."},"output":"{\n \"status\": \"matched\",\n \"results\": [\n {\n \"skill_id\": \"firecrawl-search\",\n \"name\": \"firecrawl-search\",\n \"score\": 0.6096,\n \"reason\": \"The skill description matches these query terms: research, web, search, discover, full, about, in, source.\"\n },\n {\n \"skill_id\": \"memory-search\",\n \"name\": \"memory-search\",\n \"score\": 0.5334,\n \"reason\": \"The skill description matches these query terms: structured, search, strategie, sqlite, in, memory.\"\n },\n {\n \"skill_id\": \"firecrawl\",\n \"name\": \"firecrawl\",\n \"score\": 0.3975,\n \"reason\": \"The skill description matches these query terms: research, web, search, url, full, in, file.\"\n }\n ],\n \"loaded_skill_id\": null\n}","metadata":{"status":"matched","loadedSkillID":null,"truncated":false},"title":"Found 3 skills","time":{"start":1788903228161,"end":1788903228163}},"id":"prt_g001a082f10274001VfAqCXWK9","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","messageID":"msg_g001a082efdc65001R24Irp61d"}}
|
||||
{"type":"step_finish","timestamp":1788903228189,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f10305001UrwWXzt6c","reason":"tool-calls","snapshot":"409b142aeb170991e250def4f3711ffd0803fa79","messageID":"msg_g001a082efdc65001R24Irp61d","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":30594,"input":28952,"output":130,"reasoning":1448,"cache":{"write":0,"read":64}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788903234481,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f11bae001KZCRtQpLy","messageID":"msg_g001a082f10342001npUI8NT0Y","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"551a9d7dd7ff42ac1cc5be317a2f71dd23243eff","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903245947,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f13f5c001fSD55yT4b","messageID":"msg_g001a082f10342001npUI8NT0Y","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"No exact skill match (firecrawl-search is a partial hit — useful for the actual web searching). This is a stage in an orchestrated research process, so I'll proceed stage-wise: first ground the queries in the repo's actual SQLite usage, then discover external prior-art URLs.","time":{"start":1788903243612,"end":1788903245944}}}
|
||||
{"type":"tool_use","timestamp":1788903245989,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"grep","callID":"call_aab53a19a4a54f3da2071401","state":{"status":"completed","input":{"include":"*.py","path":"src/rune","pattern":"sqlite|WAL|journal_mode|busy_timeout|PRAGMA"},"output":"Found 135 matches (showing first 100)\n/mnt/workdrive/research-stage/src/rune/rune_tui.py:\n Line 189: elif \"sqlite\" in error_msg.lower() or \"OperationalError\" in error_type:\n\n\n/mnt/workdrive/research-stage/src/rune/canary_gitea_automation.py:\n Line 207: \"PRAGMA integrity_check\" in restore_script\n\n\n/mnt/workdrive/research-stage/src/rune/memory_store.py:\n Line 5: file running sqlite-vec (dense vectors) + FTS5 (BM25) side by side.\n\n Line 26: Run under ~/.venvs/memory/bin/python3 (has sqlite-vec).\n\n Line 34: import sqlite3\n\n Line 98: cols = {row[1] for row in db.execute(\"PRAGMA table_info(entries)\")}\n\n Line 119: db = sqlite3.connect(target)\n\n Line 120: db.row_factory = sqlite3.Row\n\n Line 122: import sqlite_vec\n\n Line 124: sqlite_vec.load(db)\n\n Line 212: cols = {r[1] for r in db.execute(\"PRAGMA table_info(entries)\")}\n\n Line 232: ccols = {r[1] for r in db.execute(\"PRAGMA table_info(chunks)\")}\n\n Line 1513: # sqlite-vec rowid = sqlite rowid of the chunks table row.\n\n\n/mnt/workdrive/research-stage/src/rune/warm_router.py:\n Line 76: import sqlite3\n\n Line 77: db = sqlite3.connect(STORE_DB)\n\n Line 105: import sqlite3\n\n Line 108: db = sqlite3.connect(STORE_DB)\n\n Line 123: import sqlite3\n\n Line 126: db = sqlite3.connect(STORE_DB)\n\n Line 147: import sqlite3\n\n Line 155: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 193: import sqlite3\n\n Line 194: return sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 276: import sqlite3\n\n Line 278: db = sqlite3.connect(STORE_DB)\n\n Line 306: dbw = sqlite3.connect(STORE_DB)\n\n Line 684: import sqlite3\n\n Line 685: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 854: import sqlite3\n\n Line 855: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 932: import sqlite3\n\n Line 933: db = sqlite3.connect(STORE_DB)\n\n Line 935: db.row_factory = sqlite3.Row\n\n\n/mnt/workdrive/research-stage/src/rune/shard_manager.py:\n Line 7: Each shard has its own FTS5 + sqlite-vec index for fast retrieval.\n\n Line 16: import sqlite3\n\n Line 55: db = sqlite3.connect(shard_path)\n\n Line 57: import sqlite_vec\n\n Line 59: sqlite_vec.load(db) # #26: entries_vec virtual table needs the extension per connection\n\n Line 121: def get_shard(self, topic: str) -> sqlite3.Connection:\n\n Line 124: #26 defect fix: virtual tables (entries_vec) require the sqlite-vec\n\n Line 132: db = sqlite3.connect(shard_path)\n\n Line 133: db.row_factory = sqlite3.Row\n\n Line 135: import sqlite_vec\n\n Line 137: sqlite_vec.load(db)\n\n Line 164: db = sqlite3.connect(path)\n\n\n/mnt/workdrive/research-stage/src/rune/sleep_time.py:\n Line 22: import sqlite3\n\n Line 78: return sqlite3.connect(f\"file:{DB}?mode=ro\", uri=True)\n\n Line 79: except sqlite3.Error as e:\n\n Line 495: db = sqlite3.connect(f\"file:{DB}?mode=ro\", uri=True)\n\n Line 497: db.row_factory = sqlite3.Row\n\n\n/mnt/workdrive/research-stage/src/rune/canary_native.py:\n Line 94: \"memory_store\": [], # Skip connect test due to sqlite_vec dependency\n\n\n/mnt/workdrive/research-stage/src/rune/curator.py:\n Line 31: import sqlite3\n\n Line 132: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 147: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 173: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 216: import sqlite3\n\n Line 217: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 241: import sqlite3\n\n Line 242: db = sqlite3.connect(f\"file:{STORE_DB}?mode=ro\", uri=True)\n\n Line 258: import sqlite3\n\n Line 260: db = sqlite3.connect(STORE_DB)\n\n Line 695: for scalability (eliminates Python startup + sqlite-vec load per call).\"\"\"\n\n\n/mnt/workdrive/research-stage/src/rune/task_gate.py:\n Line 22: import sqlite3\n\n Line 41: db = sqlite3.connect(DB_PATH)\n\n Line 43: db.row_factory = sqlite3.Row\n\n Line 44: db.execute(\"PRAGMA journal_mode=WAL\")\n\n\n/mnt/workdrive/research-stage/src/rune/voice_sync.py:\n Line 17: import sqlite3\n\n Line 49: db = sqlite3.connect(STORE_DB)\n\n Line 50: db.row_factory = sqlite3.Row\n\n\n/mnt/workdrive/research-stage/src/rune/Line truncated
|
||||
{"type":"tool_use","timestamp":1788903246023,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"bash","callID":"call_34d5091ca5f34be9979eb3f5","state":{"status":"completed","input":{"command":"git log --oneline -5 2>/dev/null; ls src/rune/ | head -30","description":"Show recent commits and rune module files"},"output":"83ea89c feat(research): OUTWARD_DISCOVERY executor — real MiMo discovery with structured artifact\nb8280ae merge master\nd4a4222 feat(research): stage-trigger boundary executor — one event = one stage, idempotency guard, no self-walking\nd568705 chore(research): record local backend execution evidence (DEFINE+INWARD completed, tree on master)\n2c8d33e research: persist tree after OUTWARD_DISCOVERY (issue #261, round 1)\nabstraction.py\nattention_capsule.py\naudit_ledger.py\nauto_context.py\nauto_tasks.py\nbehavior.py\nbuild_mode.py\ncache.py\ncanary_cognitive_strata.py\ncanary_context_broker.py\ncanary_conversation_state.py\ncanary_full_system.py\ncanary_gitea_automation.py\ncanary_gitea_delegation.py\ncanary_gitea_pipeline.py\ncanary_memory_synthesis.py\ncanary_native.py\ncanary_orchestration_foundation.py\ncanary_p0_04.py\ncanary_p0_05.py\ncanary_p0_07.py\ncanary_p1_01.py\ncanary_p1_02.py\ncanary_p1_03.py\ncanary_p1_06.py\ncanary_p1_07.py\ncanary_query_memory.py\ncanary_resource_authority.py\ncanary_schema_migration.py\ncanary_surface_parity.py\n","metadata":{"output":"83ea89c feat(research): OUTWARD_DISCOVERY executor — real MiMo discovery with structured artifact\nb8280ae merge master\nd4a4222 feat(research): stage-trigger boundary executor — one event = one stage, idempotency guard, no self-walking\nd568705 chore(research): record local backend execution evidence (DEFINE+INWARD completed, tree on master)\n2c8d33e research: persist tree after OUTWARD_DISCOVERY (issue #261, round 1)\nabstraction.py\nattention_capsule.py\naudit_ledger.py\nauto_context.py\nauto_tasks.py\nbehavior.py\nbuild_mode.py\ncache.py\ncanary_cognitive_strata.py\ncanary_context_broker.py\ncanary_conversation_state.py\ncanary_full_system.py\ncanary_gitea_automation.py\ncanary_gitea_delegation.py\ncanary_gitea_pipeline.py\ncanary_memory_synthesis.py\ncanary_native.py\ncanary_orchestration_foundation.py\ncanary_p0_04.py\ncanary_p0_05.py\ncanary_p0_07.py\ncanary_p1_01.py\ncanary_p1_02.py\ncanary_p1_03.py\ncanary_p1_06.py\ncanary_p1_07.py\ncanary_query_memory.py\ncanary_resource_authority.py\ncanary_schema_migration.py\ncanary_surface_parity.py\n","exit":0,"description":"Show recent commits and rune module files","truncated":false},"title":"Show recent commits and rune module files","time":{"start":1788903246016,"end":1788903246021}},"id":"prt_g001a082f1483b001SPeX3blQ7","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","messageID":"msg_g001a082f10342001npUI8NT0Y"}}
|
||||
{"type":"step_finish","timestamp":1788903246046,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f148c6001rCQxolP2Y","reason":"tool-calls","snapshot":"20518245669477e96756cf8ce7b4844f1927bd5e","messageID":"msg_g001a082f10342001npUI8NT0Y","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":29946,"input":362,"output":136,"reasoning":456,"cache":{"write":0,"read":28992}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788903252725,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f162f2001nV0h8jUp9","messageID":"msg_g001a082f148fe001NFQTZ4js3","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"89cba376d777fea3a20bca71c56c15fe52f6cbab","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903276041,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f1b0fd0017Xbi2hRrk","messageID":"msg_g001a082f148fe001NFQTZ4js3","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"Grounding established: the repo opens many short-lived `sqlite3.connect` calls per process (warm_router, curator, sleep_time, self_improve…), some `mode=ro`, some RW, with `PRAGMA journal_mode=WAL` in task_gate.py — a classic multi-process concurrent SQLite setup. Now I'll discover external prior art via web searches (titles/snippets only — no full-source reading).","time":{"start":1788903272701,"end":1788903276039}}}
|
||||
{"type":"tool_use","timestamp":1788903276847,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_540d371acf984f73a3b5a8bc","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=sqlite+WAL+concurrency+python+%22database+is+locked%22+busy_timeout"},"output":" sqlite WAL concurrency python \"database is locked\" busy\\_timeout at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [SQLite Error: Database Is Locked (Fix Guide) | AI2SQL](//duckduckgo.com/l/?uddg=https%3A%2F%2Fbuilder.ai2sql.io%2Fblog%2Fsqlite%2Derror%2Ddatabase%2Dis%2Dlocked&rut=72b2c51c06f2dc17b127e8661b8b4d88e9dad78c1e4b09a165d93ffb5a467d6f)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fbuilder.ai2sql.io%2Fblog%2Fsqlite%2Derror%2Ddatabase%2Dis%2Dlocked&rut=72b2c51c06f2dc17b127e8661b8b4d88e9dad78c1e4b09a165d93ffb5a467d6f)[builder.ai2sql.io/blog/sqlite-error-database-is-locked](//duckduckgo.com/l/?uddg=https%3A%2F%2Fbuilder.ai2sql.io%2Fblog%2Fsqlite%2Derror%2Ddatabase%2Dis%2Dlocked&rut=72b2c51c06f2dc17b127e8661b8b4d88e9dad78c1e4b09a165d93ffb5a467d6f) 2026-03-12T00:00:00.0000000\n\n[Fix **SQLite** **database is locked** error. Covers **WAL** mode, **busy** **timeout,** concurrent access patterns, and write locking strategies.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fbuilder.ai2sql.io%2Fblog%2Fsqlite%2Derror%2Ddatabase%2Dis%2Dlocked&rut=72b2c51c06f2dc17b127e8661b8b4d88e9dad78c1e4b09a165d93ffb5a467d6f)\n\n## [Fix SQLite SQLITE\\_BUSY (5): Database is Locked — pgref.dev](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.errcodes.dev%2Fsqlite%2Fsqlite%2Dbusy%2Ddatabase%2Dlocked&rut=1b59fa219eb649c5f5397191e952d0bf69861c1bf45e443f1b9f406de19736b3)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.errcodes.dev%2Fsqlite%2Fsqlite%2Dbusy%2Ddatabase%2Dlocked&rut=1b59fa219eb649c5f5397191e952d0bf69861c1bf45e443f1b9f406de19736b3)[www.errcodes.dev/sqlite/sqlite-busy-database-locked](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.errcodes.dev%2Fsqlite%2Fsqlite%2Dbusy%2Ddatabase%2Dlocked&rut=1b59fa219eb649c5f5397191e952d0bf69861c1bf45e443f1b9f406de19736b3)\n\n[Why this works **busy\\_timeout** instructs the **SQLite** library to sleep and retry the lock acquisition for up to the specified number of milliseconds before returning SQLITE\\_BUSY. The **Python** sqlite3 module exposes this as the timeout parameter on connect (). Fix 2 Enable **WAL** mode for better read/write **concurrency**](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.errcodes.dev%2Fsqlite%2Fsqlite%2Dbusy%2Ddatabase%2Dlocked&rut=1b59fa219eb649c5f5397191e952d0bf69861c1bf45e443f1b9f406de19736b3)\n\n## [SQLite Database Is Locked: Fix SQLITE\\_BUSY — sqlfmt](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.sqlfmt.app%2Fblog%2Fsqlite%2Ddatabase%2Dis%2Dlocked&rut=64dfbb75de48eb2c9043ecfad7d207343bd394e8194f516da17a2c4a79527dfb)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.sqlfmt.app%2Fblog%2Fsqlite%2Ddatabase%2Dis%2Dlocked&rut=64dfbb75de48eb2c9043ecfad7d207343bd394e8194f516da17a2c4a79527dfb)[www.sqlfmt.app/blog/sqlite-database-is-locked](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.sqlfmt.app%2Fblog%2Fsqlite%2Ddatabase%2Dis%2Dlocked&rut=64dfbb75de48eb2c9043ecfad7d207343bd394e8194f516da17a2c4a79527dfb) 2026-08-26T00:00:00.0000000\n\n[**SQLite** \"**database is locked**\" usually means a connection needs a lock that another connection holds. Keep write transactions short, configure an appropriate **busy** **timeout,** use **WAL** for the right workload, and distinguish SQLITE\\_BUSY from SQLITE\\_LOCKED before changing files.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.sqlfmt.app%2Fblog%2Fsqlite%2Ddatabase%2Dis%2Dlocked&rut=64dfbb75de48eb2c9043ecfad7d207343bd394e8194f516da17a2c4a79527dfb)\n\n## [SQLite Errors: Common Issues and How to Fix Them | OpenPython](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.openpython.org%2Farticles%2Fsqlite%2Derrors&rut=5eed8069c82b1b98b6f05c414256885f536e39b8fc94b6d37b186175e93806af)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.openpython.org%2Line truncated
|
||||
{"type":"tool_use","timestamp":1788903276899,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_ab73f82b594d41b292df2d4d","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=sqlite+wal+checkpoint+starvation+stall+production+issues"},"output":" sqlite wal checkpoint starvation stall production issues at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [SQLite WAL Checkpoint Starvation Diagnostics - GitHub](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fmouadja02%2Fskills%2Fblob%2Fmain%2Fskills%2Fdatabases%2Fsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics%2FSKILL.md&rut=3a7cd954aad27179c5bfb9a81193ca49dcde52ac19429f6ceaa3000bd7c9c186)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fmouadja02%2Fskills%2Fblob%2Fmain%2Fskills%2Fdatabases%2Fsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics%2FSKILL.md&rut=3a7cd954aad27179c5bfb9a81193ca49dcde52ac19429f6ceaa3000bd7c9c186)[github.com/mouadja02/skills/blob/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fmouadja02%2Fskills%2Fblob%2Fmain%2Fskills%2Fdatabases%2Fsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics%2FSKILL.md&rut=3a7cd954aad27179c5bfb9a81193ca49dcde52ac19429f6ceaa3000bd7c9c186)\n\n[**SQLite** **WAL** **Checkpoint** **Starvation** Diagnostics Diagnose a **WAL** that cannot reset without deleting journal files or turning a **production** incident into a write outage. Separate copying frames into the database from resetting/truncating the **WAL**: a **checkpoint** can make progress while an older reader still prevents reset.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fmouadja02%2Fskills%2Fblob%2Fmain%2Fskills%2Fdatabases%2Fsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics%2FSKILL.md&rut=3a7cd954aad27179c5bfb9a81193ca49dcde52ac19429f6ceaa3000bd7c9c186)\n\n## [sqlite-wal-checkpoint-starvation... | Agent Skill | SkillsMP](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskillsmp.com%2Fcreators%2Fmouadja02%2Fskills%2Fskills%2Ddatabases%2Dsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics&rut=37dd3bcbd593649ade0551473dbe4a9b88f2567fb6ff1c73be72bee0ee7a9935)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskillsmp.com%2Fcreators%2Fmouadja02%2Fskills%2Fskills%2Ddatabases%2Dsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics&rut=37dd3bcbd593649ade0551473dbe4a9b88f2567fb6ff1c73be72bee0ee7a9935)[skillsmp.com/creators/mouadja02/skills/skills-databases-sqlite-wal-checkpoint-starvation-diagnostics](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskillsmp.com%2Fcreators%2Fmouadja02%2Fskills%2Fskills%2Ddatabases%2Dsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics&rut=37dd3bcbd593649ade0551473dbe4a9b88f2567fb6ff1c73be72bee0ee7a9935)\n\n[**SQLite** **WAL** **Checkpoint** **Starvation** Diagnostics Diagnose a **WAL** that cannot reset without deleting journal files or turning a **production** incident into a write outage. Separate copying frames into the database from resetting/truncating the **WAL**: a **checkpoint** can make progress while an older reader still prevents reset.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskillsmp.com%2Fcreators%2Fmouadja02%2Fskills%2Fskills%2Ddatabases%2Dsqlite%2Dwal%2Dcheckpoint%2Dstarvation%2Ddiagnostics&rut=37dd3bcbd593649ade0551473dbe4a9b88f2567fb6ff1c73be72bee0ee7a9935)\n\n## [necat101/sqlite-deployment-safety-lab - GitHub](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fnecat101%2Fsqlite%2Ddeployment%2Dsafety%2Dlab&rut=bfcf24a4914c580db8a85ae9d010d12bcb2cca98c6c5c4226637954256613bff)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fnecat101%2Fsqlite%2Ddeployment%2Dsafety%2Dlab&rut=bfcf24a4914c580db8a85ae9d010d12bcb2cca98c6c5c4226637954256613bff)[github.com/necat101/sqlite-deployment-safety-lab](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fnecat101%2Fsqlite%2Ddeployment%2Dsafety%2Dlab&rut=bfcf24a4914c580db8a85ae9d010d12bcb2cca98c6c5c4226637954256613bff)\n\n[Reproduces **SQLite** **production** **issues** from HN #47637353: **WAL** mode, concurrent writers, overlaLine truncated
|
||||
{"type":"tool_use","timestamp":1788903276927,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_d169e719907349819ec4fbed","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=pytest+benchmark+sqlite+wal+concurrency+acceptance+test+python"},"output":" pytest benchmark sqlite wal concurrency acceptance test python at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [GitHub - joedougherty/sqlite3\\_concurrent\\_writes\\_test\\_suite: Simultating ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)[github.com/joedougherty/sqlite3\\_concurrent\\_writes\\_test\\_suite](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)\n\n[**pytest** is a testing framework that is delightfully easy to get started with. Each of my **tests** will be in the form of a function that lives in test\\_parallel\\_writes.py.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)\n\n## [pytest-benchmark · PyPI](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpypi.org%2Fproject%2Fpytest%2Dbenchmark%2F&rut=49e0ab8ac98a60bb6d218af2c4efac66e303b5840a823aac179f3790d8f20272)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpypi.org%2Fproject%2Fpytest%2Dbenchmark%2F&rut=49e0ab8ac98a60bb6d218af2c4efac66e303b5840a823aac179f3790d8f20272)[pypi.org/project/pytest-benchmark/](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpypi.org%2Fproject%2Fpytest%2Dbenchmark%2F&rut=49e0ab8ac98a60bb6d218af2c4efac66e303b5840a823aac179f3790d8f20272)\n\n[A \\`\\`**pytest**\\`\\` fixture for benchmarking code. It will group the **tests** into rounds that are calibrated to the chosen timer.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpypi.org%2Fproject%2Fpytest%2Dbenchmark%2F&rut=49e0ab8ac98a60bb6d218af2c4efac66e303b5840a823aac179f3790d8f20272)\n\n## [How To Measure And Improve Code Efficiency with Pytest Benchmark (The ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpytest%2Dwith%2Deric.com%2Fpytest%2Dbest%2Dpractices%2Fpytest%2Dbenchmark%2F&rut=c300a7b03495c67cc7fb735ab1688776d9e06acb45947fedb463ce1e2415a5af)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpytest%2Dwith%2Deric.com%2Fpytest%2Dbest%2Dpractices%2Fpytest%2Dbenchmark%2F&rut=c300a7b03495c67cc7fb735ab1688776d9e06acb45947fedb463ce1e2415a5af)[pytest-with-eric.com/pytest-best-practices/pytest-benchmark/](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpytest%2Dwith%2Deric.com%2Fpytest%2Dbest%2Dpractices%2Fpytest%2Dbenchmark%2F&rut=c300a7b03495c67cc7fb735ab1688776d9e06acb45947fedb463ce1e2415a5af)\n\n[A clear understanding of the need to **benchmark** your code especially when writing custom algorithms or complex data transformations. Knowledge and application of **Pytest** **Benchmark** to perform **benchmark** analysis of your code How to analyze **benchmark** results to choose the best algorithm for code snippets.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fpytest%2Dwith%2Deric.com%2Fpytest%2Dbest%2Dpractices%2Fpytest%2Dbenchmark%2F&rut=c300a7b03495c67cc7fb735ab1688776d9e06acb45947fedb463ce1e2415a5af)\n\n## [PCritchfield/pytest-sqlite-poc - GitHub](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2FPCritchfield%2Fpytest%2Dsqlite%2Dpoc&rut=96a9f51f0d9075040f93974e1f636f180a943be1088625182f5451358f91dd0c)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2FPCritchfield%2Fpytest%2Dsqlite%2Dpoc&rut=96a9f51f0d9075040f93974e1f636f180a943be1088625182f5451358f91dd0c)[github.com/PCritchfield/pytest-sqlite-poc](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2FPCritchfield%2Fpytest%2Dsqlite%2DpocLine truncated
|
||||
{"type":"tool_use","timestamp":1788903276960,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_9a1a7101098a4aa3afe7804d","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=sqlite+wal+mode+performance+benchmark+concurrent+readers+single+writer"},"output":" sqlite wal mode performance benchmark concurrent readers single writer at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [Write-Ahead Logging - SQLite](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)[sqlite.org/wal.html](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932) 2026-08-25T00:00:00.0000000\n\n[The bug only affects databases in **WAL** **mode** when there are two or more database connections open on the same file, in separate threads or processes, and when those two connections attempt to write or checkpoint at the same instant. The bug is a data race with tight timing constraints and that requires an unusual usage pattern.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)\n\n## [Connection Pooling Strategies · SQLite Hardening](//duckduckgo.com/l/?uddg=https%3A%2F%2Fproductionhardening.org%2Fwal%2Doptimization%2Dconcurrency%2Dtuning%2Fconnection%2Dpooling%2Dstrategies%2F&rut=28cd525934d47b9d069294878d027363e2bca9c60b061dd58a0c891e22e65d69)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fproductionhardening.org%2Fwal%2Doptimization%2Dconcurrency%2Dtuning%2Fconnection%2Dpooling%2Dstrategies%2F&rut=28cd525934d47b9d069294878d027363e2bca9c60b061dd58a0c891e22e65d69)[productionhardening.org/wal-optimization-concurrency-tuning/connection-pooling-strategies/](//duckduckgo.com/l/?uddg=https%3A%2F%2Fproductionhardening.org%2Fwal%2Doptimization%2Dconcurrency%2Dtuning%2Fconnection%2Dpooling%2Dstrategies%2F&rut=28cd525934d47b9d069294878d027363e2bca9c60b061dd58a0c891e22e65d69)\n\n[Application threads many **concurrent** checkout / return Bounded connection pool fixed maxsize · queue-guarded **Writer** connection **single** · serialized by mutex **Reader** connection 1 **Reader** connection 2 **Reader** connection N **SQLite** **WAL** **mode** BEGIN IMMEDIATE exclusive write lock snapshot read × N A connection also has a lifecycle inside the pool — idle in the queue, checked out and in use, then ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fproductionhardening.org%2Fwal%2Doptimization%2Dconcurrency%2Dtuning%2Fconnection%2Dpooling%2Dstrategies%2F&rut=28cd525934d47b9d069294878d027363e2bca9c60b061dd58a0c891e22e65d69)\n\n## [Optimizing SQLite for Production: WAL Mode, Concurrency, and VFS Layers](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.nitin%2Drachabathuni.com%2Fblog%2Fsqlite%2Dproduction%2Doptimization%2Dwal%2Dmode%2Dconcurrency&rut=d6505e6b25a773f649853e92ec36402b9cbbd89fea5913ba8f881378a3d02ce3)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.nitin%2Drachabathuni.com%2Fblog%2Fsqlite%2Dproduction%2Doptimization%2Dwal%2Dmode%2Dconcurrency&rut=d6505e6b25a773f649853e92ec36402b9cbbd89fea5913ba8f881378a3d02ce3)[www.nitin-rachabathuni.com/blog/sqlite-production-optimization-wal-mode-concurrency](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.nitin%2Drachabathuni.com%2Fblog%2Fsqlite%2Dproduction%2Doptimization%2Dwal%2Dmode%2Dconcurrency&rut=d6505e6b25a773f649853e92ec36402b9cbbd89fea5913ba8f881378a3d02ce3) 2026-07-29T00:00:00.0000000\n\n[Learn how to scale **SQLite** for high-**performance** production environments by optimizing Write-Ahead Logging (**WAL**), concurrency handling, and custom VFS layers.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fwww.nitin%2Drachabathuni.com%2Fblog%2Fsqlite%2Dproduction%2Doptimization%2Dwal%2Dmode%2Dconcurrency&rut=d6505e6b25a773f649853e92ec36402b9cbbd89fea5913ba8fLine truncated
|
||||
{"type":"step_finish","timestamp":1788903276986,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f1c19f001FvRiYNJsO","reason":"tool-calls","snapshot":"a20b5acc12e2b0d2d65126021cd56bc8372ee3cd","messageID":"msg_g001a082f148fe001NFQTZ4js3","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":34977,"input":4738,"output":257,"reasoning":990,"cache":{"write":0,"read":28992}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788903280967,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f1d144001aGc1uUciT","messageID":"msg_g001a082f1c1e4001wr6lXZkeq","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"97e4d9cd338f9dd0595231eec734b299d12bc7cb","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903291058,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f1ed3c001VU65DmPqx","messageID":"msg_g001a082f1c1e4001wr6lXZkeq","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"Strong first batch — official SQLite WAL docs, checkpoint-starvation prior art, and a pytest concurrent-writes test suite repo. Now covering the Python-specific and engineering-blog dimensions.","time":{"start":1788903288124,"end":1788903291054}}}
|
||||
{"type":"tool_use","timestamp":1788903291786,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_0efb0034c340488994f4333f","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=aiosqlite+concurrent+writers+WAL+github+issue"},"output":" aiosqlite concurrent writers WAL github issue at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [Fix: aiosqlite Not Working — Single Writer, WAL Mode, Row Factory, and ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Ffixdevs.com%2Fblog%2Faiosqlite%2Dnot%2Dworking%2F&rut=bf903c864db4fd5d9e0a68bc132890cbb9e7ab676bf547b80ca37c2b6e65c879)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Ffixdevs.com%2Fblog%2Faiosqlite%2Dnot%2Dworking%2F&rut=bf903c864db4fd5d9e0a68bc132890cbb9e7ab676bf547b80ca37c2b6e65c879)[fixdevs.com/blog/aiosqlite-not-working/](//duckduckgo.com/l/?uddg=https%3A%2F%2Ffixdevs.com%2Fblog%2Faiosqlite%2Dnot%2Dworking%2F&rut=bf903c864db4fd5d9e0a68bc132890cbb9e7ab676bf547b80ca37c2b6e65c879) 2026-05-20T00:00:00.0000000\n\n[How to fix Python **aiosqlite** errors — database is locked, **WAL** mode for **concurrent** reads, foreign\\_keys PRAGMA, row factory for dict-like rows, connection per request vs pool, datetime detect\\_types, and FastAPI integration.](//duckduckgo.com/l/?uddg=https%3A%2F%2Ffixdevs.com%2Fblog%2Faiosqlite%2Dnot%2Dworking%2F&rut=bf903c864db4fd5d9e0a68bc132890cbb9e7ab676bf547b80ca37c2b6e65c879)\n\n## [Enabling \\`WAL\\` mode at scale increases failures and timeouts · Issue ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues%2F382&rut=106bdf692059fcca3caf97b66ba7518188e9a9ae18b52e5f5687fd1ec8d293f1)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues%2F382&rut=106bdf692059fcca3caf97b66ba7518188e9a9ae18b52e5f5687fd1ec8d293f1)[github.com/omnilib/aiosqlite/issues/382](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues%2F382&rut=106bdf692059fcca3caf97b66ba7518188e9a9ae18b52e5f5687fd1ec8d293f1) 2026-03-27T00:00:00.0000000\n\n[I'm using Piccolo with SQLite and have run quite a few tests with Bombardier. You can recreate this test with this app and this setup. Findings SQLite writes one at a time and blocks reads: **WAL** mode should help here! However **aiosqlite** fails when the concurrency is high (100 **concurrent** writes). **WAL** mode seems to work fine with less than -c 75 connections **WAL** mode at scale (-c 100) makes success ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues%2F382&rut=106bdf692059fcca3caf97b66ba7518188e9a9ae18b52e5f5687fd1ec8d293f1)\n\n## [Issues · omnilib/aiosqlite · GitHub](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues&rut=d595673d1ba06c82a904aba2f7600fa6b13535915e5574055e516b45db087328)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues&rut=d595673d1ba06c82a904aba2f7600fa6b13535915e5574055e516b45db087328)[github.com/omnilib/aiosqlite/issues](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues&rut=d595673d1ba06c82a904aba2f7600fa6b13535915e5574055e516b45db087328)\n\n[asyncio bridge to the standard sqlite3 module. Contribute to omnilib/**aiosqlite** development by creating an account on **GitHub**.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fomnilib%2Faiosqlite%2Fissues&rut=d595673d1ba06c82a904aba2f7600fa6b13535915e5574055e516b45db087328)\n\n## [python - How to make concurrent writes in SQLite with FastAPI ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F79707043%2Fhow%2Dto%2Dmake%2Dconcurrent%2Dwrites%2Din%2Dsqlite%2Dwith%2Dfastapi%2Dsqlalchemy%2Dwithout%2Ddatab&rut=3f7aa17aa9520870b6c6c24c67a3d10e765bae898c6da1a46acfbb084cbdb7d8)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F79707043%2Fhow%2Dto%2Dmake%2Dconcurrent%2Dwrites%2Din%2Dsqlite%2Dwith%2Dfastapi%2Dsqlalchemy%2Dwithout%2Ddatab&rut=3f7aa17aa952087Line truncated
|
||||
{"type":"tool_use","timestamp":1788903291818,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_3fe35225b25c4c1fb91df278","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=python+sqlite3+documentation+timeout+parameter+check_same_thread+threads"},"output":" python sqlite3 documentation timeout parameter check\\_same\\_thread threads at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [sqlite3 — DB-API 2.0 interface for SQLite databases - Python](//duckduckgo.com/l/?uddg=https%3A%2F%2Fdocs.python.org%2F3%2Flibrary%2Fsqlite3.html&rut=a3abeada0d2a6527efda6964fd867ad61770ded3bee02d9f832b5ddf34a7d129)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fdocs.python.org%2F3%2Flibrary%2Fsqlite3.html&rut=a3abeada0d2a6527efda6964fd867ad61770ded3bee02d9f832b5ddf34a7d129)[docs.python.org/3/library/sqlite3.html](//duckduckgo.com/l/?uddg=https%3A%2F%2Fdocs.python.org%2F3%2Flibrary%2Fsqlite3.html&rut=a3abeada0d2a6527efda6964fd867ad61770ded3bee02d9f832b5ddf34a7d129) 2026-09-08T00:00:00.0000000\n\n[In this tutorial, you will create a database of Monty **Python** movies using basic sqlite3functionality. It assumes a fundamental understanding of database concepts, including cursorsand transactions. First, we need to create a new database and open a database connection to allow sqlite3to work with it. Call **sqlite3**.connect()to create a connection to the database tutorial.dbin the current working ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fdocs.python.org%2F3%2Flibrary%2Fsqlite3.html&rut=a3abeada0d2a6527efda6964fd867ad61770ded3bee02d9f832b5ddf34a7d129)\n\n## [sqlite - Python sqlite3 and concurrency - Stack Overflow](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F393554%2Fpython%2Dsqlite3%2Dand%2Dconcurrency&rut=cb7f39f4b8ce3fa19044d0b400bbdadc4cca8acc12df23e2ec6ad0d43690bc97)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F393554%2Fpython%2Dsqlite3%2Dand%2Dconcurrency&rut=cb7f39f4b8ce3fa19044d0b400bbdadc4cca8acc12df23e2ec6ad0d43690bc97)[stackoverflow.com/questions/393554/python-sqlite3-and-concurrency](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F393554%2Fpython%2Dsqlite3%2Dand%2Dconcurrency&rut=cb7f39f4b8ce3fa19044d0b400bbdadc4cca8acc12df23e2ec6ad0d43690bc97)\n\n[I guess this means that another **thread** has mydatabase.db open through a **sqlite3** connection and has locked it. If I put this line of code in the main program and pass the connection object (conn) to each **thread**, I get a ProgrammingError, saying that SQLite objects created in a **thread** can only be used in that same **thread**.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F393554%2Fpython%2Dsqlite3%2Dand%2Dconcurrency&rut=cb7f39f4b8ce3fa19044d0b400bbdadc4cca8acc12df23e2ec6ad0d43690bc97)\n\n## [sqlite3 — DB-API 2.0 interface for SQLite databases — Python ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgetdocs.org%2FPython%2Fdocs%2F3.7%2Flibrary%2Fsqlite3&rut=4a6fcf3c3b254f50fed479ea4bf0439a1219f88e0f456161ee86d1c825b7a91a)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgetdocs.org%2FPython%2Fdocs%2F3.7%2Flibrary%2Fsqlite3&rut=4a6fcf3c3b254f50fed479ea4bf0439a1219f88e0f456161ee86d1c825b7a91a)[getdocs.org/Python/docs/3.7/library/sqlite3](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgetdocs.org%2FPython%2Fdocs%2F3.7%2Flibrary%2Fsqlite3&rut=4a6fcf3c3b254f50fed479ea4bf0439a1219f88e0f456161ee86d1c825b7a91a)\n\n[By default, the **sqlite3** module uses its Connection class for the connect call. You can, however, subclass the Connection class and make connect () use your class instead by providing your class for the factory **parameter**. Consult the section SQLite and **Python** types of this manual for details.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgetdocs.org%2FPython%2Fdocs%2F3.7%2Flibrary%2Fsqlite3&rut=4a6fcf3c3b254f50fed479ea4bf0439a1219f88e0f456161ee86d1c825b7a91a)\n\n## [12.6. sqlite3 — DB-API 2.0 interface for SQLite databases](//duckduckgo.com/l/?uddg=https%3A%2F%2Fdocumentation.hLine truncated
|
||||
{"type":"tool_use","timestamp":1788903291918,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_a94ffca3604043df9b885806","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=python+multiprocessing+sqlite+WAL+same+database+best+practices"},"output":" python multiprocessing sqlite WAL same database best practices at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [python - SQLite3 and Multiprocessing - Stack Overflow](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F6969820%2Fsqlite3%2Dand%2Dmultiprocessing&rut=921218d71d9b7e3594b59b3640eff5925602fb23c6a31227f787375c6eaa5ab1)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F6969820%2Fsqlite3%2Dand%2Dmultiprocessing&rut=921218d71d9b7e3594b59b3640eff5925602fb23c6a31227f787375c6eaa5ab1)[stackoverflow.com/questions/6969820/sqlite3-and-multiprocessing](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F6969820%2Fsqlite3%2Dand%2Dmultiprocessing&rut=921218d71d9b7e3594b59b3640eff5925602fb23c6a31227f787375c6eaa5ab1)\n\n[I noticed that sqlite3 isn´t really capable nor reliable when i use it inside a **multiprocessing** enviroment. Each process tries to write some data into the **same** **database**, so that a connection is use...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F6969820%2Fsqlite3%2Dand%2Dmultiprocessing&rut=921218d71d9b7e3594b59b3640eff5925602fb23c6a31227f787375c6eaa5ab1)\n\n## [sqlite-best-practices: Configure WAL mode and checkpoint timing for ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskills.rest%2Fskill%2Fsqlite%2Dbest%2Dpractices&rut=428f6f307f15fe30bf375a193672bdea62650dd4baf917a887ea88bc3bfa44be)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskills.rest%2Fskill%2Fsqlite%2Dbest%2Dpractices&rut=428f6f307f15fe30bf375a193672bdea62650dd4baf917a887ea88bc3bfa44be)[skills.rest/skill/sqlite-best-practices](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskills.rest%2Fskill%2Fsqlite%2Dbest%2Dpractices&rut=428f6f307f15fe30bf375a193672bdea62650dd4baf917a887ea88bc3bfa44be)\n\n[Use the **sqlite**\\-**best**\\-**practices** skill to effortlessly configure **wal** mode and checkpoint timing for **sqlite** **multiprocessing** in **python**. A reliable, executable skill for Claude, contributed by randalmurphal, designed for Software Engineering workflows.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fskills.rest%2Fskill%2Fsqlite%2Dbest%2Dpractices&rut=428f6f307f15fe30bf375a193672bdea62650dd4baf917a887ea88bc3bfa44be)\n\n## [concurrency - SQLite Concurrent Access - Stack Overflow](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F4060772%2Fsqlite%2Dconcurrent%2Daccess&rut=42bb9a6a27e35e3f8db91c8187647cac51b198c54f27ca89ec1e05f852353c0e)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F4060772%2Fsqlite%2Dconcurrent%2Daccess&rut=42bb9a6a27e35e3f8db91c8187647cac51b198c54f27ca89ec1e05f852353c0e)[stackoverflow.com/questions/4060772/sqlite-concurrent-access](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F4060772%2Fsqlite%2Dconcurrent%2Daccess&rut=42bb9a6a27e35e3f8db91c8187647cac51b198c54f27ca89ec1e05f852353c0e)\n\n[Does SQLite3 safely handle concurrent access by multiple processes reading/writing from the **same** DB? Are there any platform exceptions to that?](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F4060772%2Fsqlite%2Dconcurrent%2Daccess&rut=42bb9a6a27e35e3f8db91c8187647cac51b198c54f27ca89ec1e05f852353c0e)\n\n## [Simulating concurrent writes to sqlite3 with multiprocessing and pytest](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fgithub.com%2Fjoedougherty%2Fsqlite3_concurrent_writes_test_suite&rut=6060ce1a5a76b88f2f09752b5d717339b0e806de7c8844503f91e1cbcb563a4a)[github.com/joedougherty/sqliLine truncated
|
||||
{"type":"tool_use","timestamp":1788903291928,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_b270e50d6f3d4f99b8612370","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=sqlite+pragma+busy_timeout+synchronous+NORMAL+WAL+documentation"},"output":" sqlite pragma busy\\_timeout synchronous NORMAL WAL documentation at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [Pragma statements supported by SQLite](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fpragma.html&rut=c91f575326108e60352e4177c330c96e4848a20065b7ffadb1a47cebf70fe7fa)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fpragma.html&rut=c91f575326108e60352e4177c330c96e4848a20065b7ffadb1a47cebf70fe7fa)[sqlite.org/pragma.html](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fpragma.html&rut=c91f575326108e60352e4177c330c96e4848a20065b7ffadb1a47cebf70fe7fa) 2026-06-04T00:00:00.0000000\n\n[This **pragma** is an alternative to the sqlite3\\_busy\\_timeout () C-language interface which is made available as a **pragma** for use with language bindings that do not provide direct access to sqlite3\\_busy\\_timeout ().](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fpragma.html&rut=c91f575326108e60352e4177c330c96e4848a20065b7ffadb1a47cebf70fe7fa)\n\n## [Runnable SQLite Docs: PRAGMA Settings | Coddy](//duckduckgo.com/l/?uddg=https%3A%2F%2Fcoddy.tech%2Fdocs%2Fsqlite%2Fpragma%2Dsettings&rut=e77f60895ac51a409e0e2717e5e4a04ae7d8e8498d5814248f910f89524bfdd1)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fcoddy.tech%2Fdocs%2Fsqlite%2Fpragma%2Dsettings&rut=e77f60895ac51a409e0e2717e5e4a04ae7d8e8498d5814248f910f89524bfdd1)[coddy.tech/docs/sqlite/pragma-settings](//duckduckgo.com/l/?uddg=https%3A%2F%2Fcoddy.tech%2Fdocs%2Fsqlite%2Fpragma%2Dsettings&rut=e77f60895ac51a409e0e2717e5e4a04ae7d8e8498d5814248f910f89524bfdd1) 2026-05-02T00:00:00.0000000\n\n[A practical guide to **SQLite** **PRAGMA** settings: journal\\_mode=WAL, synchronous=NORMAL, foreign\\_keys, **busy\\_timeout**, cache\\_size, mmap\\_size, and when to run optimize.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fcoddy.tech%2Fdocs%2Fsqlite%2Fpragma%2Dsettings&rut=e77f60895ac51a409e0e2717e5e4a04ae7d8e8498d5814248f910f89524bfdd1)\n\n## [Write-Ahead Logging - SQLite](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)[sqlite.org/wal.html](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932) 2026-08-25T00:00:00.0000000\n\n[(Writers sync the **WAL** on every transaction commit if **PRAGMA** **synchronous** is set to FULL but omit this sync if **PRAGMA** **synchronous** is set to **NORMAL**.) On the other hand, read performance deteriorates as the **WAL** file grows in size since each reader must check the **WAL** file for the content and the time needed to check the **WAL** file is proportional to ...](//duckduckgo.com/l/?uddg=https%3A%2F%2Fsqlite.org%2Fwal.html&rut=bae257989ce224addb49313bd5584a36eda61b7cdf92a9815dcf32b6aafea932)\n\n## [Pragma statements supported by SQLite](//duckduckgo.com/l/?uddg=http%3A%2F%2Fwww3.sqlite.org%2Fmatrix%2Fpragma.html&rut=6abb3a2c8fa7c355956a25d36e8e7216b6b9919337bf0febbc3a6ee8d0a01c3c)\n\n [](//duckduckgo.com/l/?uddg=http%3A%2F%2Fwww3.sqlite.org%2Fmatrix%2Fpragma.html&rut=6abb3a2c8fa7c355956a25d36e8e7216b6b9919337bf0febbc3a6ee8d0a01c3c)[www3.sqlite.org/matrix/pragma.html](//duckduckgo.com/l/?uddg=http%3A%2F%2Fwww3.sqlite.org%2Fmatrix%2Fpragma.html&rut=6abb3a2c8fa7c355956a25d36e8e7216b6b9919337bf0febbc3a6ee8d0a01c3c)\n\n[\\] This **pragma** is an alternative to the sqlite3\\_busy\\_timeout () C-language interface which is made available as a **pragma** for use with language bindings that do not provide direct access to sqlite3\\_busy\\_timeout (Line truncated
|
||||
{"type":"step_finish","timestamp":1788903291955,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f1fc17001O15taEbkF","reason":"tool-calls","snapshot":"fe9aca8c731d5b24896f29f4c777aedbad468551","messageID":"msg_g001a082f1c1e4001wr6lXZkeq","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":54631,"input":20288,"output":199,"reasoning":416,"cache":{"write":0,"read":33728}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788903357604,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f2fca1001lAtujSilR","messageID":"msg_g001a082f1fc7a001AxYz2h4wT","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"3802667ebb6e7ad6b12685ae4fa68c4695571c21","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903369345,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f321a1001B9HHBbEqO","messageID":"msg_g001a082f1fc7a001AxYz2h4wT","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"Excellent coverage — the aiosqlite#382 issue (WAL fails at high concurrency) and the joedougherty pytest concurrent-writes suite are directly relevant prior art. One final batch: framework-level documentation (Django/SQLAlchemy) which the repo's stack could adopt patterns from.","time":{"start":1788903367073,"end":1788903369341}}}
|
||||
{"type":"tool_use","timestamp":1788903370212,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_d14c5e8a934a469995efa5f0","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=django+documentation+sqlite+concurrency+database+is+locked+timeout"},"output":" django documentation sqlite concurrency database is locked timeout at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n## [SQLite and database is locked error - ORM - Django Forum](//duckduckgo.com/l/?uddg=https%3A%2F%2Fforum.djangoproject.com%2Ft%2Fsqlite%2Dand%2Ddatabase%2Dis%2Dlocked%2Derror%2F26994&rut=e79552cbffe99b2ffaba736053935780d35e26d668589884f0ac7146669facfe)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fforum.djangoproject.com%2Ft%2Fsqlite%2Dand%2Ddatabase%2Dis%2Dlocked%2Derror%2F26994&rut=e79552cbffe99b2ffaba736053935780d35e26d668589884f0ac7146669facfe)[forum.djangoproject.com/t/sqlite-and-database-is-locked-error/26994](//duckduckgo.com/l/?uddg=https%3A%2F%2Fforum.djangoproject.com%2Ft%2Fsqlite%2Dand%2Ddatabase%2Dis%2Dlocked%2Derror%2F26994&rut=e79552cbffe99b2ffaba736053935780d35e26d668589884f0ac7146669facfe)\n\n[It would be to see it as an option, along with a documented why someone would consider enabling it. Without it - it's considerably harder to run **Django** on **SQLite** with more than one process/worker, as there's a chance of hitting an immediate \"**database** **is** **locked**\" regardless of the **timeout** setting.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fforum.djangoproject.com%2Ft%2Fsqlite%2Dand%2Ddatabase%2Dis%2Dlocked%2Derror%2F26994&rut=e79552cbffe99b2ffaba736053935780d35e26d668589884f0ac7146669facfe)\n\n## [python - OperationalError: database is locked - Stack Overflow](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F3172929%2Foperationalerror%2Ddatabase%2Dis%2Dlocked&rut=a2a0c71aeb8117bab2be33f78ce1f4ce2c7818db3817dad5530bfee62bf6d7e8)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F3172929%2Foperationalerror%2Ddatabase%2Dis%2Dlocked&rut=a2a0c71aeb8117bab2be33f78ce1f4ce2c7818db3817dad5530bfee62bf6d7e8)[stackoverflow.com/questions/3172929/operationalerror-database-is-locked](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F3172929%2Foperationalerror%2Ddatabase%2Dis%2Dlocked&rut=a2a0c71aeb8117bab2be33f78ce1f4ce2c7818db3817dad5530bfee62bf6d7e8)\n\n[From **Django's** **documentation**: **SQLite** **is** meant to be a lightweight **database**, and thus can't support a high level of **concurrency**. OperationalError: **database** **is** **locked** errors indicate that your application is experiencing more **concurrency** than **sqlite** can handle in default configuration.](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F3172929%2Foperationalerror%2Ddatabase%2Dis%2Dlocked&rut=a2a0c71aeb8117bab2be33f78ce1f4ce2c7818db3817dad5530bfee62bf6d7e8)\n\n## [Django + Sqlite: database is locked - Stack Overflow](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F28958580%2Fdjango%2Dsqlite%2Ddatabase%2Dis%2Dlocked&rut=78e6043fdd62daf24cfac7ded24f1672597a47a066d03754fa5c35654bb1c765)\n\n [](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F28958580%2Fdjango%2Dsqlite%2Ddatabase%2Dis%2Dlocked&rut=78e6043fdd62daf24cfac7ded24f1672597a47a066d03754fa5c35654bb1c765)[stackoverflow.com/questions/28958580/django-sqlite-database-is-locked](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F28958580%2Fdjango%2Dsqlite%2Ddatabase%2Dis%2Dlocked&rut=78e6043fdd62daf24cfac7ded24f1672597a47a066d03754fa5c35654bb1c765)\n\n[Rewriting your code to reduce **concurrency** and ensure that **database** transactions are short-lived. Increase the default **timeout** value by setting the **timeout** **database** option](//duckduckgo.com/l/?uddg=https%3A%2F%2Fstackoverflow.com%2Fquestions%2F28958580%2Fdjango%2Dsqlite%2Ddatabase%2Dis%2Dlocked&rut=78e6043fdd62daf24cfac7ded24f1672597a47a066d03754fa5c35654bb1c765)\n\n## [Django, SQLite, and Line truncated
|
||||
{"type":"tool_use","timestamp":1788903370240,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"type":"tool","tool":"webfetch","callID":"call_907cbdd92b3a4006931cb5c8","state":{"status":"completed","input":{"format":"markdown","url":"https://duckduckgo.com/html/?q=sqlalchemy+sqlite+pysqlite+documentation+concurrency+transactions+%22BEGIN+IMMEDIATE%22"},"output":" sqlalchemy sqlite pysqlite documentation concurrency transactions \"BEGIN IMMEDIATE\" at DuckDuckGo \n\n[](/html/ \"DuckDuckGo\")\n\n \n\nAll Regions Argentina Australia Austria Belgium (fr) Belgium (nl) Brazil Bulgaria Canada (en) Canada (fr) Catalonia Chile China Colombia Croatia Czech Republic Denmark Estonia Finland France Germany Greece Hong Kong Hungary Iceland India (en) Indonesia (en) Ireland Israel (en) Italy Japan Korea Latvia Lithuania Malaysia (en) Mexico Netherlands New Zealand Norway Pakistan (en) Peru Philippines (en) Poland Portugal Romania Russia Saudi Arabia Singapore Slovakia Slovenia South Africa Spain (ca) Spain (es) Sweden Switzerland (de) Switzerland (fr) Taiwan Thailand (en) Turkey US (English) US (Spanish) Ukraine United Kingdom Vietnam (en)\n\nAny Time Past Day Past Week Past Month Past Year\n\n# No results found for **sqlalchemy sqlite pysqlite documentation concurrency transactions \"BEGIN IMMEDIATE\"**\n\n**Suggestions**:\n\n- Check spelling\n- Try related keywords\n- Remove unnecessary punctuation\n\n[Feedback](//duckduckgo.com/feedback.html)\n\n","metadata":{"truncated":false},"title":"https://duckduckgo.com/html/?q=sqlalchemy+sqlite+pysqlite+documentation+concurrency+transactions+%22BEGIN+IMMEDIATE%22 (text/html; charset=UTF-8)","time":{"start":1788903369345,"end":1788903370238}},"id":"prt_g001a082f32a52001EVQ3CUwMr","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","messageID":"msg_g001a082f1fc7a001AxYz2h4wT"}}
|
||||
{"type":"step_finish","timestamp":1788903370268,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f32dff001qmsW59uIp","reason":"tool-calls","snapshot":"09103e585487a0cb279e213cd28e1497c9f1e799","messageID":"msg_g001a082f1fc7a001AxYz2h4wT","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":72768,"input":43,"output":152,"reasoning":445,"cache":{"write":0,"read":72128}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788903393712,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f389af001GV2V17EB3","messageID":"msg_g001a082f32e3f0017vFJk9uAG","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","snapshot":"fe63c20c156ce39c414b3027034aa4c81ded091c","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788903620133,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f43494001IEnMQSnKp","messageID":"msg_g001a082f32e3f0017vFJk9uAG","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"text","text":"Discovery is complete — 10 search queries executed, ~25 distinct URLs found across official docs, GitHub issues/repos, Q&A, and engineering blogs. Composing the stage artifact.\n\n---\n\n# OUTWARD_DISCOVERY Artifact — Issue 262, Round 1\n\n**Contract**: Acceptance test for SQLite WAL performance in concurrent Python applications (repo-specific; rune's memory subsystem: `memory_store.py`, `warm_router.py`, `curator.py`, `auto_tasks.py`, `task_gate.py` — many short-lived `sqlite3.connect` calls, mixed `mode=ro`/RW connections across multiple processes, WAL enabled in `task_gate.py`, FTS5 + sqlite-vec).\n\n## 1. Search strategies\n\n| ID | Strategy | Queries | Targets |\n|----|----------|---------|---------|\n| S1 | Official WAL semantics | `sqlite wal mode performance benchmark concurrent readers single writer`; `sqlite pragma busy_timeout synchronous NORMAL WAL documentation` | sqlite.org docs; grounding for test assertions |\n| S2 | Python binding behavior | `python sqlite3 documentation timeout parameter check_same_thread threads`; `python multiprocessing sqlite WAL same database best practices` | stdlib docs, threads-vs-processes semantics |\n| S3 | Acceptance/perf test prior art | `pytest benchmark sqlite wal concurrency acceptance test python`; `aiosqlite concurrent writers WAL github issue` | test suites, benchmark tooling, known failure thresholds |\n| S4 | Failure modes | `sqlite wal checkpoint starvation stall production issues`; `sqlite WAL concurrency \"database is locked\" busy_timeout` | reproducible failure scenarios to assert against |\n| S5 | Framework precedent | `django documentation sqlite concurrency database is locked timeout`; `sqlalchemy pysqlite BEGIN IMMEDIATE` (no-hit → known-stable URL used) | documented defaults worth mirroring in the acceptance test |\n\n## 2. Discovered sources (classified)\n\n### official_docs (highest read priority)\n- **S1** https://sqlite.org/wal.html — WAL semantics: readers/writers concurrency, checkpointing, synchronous=NORMAL trade-offs, known multi-connection race bug. *Ground truth for what the acceptance test may assert.*\n- **S2** https://sqlite.org/pragma.html — `busy_timeout`, `journal_mode`, `synchronous` definitions (Python's `timeout` param maps to busy_timeout).\n- **S3** https://sqlite.org/c3ref/wal_checkpoint_v2.html — PASSIVE/FULL/RESTART/TRUNCATE checkpoint modes; blocking semantics.\n- **S4** https://docs.python.org/3/library/sqlite3.html — `timeout` param, `check_same_thread`, transaction control.\n- **S5** https://docs.sqlalchemy.org/en/20/dialects/sqlite.html — *(identified as known-stable official URL; query returned no hit)* — pysqlite serializable isolation / BEGIN IMMEDIATE / WAL guidance.\n\n### github_issue / github_repo (direct prior art)\n- **S6** https://github.com/omnilib/aiosqlite/issues/382 — \"Enabling WAL at scale increases failures and timeouts\": WAL fine below ~75 concurrent conns, degrades at 100. **Quantified failure threshold — key prior art for acceptance thresholds.**\n- **S7** https://github.com/joedougherty/sqlite3_concurrent_writes_test_suite — pytest + multiprocessing suite measuring max concurrent 1-record inserts before `database is locked`. **Closest structural template for the repo's acceptance test.**\n- **S8** https://github.com/anze3db/django-sqlite-dblock — repro repo: configure SQLite for multi-worker concurrency (Django context).\n- **S9** https://github.com/necat101/sqlite-deployment-safety-lab — reproduces WAL production issues: concurrent writers, checkpoint starvation, backup safety.\n\n### engineering_blog / deep-dive\n- **S10** https://productionhardening.org/wal-optimization-concurrency-tuning/ (+ subpages: PRAGMA guide, connection-pooling strategies) — claims checkpoint starvation is the most common production WAL failure; per-connection PRAGMA reset pitfall (relevant: repo opens a fresh connection per call).\n- **S11** https://dev.to/lumin-playstar/sqlite-wal-mode-10x-performance-for-python-apps-4ic — Python WAL performance claims (\"10x\"); treat as unverified marketing-grade claim to check against S1/S6.\n- **S12** https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo — minimal repro: one stale read transaction starves checkpoints.\n- **S13** https://blog.pecar.me/django-sqlite-dblock/ — Django SQLite lock analysis (transferable diagnosis method).\n\n### q_and_a (community consensus, medium priority)\n- **S14** https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency — threads + sqlite3 connection sharing (`check_same_thread`).\n- **S15** https://stackoverflow.com/questions/6969820/sqlite3-and-multiprocessing — multiprocessing reliability Line truncated
|
||||
{"type":"step_finish","timestamp":1788903620176,"sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","part":{"id":"prt_g001a082f6fe24001ox29z81i8","reason":"stop","snapshot":"010875169a46e0441bcbb8ce507c8e62598c6831","messageID":"msg_g001a082f32e3f0017vFJk9uAG","sessionID":"ses_-ffe5f7d1024a3ffe5J13LEwLr","type":"step-finish","tokens":{"total":83451,"input":81460,"output":1991,"reasoning":0,"cache":{"write":0,"read":0}},"cost":0}}
|
||||
@@ -0,0 +1,42 @@
|
||||
{"type":"step_start","timestamp":1788905053677,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830cddea0011Q08mPxw6","messageID":"msg_g001a0830cb84c001t0NQKcjWr","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"5e8a5f6e63f1d501a023eb0685f3598f9e43bc6e","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905055386,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830cded2001Xfepq6kOf","messageID":"msg_g001a0830cb84c001t0NQKcjWr","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"text","text":"I'll start by searching for a matching skill, then locate the prior stage artifacts (especially the OUTWARD_DISCOVERY source list I need to read).","time":{"start":1788905053906,"end":1788905055383}}}
|
||||
{"type":"tool_use","timestamp":1788905055389,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"skill_search","callID":"call_913140b299664e50ab3c46c9","state":{"status":"completed","input":{"query":"Read primary external sources (web pages, docs) selected by a prior discovery stage and extract claims with source IDs and limitations for a research pipeline stage about sqlite WAL performance in concurrent Python apps; output structured stage artifact outward_reading.json"},"output":"{\n \"status\": \"matched\",\n \"results\": [\n {\n \"skill_id\": \"xlsx-official\",\n \"name\": \"xlsx-official\",\n \"score\": 0.6403,\n \"reason\": \"The skill description matches these query terms: read, source, page, doc, pipeline, in, python, artifact.\"\n },\n {\n \"skill_id\": \"firecrawl-agent\",\n \"name\": \"firecrawl-agent\",\n \"score\": 0.5299,\n \"reason\": \"The skill description matches these query terms: page, extract, structured, json.\"\n },\n {\n \"skill_id\": \"firecrawl-search\",\n \"name\": \"firecrawl-search\",\n \"score\": 0.5431,\n \"reason\": \"The skill description matches these query terms: source, web, page, research, about, in.\"\n }\n ],\n \"loaded_skill_id\": null\n}","metadata":{"status":"matched","loadedSkillID":null,"truncated":false},"title":"Found 3 skills","time":{"start":1788905055384,"end":1788905055388}},"id":"prt_g001a0830cded8001LncAzTVam","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830cb84c001t0NQKcjWr"}}
|
||||
{"type":"tool_use","timestamp":1788905055475,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"memory","callID":"call_3847cfc8d4cd45b49e28541a","state":{"status":"completed","input":{"operation":"search","query":"OUTWARD_DISCOVERY sqlite WAL issue 262"},"output":"Found 9 matches (BM25-ranked, best first).\nA hit here is authoritative — use it even if a parallel/sibling query returned nothing.\nIf you need the FULL body (snippets are truncated), Read the path.\nIf you need an EXACT literal (a connection string, port, token, full command line, path) and the snippet/body only paraphrases or partially shows it, the curated memory may have dropped the precise form — query the history tool for the original message, which holds it verbatim.\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr/checkpoint.md\nScope: sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr, Type: checkpoint, Score: 27.168\n...<<OUTWARD_DISCOVERY>> stage for <<issue>> <<262>> (research-<<262>>-r1, <<SQLite>> <<WAL>> performance in concurrent Python apps) — repo grounding + 4 discovery searches done, URL inventory captured, <<outward_discovery>>.json artifact pending\n\n# Session checkpoint...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d08ef0effe7822prgaw/checkpoint.md\nScope: sessions/ses_-ffe5f7d08ef0effe7822prgaw, Type: checkpoint, Score: 25.188\n...OUTWARD_READING for research-<<262>>-r1 (<<issue>> <<262>>: <<SQLite>> <<WAL>> performance under concurrency in Python apps; acceptance-test question). Progress so far:\n\n1. Recovered the <<OUTWARD_DISCOVERY>> source inventory from prior session...\n\n### /home/nick/.local/share/mimocode/memory/projects/add96ab3-25dd-4c38-9fa3-34c01811d081/MEMORY.md\nScope: projects/add96ab3-25dd-4c38-9fa3-34c01811d081, Type: memory, Score: 15.181\n...and `file:...?mode=ro` URI reads) across multiple OS processes; only task_gate.py sets `PRAGMA journal_mode=<<WAL>>` explicitly; <<sqlite>>-vec extension must be loaded per connection (<<issue>> #26 defect fix).\n\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5fc20c77acffeZPFtNS5gw/tasks/T4.7/progress.md\nScope: sessions/ses_-ffe5fc20c77acffeZPFtNS5gw, Type: progress, Score: 9.724\n...Added per-canonical-database-path <<WAL>> activation locks, deadline-bounded retry with exponential backoff for <<SQLite>> `BUSY`/`LOCKED` only, requested busy-timeout restoration, and cleanup of partially initialized connections on failure.\n- tests...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5fc20c77acffeZPFtNS5gw/checkpoint-task-history.md\nScope: sessions/ses_-ffe5fc20c77acffeZPFtNS5gw, Type: checkpoint, Score: 8.725\n...concurrency and migration re-review\n- 🟡 T25 Reconcile Gitea hardening conflicts with master\n- ✅ T26 Final read-only review of <<SQLite>> runtime fixes\n- ✅ T27 Fix concurrent fresh-path <<WAL>> activation with strict TDD\n\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5fc20c77acffeZPFtNS5gw/tasks/T4.6/progress.md\nScope: sessions/ses_-ffe5fc20c77acffeZPFtNS5gw, Type: progress, Score: 8.351\n...Fixed conversation-store paging and <<SQLite>> initialization, migration, and channel-creation concurrency.\n\n## §2 Subagent intent\nThis subagent was asked to address four code-quality findings in the Rune conversation store using strict...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f826d4b3affeptScH2iSt/notes.md\nScope: sessions/ses_-ffe5f826d4b3affeptScH2iSt, Type: free, Score: 8.180\n...Contract compiled from Gitea <<issue>> body.\n- INWARD: 0.03s, no MiMo. Context builder matches keywords → umbrella manifest → source files.\n- Both persisted to Gitea master via contents API.\n- Tree on master: stage=<<OUTWARD>>...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d7bf30effejatPfIVut/checkpoint.md\nScope: sessions/ses_-ffe5f7d7bf30effejatPfIVut, Type: checkpoint, Score: 6.797\n...an 8-stage research pipeline exists — DEFINE → INWARD → <<OUTWARD_DISCOVERY>> → OUTWARD_READING → ADVERSARIAL → INNOVATION → SYNTHESIS (stage-scoped methodology, from prior session `ses_-ffe5f826d4b3affeptScH2iSt`). Convention: research filed as `research/<<issue>>-<n>-research.md...\n\n### /home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f826d4b3affeptScH2iSt/checkpoint.md\nScope: sessions/ses_-ffe5f826d4b3affeptScH2iSt, Type: checkpoint, Score: 5.621\n...when a gate aborts, the DIAGNOSTIC must be visible (stdout, not stderr).\n- **DISPATCH EVENTS CARRY NO <<ISSUE>> PAYLOAD:** `gitea.event.<<issue>>.*` is null on workflow_dispatch. Fix: fetch <<issue>> title/body from...\n","metadata":{"count":9,"truncated":false},"title":"Memory search: 9 results","time":{"start":1788905055386,"end":1788905055472}},"id":"prt_g001a0830ce294001Df7MAdPHc","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830cb84c001t0NQKcjWr"}}
|
||||
{"type":"step_finish","timestamp":1788905055552,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830ce4f2001HnpjNGPbp","reason":"tool-calls","snapshot":"d8594ae82cb03f83b35781e8ceae266c5d9dc6b8","messageID":"msg_g001a0830cb84c001t0NQKcjWr","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":29273,"input":29052,"output":221,"reasoning":0,"cache":{"write":0,"read":0}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905065148,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d0aba001ZzfnKeBTm","messageID":"msg_g001a0830ce5ab001xV6b6zH7e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"0bccb8ce97d091061ff937d5400a7388b464670a","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905066437,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d0b71002bRmvZXZn3","messageID":"msg_g001a0830ce5ab001xV6b6zH7e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"text","text":"No exact skill match — this is a stage in a custom research pipeline, so I'll proceed directly. Memory shows a prior session completed OUTWARD_DISCOVERY for this issue; let me recover its source inventory.","time":{"start":1788905065329,"end":1788905066435}}}
|
||||
{"type":"tool_use","timestamp":1788905066444,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"read","callID":"call_d405d8010069479295405f48","state":{"status":"completed","input":{"file_path":"/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr/checkpoint.md"},"output":"<path>/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr/checkpoint.md</path>\n<type>file</type>\n<content>\n1: Topic: OUTWARD_DISCOVERY stage for issue 262 (research-262-r1, SQLite WAL performance in concurrent Python apps) — repo grounding + 4 discovery searches done, URL inventory captured, outward_discovery.json artifact pending\n2: \n3: # Session checkpoint\n4: _Generated by checkpoint writer; structure preserved across updates. Edit only content under italic instructions._\n5: \n6: ## §1 Active intent\n7: _User's most recent explicit request, verbatim block-quoted from the conversation. The verbatim quote is the ground truth for what to do — do not paraphrase._\n8: \n9: > \"## Your task\n10: > Generate search strategies and discover prior art for this issue.\"\n11: \n12: (Verbatim task section of the headless stage dispatch. Full context: process `research-262-r1` — issue 262, round 1, stage OUTWARD_DISCOVERY of 8; title \"OUTWARD_DISCOVERY acceptance: sqlite WAL performance in concurrent Python applications\" (question_type: repo-specific). MUST: produce search queries, discover URLs, classify source types. MUST NOT: read full sources yet (that is OUTWARD_READING). Output: stage artifact as structured text, expected artifact `outward_discovery.json`, ending with `StageCompleted: OUTWARD_DISCOVERY` (or `StageFailed:` + `Reason:`). Accepted prior artifacts: DEFINE contract + INWARD claims I1–I5 (files: rune_tui.py, warm_router.py, curator.py, auto_tasks.py, memory_store.py). blocking_unknowns: none.)\n13: \n14: ## §2 Next concrete action\n15: _The single next concrete step, derived from §1 and current state. Include verbatim quote when the user gave one._\n16: \n17: Run the remaining discovery searches (Python-specific sqlite3 concurrency: aiosqlite / check_same_thread / connection-per-call patterns; official SQLite locking + pragma docs: lockingmodel.html, pragma.html busy_timeout; production case studies: Fly.io/LiteFS, Litestream, Turso), then compose the stage artifact — query→sub-question strategy map, discovered-URL inventory with source_type classification, OUTWARD_READING priorities — as structured text for `outward_discovery.json`.\n18: > \"Produce your stage artifact as structured text. End with:\n19: > ```\n20: > StageCompleted: OUTWARD_DISCOVERY\n21: > ```\"\n22: \n23: ## §3 Directives (this session)\n24: _This session's specific working style. Project-level rules are in projects/<pid>/MEMORY.md — do not duplicate them here. Only put items that are session-specific._\n25: \n26: - Stage-boundary rule from capsule: `allowed_action_now = OUTWARD_DISCOVERY` — discovery via search-result titles/snippets ONLY; do NOT fetch/read full external sources this stage (that is the next stage, OUTWARD_READING).\n27: - Discovery method this session: webfetch against `https://duckduckgo.com/html/?q=<url-encoded terms>` (verified working; batch ≥4 queries in parallel). skill_search ran at turn 1 per first-query trigger: no exact match (nearest: firecrawl-search 0.61) → proceed without a skill.\n28: - Derive each query from repo-grep evidence first — question_type is repo-specific, so queries must match the real concurrency shape (multi-process, per-call connections, ro/RW mix, sqlite-vec per-connection load).\n29: \n30: ## §4 Task tree\n31: _Hierarchical view of tasks with current focus marked. Pulled from task tool's DB; one bullet per top-level task with status + summary. Append ` (progress: tasks/<id>/progress.md)` so the next agent can Read the per-task journal directly. Indent sub-tasks two spaces under their parent._\n32: \n33: (none — task tool DB returned \"No tasks\" at checkpoint time; stage work is not tracked as tasks this session)\n34: \n35: ## §5 Current work\n36: _Description of what was being done immediately before this checkpoint. Mention specific file paths and code locations._\n37: \n38: Executing OUTWARD_DISCOVERY for research-262-r1 (issue 262: SQLite WAL performance under concurrency in Python apps, acceptance-test question). Done so far: (a) repo grounding — grep for `sqlite|WAL|journal_mode|busy_timeout|PRAGMA` over src/rune (135 hits; details in §6) + `git log` (research-executor tree, HEAD 83ea89c). (b) 4 parallel DuckDuckGo SERP fetches, all successful. Discovered-URL inventory (titles/snippets only — NOT yet read, per stage contract):\n39: \n40: OFFICIAL DOCS (sqlite.org) — TOP reading priority:\n41: - https://sqlite.org/wal.html — Write-Ahead Logging; §2.2 concurrency (reader \"end mark\"); snippet also discloses a WAL data-race bug (≥2 connections in separate threads/processes writing/cLine truncated
|
||||
{"type":"tool_use","timestamp":1788905066447,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"read","callID":"call_c8234dc4b1a14a67aa9b64c0","state":{"status":"completed","input":{"file_path":"/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d08ef0effe7822prgaw/checkpoint.md"},"output":"<path>/home/nick/.local/share/mimocode/memory/sessions/ses_-ffe5f7d08ef0effe7822prgaw/checkpoint.md</path>\n<type>file</type>\n<content>\n1: # Session checkpoint\n2: _Generated by checkpoint writer; structure preserved across updates. Edit only content under italic instructions._\n3: \n4: > \"# Research Stage: OUTWARD_READING ... ## Your task: Read the selected sources from OUTWARD_DISCOVERY. Extract claims and provenance. ## You MUST read primary sources, extract claims with source IDs, note limitations. ## You MUST NOT do NOT generate new search queries (that is OUTWARD_DISCOVERY).\"\n5: \n6: (Paraphrased: headless stage dispatch for process research-262-r1, issue 262, round 1, stage OUTWARD_READING of 8; completed stages DEFINE/INWARD/OUTWARD_DISCOVERY; allowed_action_now=OUTWARD_READING; expected artifact `outward_reading.json`; output must end with `StageCompleted: OUTWARD_READING` (or `StageFailed:` + `Reason:`). INWARD claims I1–I5 name files rune_tui.py, warm_router.py, curator.py, auto_tasks.py, memory_store.py. Full process capsule JSON was in the dispatch; stage prompt template confirmed at /mnt/workdrive/research-stage/prompts/research-stages/outward_reading.md.)\n7: \n8: ## §2 Next concrete action\n9: _The single next concrete step, derived from §1 and current state. Include verbatim quote when the user gave one._\n10: \n11: Continue OUTWARD_READING: fetch the remaining priority sources from the discovery inventory (batch in parallel), then compose the stage artifact as structured text (claims with source IDs + limitations), ending with the literal line `StageCompleted: OUTWARD_READING`.\n12: \n13: Remaining sources to read (from prior-session inventory, ses_-ffe5f7d1024a3ffe5J13LEwLr):\n14: - https://github.com/necat101/sqlite-deployment-safety-lab (HN #47637353 repro lab)\n15: - https://github.com/mouadja02/skills/blob/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md\n16: - https://productionhardening.org/wal-optimization-concurrency-tuning/ (+ /connection-pooling-strategies/) — verify site credibility\n17: - https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo\n18: - https://dev.to/lumin-playstar/sqlite-wal-mode-10x-performance-for-python-apps-4ic — verify \"10x\" numbers\n19: - https://www.sqliteforum.com/p/checkpoint-algorithms-and-wal-performance\n20: - https://pypi.org/project/pytest-benchmark/ + https://pytest-benchmark.readthedocs.io/en/latest/ + https://bencher.dev/learn/benchmarking/python/pytest-benchmark/\n21: - https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency\n22: - Optional/secondary: sqlite.org lockingmodel/pragma docs; theconsensus.dev WAL-reset reproducer post; charlesleifer.com \"going fast with sqlite and python\"; begin-concurrent branch doc.\n23: \n24: Already read this session (do not re-fetch): sqlite.org/wal.html; sqlite.org/c3ref/wal_checkpoint_v2.html; github.com/joedougherty/sqlite3_concurrent_writes_test_suite (README). Extracted claims recorded in §5/§7.\n25: \n26: ## §3 Directives (this session)\n27: _This session's specific working style. Project-level rules are in projects/<pid>/MEMORY.md — do not duplicate them here. Only put items that are session-specific._\n28: \n29: - Stage contract: OUTWARD_READING only — read primary sources, extract claims with source IDs, note limitations. Do NOT generate new search queries (that is OUTWARD_DISCOVERY).\n30: - Discovery tooling note: GitHub repo pages fetch fine via plain webfetch but return large navigation chrome — content is at the bottom; a raw README fetch (raw.githubusercontent.com) is cleaner for code-heavy repos.\n31: \n32: ## §4 Task tree\n33: _Hierarchical view of tasks with current focus marked. Pulled from task tool's DB; one bullet per top-level task with status + summary. Append ` (progress: tasks/<id>/progress.md)` so the next agent can Read the per-task journal directly. Indent sub-tasks two spaces under their parent._\n34: \n35: (none — task tool DB returned \"No tasks\" at checkpoint time; stage work is not tracked as tasks this session)\n36: \n37: ## §5 Current work\n38: _Description of what was being done immediately before this checkpoint. Mention specific file paths and code locations._\n39: \n40: Executing OUTWARD_READING for research-262-r1 (issue 262: SQLite WAL performance under concurrency in Python apps; acceptance-test question). Progress so far:\n41: \n42: 1. Recovered the OUTWARD_DISCOVERY source inventory from prior session checkpoint (memory/sessions/ses_-ffe5f7d1024a3ffe5J13LEwLr/checkpoint.md §5) — the dispatch capsule truncated it. Also Line truncated
|
||||
{"type":"step_finish","timestamp":1788905066677,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d0fce00167BDs5Jjq","reason":"tool-calls","snapshot":"0384f80ee541ab290f75d1acb0665f018ad864ee","messageID":"msg_g001a0830ce5ab001xV6b6zH7e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":30919,"input":1633,"output":230,"reasoning":0,"cache":{"write":0,"read":29056}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905073561,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d2b98001Fcw1Q4pcv","messageID":"msg_g001a0830d11a4001ebTTYjiIn","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"234d9c5ccceecef36edaf9a804c0060267fc3897","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905075522,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d2b99001mynl7aF5l","messageID":"msg_g001a0830d11a4001ebTTYjiIn","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"text","text":"I've recovered the full state. Prior sessions already read S1–S3; my job now is to read the remaining priority sources and compose the stage artifact. Fetching the next batch in parallel:","time":{"start":1788905073561,"end":1788905075520}}}
|
||||
{"type":"tool_use","timestamp":1788905075720,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_a37a59f02eaa479a8931e1b8","state":{"status":"completed","input":{"format":"text","url":"https://www.sqliteforum.com/p/checkpoint-algorithms-and-wal-performance"},"output":"SQLite WAL Checkpoint Algorithms Explained\n \n \n \n \n \n\n \n\n \n \n \n \n \n \n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n \n \n \n \n \n \n \n \n \n \n\n \n\n \n\n \n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n\n \n \n \n\n \n \n \n \n\n \n \n\n \n\n \n\n \n SQLite ForumSubscribeSign inCheckpoint Algorithms and WAL Performance TuningUnderstanding Checkpoint Modes, WAL Growth, and Write Throughput in SQLiteJenny MuralidharanMay 12, 20262ShareIn our previous guide on SQLite WAL internals, we explored how SQLite stores changes inside the WAL file using frames and commit records.But WAL mode introduces a new challenge:What happens when the WAL file keeps growing?That’s where checkpointing becomes critical. Checkpointing is one of the most important mechanisms in SQLite WAL mode because it directly affects:Write throughputRead performanceDisk usageDatabase responsivenessPoor checkpoint configuration can lead to:Large WAL filesSlower writesIncreased I/O pressureUnexpected latency spikesIn this guide, we’ll break down:How checkpointing works internallyThe different checkpoint algorithmsHow checkpoints impact performancePractical WAL tuning strategies for production systemsWhat is a WAL Checkpoint?In WAL mode:Writes are appended to the -wal fileThe main database file remains unchanged initiallyEventually, SQLite needs to merge WAL changes back into the main database.This process is called a checkpoint.What Happens During a CheckpointSQLite:Reads committed frames from the WAL fileCopies those pages into the main database fileUpdates the database stateOptionally truncates or resets the WALWithout checkpointing:WAL files would grow indefinitelyCheckpointing vs CommittingThis is a common point of confusion.CommitA commit:Marks a transaction as complete inside the WAL fileMakes changes visible to readersCheckpointA checkpoint:Moves committed changes from WAL into the database file👉 Commits affect transaction visibility.👉 Checkpoints affect storage consolidation.How SQLite Decides When to CheckpointSQLite supports:Automatic checkpointsManual checkpointsAutomatic CheckpointingBy default:PRAGMA wal_autocheckpoint = 1000;This means: SQLite triggers a checkpoint after roughly 1000 WAL pages accumulate The actual size depends on:Database page size Workload patternsCheckpoint Algorithms in SQLiteSQLite provides four primary checkpoint modes:PASSIVE FULL RESTART TRUNCATE Each behaves differently internally.PASSIVE CheckpointPRAGMA wal_checkpoint(PASSIVE);BehaviorCopies as many WAL frames as possibleDoes not block readersStops if active readers prevent progressAdvantagesMinimal disruptionGood for busy systems DisadvantagesWAL may not fully shrink Incomplete checkpoints are common under heavy read load Best Use CaseApplications prioritizing responsiveness over aggressive cleanup.FULL CheckpointPRAGMA wal_checkpoint(FULL);BehaviorWaits for readers if necessary Ensures all possible frames are checkpointedAdvantagesMore complete WAL consolidation Better WAL size controlDisadvantagesCan temporarily delay operations Increased latency during checkpoint executionBest Use CaseModerate workloads requiring balanced WAL maintenance.RESTART CheckpointPRAGMA wal_checkpoint(RESTART);BehaviorPerforms a FULL checkpoint Resets WAL so new writes begin from the start Important DetailThe WAL file itself may remain allocated on disk.AdvantagesEfficient WAL reuse Reduces file fragmentationBest Use CaseLong-running applications with steady write activity.TRUNCATE CheckpointPRAGMA wal_checkpoint(TRUNCATE);BehaviorFully checkpoints WAL contents Truncates WAL file to zero bytesAdvantagesMaximum WAL cleanup Frees disk space immediatelyDisadvantagesMore expensive operation Can increase I/O overheadBest Use CaseMainLine truncated
|
||||
{"type":"tool_use","timestamp":1788905075785,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_4e947775b1a44b2fa8e8ef67","state":{"status":"completed","input":{"format":"text","url":"https://raw.githubusercontent.com/mouadja02/skills/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md"},"output":"---\nname: sqlite-wal-checkpoint-starvation-diagnostics\ndescription: \"Use when a SQLite database in WAL mode has a growing -wal file, repeated incomplete checkpoints, SQLITE_BUSY, disk-pressure risk, or reader slowdowns that may indicate checkpoint starvation.\"\nversion: \"1.0.0\"\nlicense: MIT\n---\n\n# SQLite WAL Checkpoint Starvation Diagnostics\n\nDiagnose a WAL that cannot reset without deleting journal files or turning a production incident into a write outage. Separate **copying frames into the database** from **resetting/truncating the WAL**: a checkpoint can make progress while an older reader still prevents reset.\n\n## When to Use\n\n- A `database-wal` file grows continuously or threatens disk capacity.\n- `PRAGMA wal_checkpoint(...)` repeatedly leaves frames uncheckpointed or reports busy.\n- Read latency worsens while WAL size and long-lived read transactions increase.\n- Space returns only after all application processes or readers exit.\n- An operator needs a bounded, evidence-first checkpoint recovery sequence.\n\n## When Not to Use\n\n- Ordinary query/index tuning with no WAL growth or checkpoint symptom.\n- Rollback-journal databases (`journal_mode` is not `wal`).\n- Corruption recovery, file carving, or restoring a damaged database.\n- Network filesystems: SQLite WAL requires cooperating processes on one host; redesign placement rather than applying this runbook.\n\n## Prerequisites\n\n- A verified backup or application recovery point before any production mutation.\n- Filesystem access for size and free-space measurements.\n- A SQLite client compatible with the target database.\n- Application observability that can identify connection owners and transaction age. SQLite itself does not provide a universal cross-process reader list.\n- Authority to pause traffic only if read-only diagnosis proves escalation necessary.\n\n## Quick Reference\n\n```sql\nPRAGMA journal_mode; -- inspect; do not change during diagnosis\nPRAGMA wal_autocheckpoint; -- configured frame threshold\nPRAGMA busy_timeout; -- current connection only\nPRAGMA wal_checkpoint(PASSIVE); -- non-blocking diagnostic snapshot\n```\n\n`wal_checkpoint` returns three integers: **busy, log frames, checkpointed frames**. Interpret the tuple together with its mode:\n\n| Observation | Meaning | Next action |\n| --- | --- | --- |\n| `checkpointed == log` | All reported frames were copied | Verify whether WAL bytes stabilize/reset after new writes |\n| PASSIVE and `checkpointed < log` | A reader boundary or concurrent activity limited progress; PASSIVE's busy column is always `0` | Correlate repeated samples with reader age |\n| FULL/RESTART/TRUNCATE, `busy == 1` | The requested blocking checkpoint could not complete | Stop escalation and identify the holder |\n| Repeated unchanged remainder | Likely persistent boundary, not a one-off spike | Find long transactions, leaked cursors, or overlapping readers |\n\nAnalyze a captured tuple offline:\n\n```bash\npython3 scripts/analyze_checkpoint.py \\\n --input observations/checkpoint.json\n```\n\nInput example:\n\n```json\n{\"mode\":\"PASSIVE\",\"busy\":0,\"log_frames\":412000,\"checkpointed_frames\":900,\"wal_bytes\":3375104000,\"free_bytes\":4294967296,\"oldest_reader_seconds\":1800}\n```\n\n## Procedure\n\n### 1. Freeze the evidence, not the workload\n\nRecord UTC time, database path, database/WAL/SHM byte sizes, filesystem free bytes, process owners, deployment version, and recent write rate. Sample at least three times across the expected automatic-checkpoint interval.\n\n**Completion:** observations show whether WAL bytes and the uncheckpointed remainder are growing, stable, or recovering.\n\nDo not copy a live database by copying only the main file. Use the application's supported backup path or SQLite backup API.\n\n### 2. Confirm WAL mode and scope\n\nRun `PRAGMA journal_mode;` on the exact database. Map every process, worker, pool, desktop window, and maintenance job that can hold a connection. Check whether transaction scopes span streaming responses, iteration, sleeps, network calls, or user interaction.\n\n**Completion:** every known connection class has an owner and expected maximum read/write transaction duration.\n\n### 3. Take a PASSIVE checkpoint snapshot\n\nUse `PRAGMA wal_checkpoint(PASSIVE);` first. It checkpoints what it can without waiting for readers or writers. Capture the exact three-column tuple; do not reduce it to “success” merely because SQL execution returned normally.\n\nRepeat with timestamps. Compare `log - checkpointed`, WAL bytes, write raLine truncated
|
||||
{"type":"tool_use","timestamp":1788905075787,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_d7c038c2822a40e48d67c3e5","state":{"status":"completed","input":{"format":"text","url":"https://raw.githubusercontent.com/necat101/sqlite-deployment-safety-lab/master/README.md"},"output":"# SQLite Deployment Safety Lab\n\nDemonstrates real-world SQLite deployment issues from [HN #47637353](https://news.ycombinator.com/item?id=47637353) about running SQLite in production.\n\n## The HN Debate Summary\n\n**The incident**: Ultrathink.art lost 2 orders after **11 pushes in 2 hours** with overlapping Kamal deploys. Three containers simultaneously accessed the same SQLite WAL file on a shared Docker volume. Orders 16 and 17 succeeded in Stripe but never made it to the database.\n\n**HN discussion themes**:\n- **Operational failure, not SQLite failure**: Pushing straight to main, agents auto-deploying, no deploy serialization\n- **WAL shared-memory across containers**: Debated whether mmap'd `-shm` files work reliably across Docker containers (they do, via the shared volume)\n- **Single-writer limitation**: Many commenters clarified WAL allows concurrent readers but NOT concurrent writers\n- **Process termination risk**: Overlapping deploys + SIGTERM mid-transaction = data loss\n- **Backup safety**: `cp` vs SQLite's `.backup` API - raw copies can be corrupt\n\n## Experiments\n\nAll 5 experiments are now committed and ready to run:\n\n### ✅ Experiment 1: WAL Concurrency Limits\n**File**: `experiments/01_wal_concurrency.py` \n**Proves**: SQLite allows only ONE writer at a time, even in WAL mode. Concurrent writers get SQLITE_BUSY.\n\n**Validated output**:\n```\nSummary: 3 succeeded, 2 failed\nLost writes: 2\n✗ PROVEN: Even in WAL mode, SQLite allows only ONE writer at a time\n```\n\n### ✅ Experiment 2: Overlapping Deploys\n**File**: `experiments/02_overlapping_deploys.py` \n**Proves**: Simulates 3 containers with overlapping lifetimes writing to shared DB.\n\n**Note**: In controlled tests, SQLite properly serializes writes and no data is lost. Real data loss occurs when processes are SIGTERM'd mid-transaction or applications don't handle SQLITE_BUSY errors.\n\n### ✅ Experiment 3: Checkpoint Blocking\n**File**: `experiments/03_checkpoint_behavior.py` \n**Proves**: Long-running readers block checkpoints, causing WAL files to grow.\n\n### ✅ Experiment 4: Unsafe Backups\n**File**: `experiments/04_unsafe_backup.py` \n**Proves**: `cp` can create corrupt backups when copying live databases. Use `sqlite3 .backup` instead.\n\n### ✅ Experiment 5: Busy Timeout\n**File**: `experiments/05_busy_timeout.py` \n**Proves**: How `timeout: 5000` works - writers wait up to 5 seconds, then fail with SQLITE_BUSY.\n\n## Running the Lab\n\n```bash\ngit clone https://github.com/necat101/sqlite-deployment-safety-lab.git\ncd sqlite-deployment-safety-lab\n\n# Run all experiments\n./run_all.sh\n\n# Or run individually\npython3 experiments/01_wal_concurrency.py\npython3 experiments/02_overlapping_deploys.py\n# etc.\n```\n\n## Key Takeaways\n\n1. **SQLite WAL ≠ Multi-writer**: WAL enables concurrent readers + single writer. Writes are serialized.\n2. **Deploy serialization is mandatory**: Use GitHub Actions concurrency:\n ```yaml\n concurrency:\n group: production-deploy\n cancel-in-progress: false\n ```\n3. **Never use `cp` for backups**: Use `sqlite3 db \".backup backup.db\"` or the backup API\n4. **Monitor WAL size**: Long-running readers block checkpoints, causing unbounded growth\n5. **Handle SQLITE_BUSY**: With `timeout: 5000`, writers wait 5s then fail. App must retry or handle the error.\n\n## References\n\n- [HN Thread #47637353](https://news.ycombinator.com/item?id=47637353)\n- [Ultrathink: SQLite in Production](https://ultrathink.art/blog/sqlite-in-production-lessons)\n- [SQLite WAL Mode](https://sqlite.org/wal.html)\n- [How to Corrupt SQLite](https://sqlite.org/howtocorrupt.html)\n- [GitHub Actions: Control Workflow Concurrency](https://docs.github.com/en/actions/how-tos/write-workflows/choose-when-workflows-run/control-workflow-concurrency)\n\n## Validation Status\n\nSee [VALIDATED_RESULTS.md](VALIDATED_RESULTS.md) for detailed test output.\n\n**Experiment 1**: ✅ Fully validated with real output showing 2 of 5 writers failing \n**Experiments 2-5**: ✅ Scripts committed, validated locally - run them to see results\n","metadata":{"truncated":false},"title":"https://raw.githubusercontent.com/necat101/sqlite-deployment-safety-lab/master/README.md (text/plain; charset=utf-8)","time":{"start":1788905075522,"end":1788905075786}},"id":"prt_g001a0830d2bdc001hEkwnnL95","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830d11a4001ebTTYjiIn"}}
|
||||
{"type":"tool_use","timestamp":1788905075985,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_25b0964bdea54da495294764","state":{"status":"completed","input":{"format":"text","url":"https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo"},"output":"Reproduce SQLite WAL Checkpoint Starvation With One Forgotten Reader - DEV Community\n \n \n \n \n \n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n \n \n \n \n\n\n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n\n \n \n \n \n \n \n\n\n\n \n \n \n \n \n\n\n \n Skip to content\n \n \n \n Navigation menu\n \n\n\n \n \n \n \n\n\n\n \n \n \n \n \n \n Search\n \n\n\n \n\n \n Powered by Algolia\n Search\n \n\n\n \n \n \n \n \n\n \n \n \n \n Log in\n \n \n\n \n Create account\n \n \n \n \n\n\n\n \n \n DEV Community\n\n \n Close\n\n \n \n\n \n \n \n \n\n\n\n \n\n \n \n\n \n\n \n \n \n\n \n\n \n \n \n \n \n \n \n \n \n \n \n\n\n \n \n \n \n \n \n \n \n Add reaction\n \n \n\n \n \n \n \n \n \n \n\n \n Like\n \n\n\n \n \n \n \n \n\n \n Unicorn\n \n\n\n \n \n \n \n \n\n \n Exploding Head\n \n\n\n \n \n \n \n \n\n \n Raised Hands\n \n\n\n \n \n \n \n \n\n \n Fire\n \n\n\n \n \n\n\n\n \n \n \n\n\n \n \n \n \n\n \n Jump to Comments\n \n\n\n\n \n \n \n\n\n \n \n\n \n Save\n \n\n\n\n\n \n \n \n\n\n \n \n Boost\n \n\n\n\n \n \nPick as gem\n \n\n \n \n \n \n More...\n\n \n\n \n \n \n Copy link\n Copy link\n \n\n\n \n Copied to Clipboard\n \n\n \n \n Share to X\n \n \n Share to LinkedIn\n \n \n Share to Facebook\n \n \n Share to Mastodon\n \n \n\n \n \n \n Share Post via...\n \n\n Report Abuse\n \n \n \n \n\n \n\n \n \n\n\n \n \n\n \n \n \n \n \n \n \n \n Odd_Background_328\n \n \n \n Posted on Jul 20\n\n\n\n \n \n \n \n\n \n\n \n Reproduce SQLite WAL Checkpoint Starvation With One Forgotten Reader\n \n \n \n #sqlite\n #database\n #devops\n #monitoring\n \n \n \n\n \n \n A SQLite service can keep answering health checks while its WAL grows without a successful checkpoint. One forgotten read transaction is enough to reproduce the risk.\n\nRun a controlled drill:\n\n\nEnable WAL mode and create a small table.\nOpen connection A, begin a read transaction, and keep it open.\nFrom connection B, commit batches of writes for 60 seconds.\nSample WAL bytes and checkpoint results every second.\nRelease A and observe recovery.\n\n\n\n\nPRAGMA journal_mode=WAL;\nPRAGMA wal_checkpoint(PASSIVE);\n\n\n\n Enter fullscreen mode\n \n\n\n Exit fullscreen mode\n \n\n\n\n\n\n\n\n\nRecord the three checkpoint counters plus duration, WAL file size, oldest transaction age, write latency, and free disk bytes. A green SELECT 1 says nothing about checkpoint progress.\n\nMy fault-injection gate looks like this:\n\n\n\nGiven: one reader holds its transaction\nWhen: 10,000 writes commit\nThen: writes remain bounded\nAnd: WAL growth triggers an alert before the disk budget\nWhen: the reader closes\nThen: checkpoint progress resumes and WAL size converges\n\n\n\n Enter fullscreen mode\n \n\n\n Exit fullscreen mode\n \n\n\n\n\n\n\n\n\nDo not stLine truncated
|
||||
{"type":"step_finish","timestamp":1788905076171,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d3510001QuqhlaE8m","reason":"tool-calls","snapshot":"26ec97ef1c96bbb64bd6661d5c66425243adb513","messageID":"msg_g001a0830d11a4001ebTTYjiIn","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":38860,"input":7939,"output":201,"reasoning":0,"cache":{"write":0,"read":30720}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905084153,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d54f7001bmFPAaw63","messageID":"msg_g001a0830d36c0001F51hkFY1e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"58de6f87d294dcf029c391947fb101235c7ad518","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905085627,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d5591002sCbzZEY2Y","messageID":"msg_g001a0830d36c0001F51hkFY1e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"text","text":"Good progress — four more sources read. Fetching the remaining priority sources (productionhardening.org credibility check, the \"10x\" dev.to post, pytest-benchmark docs, Stack Overflow Q&A):","time":{"start":1788905084305,"end":1788905085625}}}
|
||||
{"type":"tool_use","timestamp":1788905085685,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_575d8cd6f0db46e799f3bfe1","state":{"status":"completed","input":{"format":"text","url":"https://pypi.org/project/pytest-benchmark/"},"output":"pytest-benchmark · PyPI\n \n \n \n \n \n \n \n \n \n \n \n\n \n \n \n \n \n \n \n \n \n Skip to main content\n Switch to mobile version\n \n \n \n \n\n \n \n \n \n \n \n \n \n \n Search PyPI\n \n \n \n Search\n \n \n \n \n \n \n \n Help\n \n \n Docs\n \n \n Log in\n \n \n Register\n \n \n \n \n \n \n \n \n \n Help\n \n \n Docs\n \n \n Log in\n \n \n Register\n \n \n \n\n \n \n \n \n \n \n \n Deutsch\n \n \n \n \n English\n \n \n \n \n español\n \n \n \n \n Esperanto\n \n \n \n \n français\n \n \n \n \n português (Brasil)\n \n \n \n \n Ελληνικά\n \n \n \n \n русский\n \n \n \n \n українська\n \n \n \n \n עברית\n \n \n \n \n 中文 (简体)\n \n \n \n \n 中文 (繁體)\n \n \n \n \n 日本語\n \n \n \n \n 한국어\n \n \n \n \n \n \n\n\n \n \n Search PyPI\n \n \n \n \n Search\n \n \n \n\n\n \n pytest-benchmark 5.3.0\n A ``pytest`` fixture for benchmarking code. It will group the tests into rounds that are calibrated to the chosen timer.\n \n \n pip install pytest-benchmark\n \n \n Copy PIP instructions\n \n \n \n \n \n\n \n \n \n \n \n \n \nDescription \n \n \n \n \n \n \nDownload files \n \n \n \n \n \n \nRelease history \n \n \n \n \n \n \n \n\n \n \n \n\ndocs\n \n\ntests\n \n\npackage\n \n\n\n\nA pytest fixture for benchmarking code. It will group the tests into rounds that are calibrated to the chosen\ntimer.\nSee calibration and FAQ.\n\nFree software: BSD 2-Clause License\n\n\nInstallation\npip install pytest-benchmark\n\n\nDocumentation\nFor latest release: pytest-benchmark.readthedocs.org/en/stable.\nFor master branch (may include documentation fixes): pytest-benchmark.readthedocs.io/en/latest.\n\n\nExamples\nBut first, a prologue:\n\nThis plugin tightly integrates into pytest. To use this effectively you should know a thing or two about pytest first.\nTake a look at the introductory material\nor watch talks.\nFew notes:\n\nThis plugin benchmarks functions and only that. If you want to measure block of code\nor whole programs you will need to write a wrapper function.\nIn a test you can only benchmark one function. If you want to benchmark many functions write more tests or\nuse parametrization.\nTo run the benchmarks you simply use pytest to run your “tests”. The plugin will automatically do the\nbenchmarking and generate a result table. Run pytest --help for more details.\n\n\nThis plugin provides a benchmark fixture. This fixture is a callable object that will benchmark any function passed\nto it.\nExample:\ndef something(duration=0.000001):\n \"\"\"\n Function that needs some serious benchmarking.\n \"\"\"\n time.sleep(duration)\n # You may return anything you want, like the result of a computation\n return 123\n\ndef test_my_stuff(benchmark):\n # benchmark something\n result = benchmark(something)\n\n # Extra code, to verify that the run completed correctly.\n # Sometimes you may want to check the result, fast functions\n # are no good if they return incorrect results :-)\n assert result == 123\nYou can also pass extra arguments:\ndef test_my_stuff(benchmark):\n benchmark(time.sleep, 0.02)\nOr even keyword arguments:\ndef test_my_stuff(benchmark):\n benchmark(tLine truncated
|
||||
{"type":"tool_use","timestamp":1788905085717,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_bf6317a8ec4f4589a8a4e5a5","state":{"status":"completed","input":{"format":"text","url":"https://productionhardening.org/wal-optimization-concurrency-tuning/"},"output":"WAL Optimization & Concurrency Tuning · SQLite Hardening\n \n \n \n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n \n \n \n\n \n \n \n \n \n \n \n\n \n \n Skip to content\n\n \n \n \n \n SQLite Production Hardening\n & WAL Optimization\n \n \n\n \n \n \n\n \n \n Home\n \n Architecture & Hardening\n \n WAL & Concurrency\n \n Backup & Recovery\n \n All content\n \n \n \n\n\n \n \n \n \n Home\n ContentWAL Optimization & Concurrency Tuning\n\n\n\n \n WAL Optimization & Concurrency Tuning #\nSQLite’s Write-Ahead Logging mode is the journaling mechanism for modern concurrent deployments, yet out-of-the-box configurations rarely survive the concurrency and durability demands of edge telemetry, desktop synchronization engines, Python automation pipelines, or embedded controllers. In production, WAL is not a performance toggle you flip and forget; it is a crash-safety contract that dictates how writes are staged, how readers isolate snapshots, and how the database recovers after abrupt power loss. This reference strips away academic abstractions and delivers hardened tuning strategies, explicit PRAGMA trade-offs, measurable concurrency thresholds, and deterministic fallback routing — the same discipline applied across the companion SQLite Architecture & Production Hardening reference. Every configuration here has been validated against SD-card degradation, eMMC wear leveling, and high-contention desktop workloads, and each section links down to a dedicated page where a single knob is tuned in depth.\nCore Mechanics & Crash-Safety Architecture #\nWAL operates by appending committed transactions to a separate -wal file before those frames are ever applied to the main database file. Readers bypass the main file’s write locks by reconstructing their snapshot from the WAL, which is what enables true concurrent read/write isolation. A third file, the -shm shared-memory segment, acts as a lock index and WAL page map, coordinating access across every connection and process attached to the database. This architecture eliminates the reader-writer contention that crippled the legacy rollback journaling modes, but it introduces specific failure modes that must be engineered around rather than assumed away.\n\n\n The WAL write path in SQLite\n A single writer connection appends committed frames to the sibling minus-wal log file. Concurrent readers reconstruct their snapshots directly from that log rather than blocking on the main database. The minus-shm shared-memory segment indexes WAL pages and coordinates locking across every connection. A later checkpoint merges the accumulated frames back into the main database file.\n \n \n \n \n \n \n \n \n \n \n Writer\n one at a time\n \n append\n \n -wal log file\n committed frames\n + per-frame checksums\n \n checkpoint (merge)\n \n \n \n \n \n Main database\n never half-written\n \n \n -shm index\n WAL page map + locks\n \n coordinates\n access\n \n \n Reader 1\n \n Reader 2\n \n \n consistent snapshot reads\n\nThe WAL write path: a single writer appends frames to the -wal file while readers continue from a consistent snapshot, and a checkpoint later merges frames back into the main database.\n\nCrash safety in WAL mode rests on three guarantees: atomic commit, ordered flush, and deterministic recovery. When a transaction commits, SQLite appends its frames to the WAL — each frame carrying a 32-bit checksum and a commit marker — and only migrates those frames into the main database file during a later checkpoint. If power fails mid-commit, the WAL retains the last fully committed transaction and discards any torn trailing frame whose checksum does not validate; SQLite replays the valid prefix on the next open. The main database file is therefore never left half-written.\nThese guarantees degrade the instant synchronization settings are relaxed or the underlying storage controller reorders writes. Setting synchronous=OFF bypasses fsync() entirely, trading durability for throughput — unacceptable for edge devices subject to brownouts or desktop apps holding financial state. The production baseline is synchronous=NORMAL, which guarantees the database can never corrupt even though commits made in the moments before a power cut may be rolled back. For critical embedded control loops where every acknowledged write must survive power failure, synchronous=FULL remains mandatory despite a 15–30% write-lLine truncated
|
||||
{"type":"tool_use","timestamp":1788905085745,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_fb212ad7f25b4581a9364999","state":{"status":"error","input":{"format":"text","url":"https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency"},"error":"StatusCode: non 2xx status code (403 GET https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency)","time":{"start":1788905085629,"end":1788905085744}},"id":"prt_g001a0830d58e70015sRrY0BMZ","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830d36c0001F51hkFY1e"}}
|
||||
{"type":"tool_use","timestamp":1788905085761,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_11f7d2bd42224e5291b02237","state":{"status":"completed","input":{"format":"text","url":"https://dev.to/lumin-playstar/sqlite-wal-mode-10x-performance-for-python-apps-4ic"},"output":"SQLite WAL Mode: 10x Performance for Python Apps - DEV Community\n \n \n \n \n \n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n \n \n \n \n\n\n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n\n \n\n \n \n \n \n \n \n\n\n\n \n \n \n \n \n\n\n \n Skip to content\n \n \n \n Navigation menu\n \n\n\n \n \n \n \n\n\n\n \n \n \n \n \n \n Search\n \n\n\n \n\n \n Powered by Algolia\n Search\n \n\n\n \n \n \n \n \n\n \n \n \n \n Log in\n \n \n\n \n Create account\n \n \n \n \n\n\n\n \n \n DEV Community\n\n \n Close\n\n \n \n\n \n \n \n \n\n\n\n \n\n \n \n\n \n\n \n \n \n\n \n\n \n \n \n \n \n \n \n \n \n \n \n\n\n \n \n \n \n \n \n \n \n Add reaction\n \n \n\n \n \n \n \n \n \n \n\n \n Like\n \n\n\n \n \n \n \n \n\n \n Unicorn\n \n\n\n \n \n \n \n \n\n \n Exploding Head\n \n\n\n \n \n \n \n \n\n \n Raised Hands\n \n\n\n \n \n \n \n \n\n \n Fire\n \n\n\n \n \n\n\n\n \n \n \n\n\n \n \n \n \n\n \n Jump to Comments\n \n\n\n\n \n \n \n\n\n \n \n\n \n Save\n \n\n\n\n\n \n \n \n\n\n \n \n Boost\n \n\n\n\n \n \nPick as gem\n \n\n \n \n \n \n More...\n\n \n\n \n \n \n Copy link\n Copy link\n \n\n\n \n Copied to Clipboard\n \n\n \n \n Share to X\n \n \n Share to LinkedIn\n \n \n Share to Facebook\n \n \n Share to Mastodon\n \n \n\n \n \n \n Share Post via...\n \n\n Report Abuse\n \n \n \n \n\n \n\n \n \n\n\n \n \n\n \n \n \n \n \n \n \n \n Ilja Fedorow (PLAY-STAR)\n \n \n \n Posted on Mar 10\n\n\n\n \n \n \n \n\n \n\n \n SQLite WAL Mode: 10x Performance for Python Apps\n \n \n \n #python\n #sqlite\n #database\n #performance\n \n \n \n\n \n \n \n \n \n SQLite WAL Mode: 10x Performance for Python Apps\n\n\n\n\n\nYou're building a Python application, and like many developers, you've chosen SQLite for its unparalleled simplicity, zero-configuration, and embedded nature. It's fantastic for local data storage, small-to-medium web applications, desktop apps, and even mobile backends.\n\nBut then, your application starts to grow. More users, more data, more concurrent operations. Suddenly, that fast, reliable SQLite database starts to feel sluggish. Writes block reads, reads block writes, and your once-snappy app feels like it's wading through mud.\n\nThe problem? You're likely still using SQLite's default journaling mode, which, while robust, isn't designed for high concurrency or write-heavy workloads.\n\nThe solution? A single PRAGMA statement can unlock a hidden superpower in SQLite, transforming its performance and concurrency profile: Write-Ahead Logging (WAL) mode. For many Python applications, switching to WAL mode can deliver a 10x or even greater performance boost, especially for writes and concurrent operations.\n\nLet's dive in and see how.\n\n\n \n \n The Bottleneck: Understanding Traditional Journaling\n\n\nBy default, SQLite operates in DELETE journal Line truncated
|
||||
{"type":"step_finish","timestamp":1788905085785,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d5b41001C0dSHb6L5","reason":"tool-calls","snapshot":"c649d3eb645de080d8ecccca8d6a8fdde317aa91","messageID":"msg_g001a0830d36c0001F51hkFY1e","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":45274,"input":6396,"output":222,"reasoning":0,"cache":{"write":0,"read":38656}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905091626,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d7229001ooAMmTvuF","messageID":"msg_g001a0830d5b9a001Zym7xf6f2","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"b0b20158a5888b6600aea12de6d3633199ae5e2a","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905092413,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_3ad029af72694e328e9ef8df","state":{"status":"completed","input":{"format":"markdown","url":"https://pytest-benchmark.readthedocs.io/en/latest/index.html"},"output":" \n\nContents Menu Expand Light mode Dark mode Auto light/dark, in light mode Auto light/dark, in dark mode [Skip to content](#furo-main-content) \n\n[ pytest-benchmark 5.3.0 documentation ](#)\n\n* [Installation](https://pytest-benchmark.readthedocs.io/en/latest/installation.html)\n* [Usage](https://pytest-benchmark.readthedocs.io/en/latest/usage.html)\n* [Calibration](https://pytest-benchmark.readthedocs.io/en/latest/calibration.html)\n* [Pedantic mode](https://pytest-benchmark.readthedocs.io/en/latest/pedantic.html)\n* [Comparing past runs](https://pytest-benchmark.readthedocs.io/en/latest/comparing.html)\n* [Hooks](https://pytest-benchmark.readthedocs.io/en/latest/hooks.html)\n* [Frequently Asked Questions](https://pytest-benchmark.readthedocs.io/en/latest/faq.html)\n* [Glossary](https://pytest-benchmark.readthedocs.io/en/latest/glossary.html)\n* [Contributing](https://pytest-benchmark.readthedocs.io/en/latest/contributing.html)\n* [Authors](https://pytest-benchmark.readthedocs.io/en/latest/authors.html)\n* [Changelog](https://pytest-benchmark.readthedocs.io/en/latest/changelog.html)\n\n[ Back to top ](#) \n\n[ View this page ](https://github.com/ionelmc/pytest-benchmark/blob/master/docs/index.rst?plain=true \"View this page\") \n\n[ Edit this page ](https://github.com/ionelmc/pytest-benchmark/edit/master/docs/index.rst \"Edit this page\") \n\n# Welcome to pytest-benchmark’s documentation\n\nThis plugin provides a benchmark fixture. This fixture is a callable object that will benchmark any function passed to it.\n\nNotable features and goals:\n\n* Sensible defaults and automatic calibration for micro-benchmarks\n* Good integration with pytest\n* Comparison and regression tracking\n* Exhaustive statistics\n* JSON export\n\nExamples:\n\ndef something(duration=0.000001):\n \"\"\"\n Function that needs some serious benchmarking.\n \"\"\"\n time.sleep(duration)\n # You may return anything you want, like the result of a computation\n return 123\n\ndef test_my_stuff(benchmark):\n # benchmark something\n result = benchmark(something)\n\n # Extra code, to verify that the run completed correctly.\n # Sometimes you may want to check the result, fast functions\n # are no good if they return incorrect results :-)\n assert result == 123\n\ndef test_my_stuff_different_arg(benchmark):\n # benchmark something, but add some arguments\n result = benchmark(something, 0.001)\n assert result == 123\n\n## Screenshots[¶](#screenshots \"Link to this heading\")\n\nNormal run:\n\n \n\nCompare mode (`--benchmark-compare`):\n\n \n\nHistogram (`--benchmark-histogram`):\n\n \n\n> Also, it has [nice tooltips](https://cdn.rawgit.com/ionelmc/pytest-benchmark/master/docs/sample.svg).\n\n# User guide[¶](#user-guide \"Link to this heading\")\n\n* [Installation](https://pytest-benchmark.readthedocs.io/en/latest/installation.html)\n* [Usage](https://pytest-benchmark.readthedocs.io/en/latest/usage.html)\n * [Commandline options](https://pytest-benchmark.readthedocs.io/en/latest/usage.html#commandline-options)\n * [Markers](https://pytest-benchmark.readthedocs.io/en/latest/usage.html#markers)\n * [Extra info](https://pytest-benchmark.readthedocs.io/en/latest/usage.html#extra-info)\n * [Patch utilities](https://pytest-benchmark.readthedocs.io/en/latest/usage.html#patch-utilities)\n* [Calibration](https://pytest-benchmark.readthedocs.io/en/latest/calibration.html)\n * [How many rounds?](https://pytest-benchmark.readthedocs.io/en/latest/calibration.html#how-many-rounds)\n* [Pedantic mode](https://pytest-benchmark.readthedocs.io/en/latest/pedantic.html)\n * [Reference](https://pytest-benchmark.readthedocs.io/en/latest/pedantic.html#reference)\n* [Comparing past runs](https://pytest-benchmark.readthedocs.io/en/latest/comparing.html)\n * [Comparing outside of pytest](https://pytest-benchmark.readthedocs.io/en/latest/comparing.html#comparing-outside-of-pytest)\n * [Plotting](https://pytest-benchmark.readthedocs.io/en/latest/comparing.html#plotting)\n* [Hooks](https://pytest-benchmark.readthedocs.io/en/latest/hooks.html)\n * [pytest\\_benchmark\\_compare\\_machine\\_info()](https://pytest-benchmark.readtheLine truncated
|
||||
{"type":"step_finish","timestamp":1788905092436,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d753c001egwrL8d7L","reason":"tool-calls","snapshot":"09f2d07acc065935b8a28c6f6f6529473e54c36d","messageID":"msg_g001a0830d5b9a001Zym7xf6f2","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":59278,"input":14192,"output":30,"reasoning":0,"cache":{"write":0,"read":45056}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905101102,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830d972c001avl1AJkT5","messageID":"msg_g001a0830d7581001kMaq7TzLr","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"05311f613b2995ad08e1ebc230f951aae6b35c00","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905104124,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"webfetch","callID":"call_892fdff7ff3d4b14b560ba02","state":{"status":"completed","input":{"format":"markdown","url":"https://r.jina.ai/https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency"},"output":"Title: Just a moment...\n\nURL Source: https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency\n\nWarning: Target URL returned error 403: Forbidden\n\nMarkdown Content:\n\n","metadata":{"truncated":false},"title":"https://r.jina.ai/https://stackoverflow.com/questions/393554/python-sqlite3-and-concurrency (text/plain; charset=utf-8)","time":{"start":1788905101749,"end":1788905104123}},"id":"prt_g001a0830d972d001Nhkxm3nld","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830d7581001kMaq7TzLr"}}
|
||||
{"type":"step_finish","timestamp":1788905104149,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830da2fc001GamjsjvSA","reason":"tool-calls","snapshot":"718eddb8dc73f62916d6cf92a076e59e62f79ed7","messageID":"msg_g001a0830d7581001kMaq7TzLr","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":63116,"input":63074,"output":42,"reasoning":0,"cache":{"write":0,"read":0}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905113893,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830dc923001beWd7TaS6","messageID":"msg_g001a0830da3340011Hc6jiqts","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"da6d5aa0f3a895822d8e7dde01046df0a1636e27","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905116673,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"bash","callID":"call_925dcdac215c48f786b690f8","state":{"status":"completed","input":{"command":"curl -s --max-time 30 -A \"Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/126.0 Safari/537.36\" \"https://api.stackexchange.com/2.3/questions/393554?site=stackoverflow&filter=withbody\" | python3 -c \"import json,sys; d=json.load(sys.stdin); [print('TITLE:', q['title'], '\\nSCORE:', q['score'], '\\n\\n', q['body'][:3500]) for q in d.get('items',[])]\"","description":"Fetch Stack Overflow Q via Stack Exchange API"},"output":"TITLE: Python sqlite3 and concurrency \nSCORE: 115 \n\n <p>I have a Python program that uses the \"threading\" module. Once every second, my program starts a new thread that fetches some data from the web, and stores this data to my hard drive. I would like to use sqlite3 to store these results, but I can't get it to work. The issue seems to be about the following line:</p>\n\n<pre><code>conn = sqlite3.connect(\"mydatabase.db\")\n</code></pre>\n\n<ul>\n<li>If I put this line of code inside each thread, I get an OperationalError telling me that the database file is locked. I guess this means that another thread has mydatabase.db open through a sqlite3 connection and has locked it.</li>\n<li>If I put this line of code in the main program and pass the connection object (conn) to each thread, I get a ProgrammingError, saying that SQLite objects created in a thread can only be used in that same thread.</li>\n</ul>\n\n<p>Previously I was storing all my results in CSV files, and did not have any of these file-locking issues. Hopefully this will be possible with sqlite. Any ideas?</p>\n\n","metadata":{"output":"TITLE: Python sqlite3 and concurrency \nSCORE: 115 \n\n <p>I have a Python program that uses the \"threading\" module. Once every second, my program starts a new thread that fetches some data from the web, and stores this data to my hard drive. I would like to use sqlite3 to store these results, but I can't get it to work. The issue seems to be about the following line:</p>\n\n<pre><code>conn = sqlite3.connect(\"mydatabase.db\")\n</code></pre>\n\n<ul>\n<li>If I put this line of code inside each thread, I get an OperationalError telling me that the database file is locked. I guess this means that another thread has mydatabase.db open through a sqlite3 connection and has locked it.</li>\n<li>If I put this line of code in the main program and pass the connection object (conn) to each thread, I get a ProgrammingError, saying that SQLite objects created in a thread can only be used in that same thread.</li>\n</ul>\n\n<p>Previously I was storing all my results in CSV files, and did not have any of these file-locking issues. Hopefully this will be possible with sqlite. Any ideas?</p>\n\n","exit":0,"description":"Fetch Stack Overflow Q via Stack Exchange API","truncated":false},"title":"Fetch Stack Overflow Q via Stack Exchange API","time":{"start":1788905116661,"end":1788905116671}},"id":"prt_g001a0830dc925001unvY50qfE","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","messageID":"msg_g001a0830da3340011Hc6jiqts"}}
|
||||
{"type":"step_finish","timestamp":1788905116720,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830dd401001LLZhrjxyg","reason":"tool-calls","snapshot":"6a3d76a87e9d5a8fb5037c7a9c967b5f5e590b56","messageID":"msg_g001a0830da3340011Hc6jiqts","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":63320,"input":59,"output":157,"reasoning":0,"cache":{"write":0,"read":63104}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905127544,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830dfe76001FEXNgxqz2","messageID":"msg_g001a0830dd44e0018Xur0Z1Jf","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"aa278dc73b823028645e3cf323a6394db71525c0","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905129847,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"bash","callID":"call_9dae28e0e88f4b1ea7592637","state":{"status":"completed","input":{"command":"curl -s --max-time 30 \"https://api.stackexchange.com/2.3/questions/393554/answers?site=stackoverflow&filter=withbody&sort=votes\" | python3 -c \"\nimport json,sys,html\nd=json.load(sys.stdin)\nfor a in d.get('items',[])[:4]:\n print('=== ANSWER score', a['score'], 'accepted:', a.get('is_accepted'))\n print(html.unescape(a['body'])[:2200])\n print()\n\"","description":"Fetch top answers for SO 393554"},"output":"=== ANSWER score 214 accepted: False\n<p>Contrary to popular belief, newer versions of sqlite3 <strong>do</strong> support access from multiple threads.</p>\n\n<p>This can be enabled via optional keyword argument <code>check_same_thread</code>:</p>\n\n<pre><code>sqlite.connect(\":memory:\", check_same_thread=False)\n</code></pre>\n\n\n=== ANSWER score 54 accepted: True\n<p>You can use consumer-producer pattern. For example you can create queue that is shared between threads. First thread that fetches data from the web enqueues this data in the shared queue. Another thread that owns database connection dequeues data from the queue and passes it to the database. </p>\n\n\n=== ANSWER score 20 accepted: False\n<p>The following found on <a href=\"http://mail.python.org/pipermail/python-list/2010-March/1239789.html\" rel=\"noreferrer\">mail.python.org.pipermail.1239789</a>\n<br/><br/>\nI have found the solution. I don't know why python documentation has not a single word about this option. So we have to add a new keyword argument to connection function \nand we will be able to create cursors out of it in different thread. So use:</p>\n\n<pre><code>sqlite.connect(\":memory:\", check_same_thread = False)\n</code></pre>\n\n<p>works out perfectly for me. Of course from now on I need to take care \nof safe multithreading access to the db. Anyway thx all for trying to help.</p>\n\n\n=== ANSWER score 15 accepted: False\n<p>Switch to <a href=\"http://docs.python.org/library/multiprocessing.html\" rel=\"noreferrer\">multiprocessing</a>. It is much better, scales well, can go beyond the use of multiple cores by using multiple CPUs, and the interface is the same as using python threading module.</p>\n\n<p>Or, as Ali suggested, just use <a href=\"http://www.sqlalchemy.org/docs/05/reference/sqlalchemy/pooling.html#sqlalchemy.pool.SingletonThreadPool\" rel=\"noreferrer\">SQLAlchemy's thread pooling mechanism</a>. It will handle everything for you automatically and has many extra features, just to quote some of them:</p>\n\n<ol>\n<li>SQLAlchemy includes dialects for SQLite, Postgres, MySQL, Oracle, MS-SQL, Firebird, MaxDB, MS Access, Sybase and Informix; IBM has also released a DB2 driver. So you don't have to rewrite your application if you decide to move away from SQLite.</li>\n<li>The Unit Of Work system, a central part of SQLAlchemy's Object Relational Mapper (ORM), organizes pending create/insert/update/delete operations into queues and flushes them all in one batch. To accomplish this it performs a topological \"dependency sort\" of all modified items in the queue so as to honor foreign key constraints, and groups redundant statements together where they can sometimes be batched even further. This produces the maxiumum efficiency and transaction safety, and minimizes chances of deadlocks.</li>\n</ol>\n\n\n","metadata":{"output":"=== ANSWER score 214 accepted: False\n<p>Contrary to popular belief, newer versions of sqlite3 <strong>do</strong> support access from multiple threads.</p>\n\n<p>This can be enabled via optional keyword argument <code>check_same_thread</code>:</p>\n\n<pre><code>sqlite.connect(\":memory:\", check_same_thread=False)\n</code></pre>\n\n\n=== ANSWER score 54 accepted: True\n<p>You can use consumer-producer pattern. For example you can create queue that is shared between threads. First thread that fetches data from the web enqueues this data in the shared queue. Another thread that owns database connection dequeues data from the queue and passes it to the database. </p>\n\n\n=== ANSWER score 20 accepted: False\n<p>The following found on <a href=\"http://mail.python.org/pipermail/python-list/2010-March/1239789.html\" rel=\"noreferrer\">mail.python.org.pipermail.1239789</a>\n<br/><br/>\nI have found the solution. I don't know why python documentation has not a single word about this option. So we have to add a new keyword argument to connection function \nand we will be able to create cursors out of it in different thread. So use:</p>\n\n<pre><code>sqlite.connect(\":memory:\", check_same_thread = False)\n</code></pre>\n\n<p>works out perfectly for me. Of course from now on I need to take care \nof safe multithreading access to the db. Anyway thx all for trying to help.</p>\n\n\n=== ANSWER score 15 accepted: False\n<p>Switch to <a href=\"http://docs.python.org/library/multLine truncated
|
||||
{"type":"step_finish","timestamp":1788905129867,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830e0777001XeLSdd018","reason":"tool-calls","snapshot":"f878a57ca77c11229d3d098ef912f33c8f30d4a9","messageID":"msg_g001a0830dd44e0018Xur0Z1Jf","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":63710,"input":407,"output":135,"reasoning":0,"cache":{"write":0,"read":63168}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905140124,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830e2f9a001jKgE9Izi6","messageID":"msg_g001a0830e07a9001MKP1i1O2V","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"224999b11c6d48cead95009ffcb8db0f34049d5d","type":"step-start"}}
|
||||
{"type":"tool_use","timestamp":1788905239776,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"type":"tool","tool":"write","callID":"call_f6899f12aff44bc091df2541","state":{"status":"completed","input":{"content":"{\n \"process_id\": \"research-262-r1\",\n \"issue\": 262,\n \"round\": 1,\n \"stage\": \"OUTWARD_READING\",\n \"title\": \"sqlite WAL performance in concurrent Python applications (acceptance-test question, repo-specific)\",\n \"method_note\": \"Primary sources fetched and read in full this stage plus in the prior partially-completed OUTWARD_READING session (ses_-ffe5f7d08ef0effe7822prgaw, which read S1-S3). No new search queries generated, per stage contract. Claims below carry source IDs (S1-S10); repo claims from INWARD (I1-I5) are referenced for mapping only.\",\n \"sources\": {\n \"S1\": {\n \"url\": \"https://sqlite.org/wal.html\",\n \"type\": \"official_docs\",\n \"authority\": \"high (canonical SQLite documentation)\",\n \"read_in\": \"prior session (ses_-ffe5f7d08ef0effe7822prgaw); claims verified against that session's extraction\",\n \"limitations\": [\"Documents C-library behavior; Python sqlite3 module wraps the same library so semantics carry over, but Python-side ergonomics (isolation_level, implicit transactions) are not covered by this source\"]\n },\n \"S2\": {\n \"url\": \"https://sqlite.org/c3ref/wal_checkpoint_v2.html\",\n \"type\": \"official_docs\",\n \"authority\": \"high (canonical SQLite C API reference)\",\n \"read_in\": \"prior session\",\n \"limitations\": [\"C API reference; PRAGMA wal_checkpoint exposes the same tuple (busy, log, checkpointed) per S5, but the C-API framing (pnLog/pnCkpt out-params) is not literally what Python callers see\"]\n },\n \"S3\": {\n \"url\": \"https://github.com/joedougherty/sqlite3_concurrent_writes_test_suite\",\n \"type\": \"repro_test_suite_github\",\n \"authority\": \"medium (small public repo: 22 stars, 3 forks, 20 commits; author's own caveats are candid)\",\n \"read_in\": \"prior session (README)\",\n \"limitations\": [\"No busy_timeout/timeout configuration\", \"Write-only contention; no reader/writer mix\", \"No WAL-size or checkpoint observation\", \"Small scale (ceiling found ~500 simultaneous single-row inserts)\", \"Tests threads/processes against one DB but not a separate-process RW+RO mix\"]\n },\n \"S4\": {\n \"url\": \"https://raw.githubusercontent.com/necat101/sqlite-deployment-safety-lab/master/README.md\",\n \"type\": \"repro_lab_github\",\n \"authority\": \"medium (README reports validated experiment output; experiments are Python scripts committed in repo; grounded in a real production incident via HN thread #47637353)\",\n \"limitations\": [\"README summarizes results; per-experiment scripts were not individually read this stage\", \"Experiment 2 note is the author's own: controlled tests show NO data loss without SIGTERM/unhandled-SQLITE_BUSY\", \"Production-incident generalization comes from one anecdotal incident (Ultrathink.art)\"]\n },\n \"S5\": {\n \"url\": \"https://www.sqliteforum.com/p/checkpoint-algorithms-and-wal-performance\",\n \"type\": \"engineering_writeup_newsletter\",\n \"authority\": \"medium-low (Substack-style explainer 'SQLite Forum' by Jenny Muralidharan, May 2026; technically consistent with S1/S2 but is not sqlite.org)\",\n \"limitations\": [\"Not an official SQLite source despite the domain name\", \"No measurements of its own; all claims qualitative\", \"Minor imprecision: says auto-checkpoint 'happens in the background by a reader connection' — S1 states the COMMITTING thread runs it (this source's framing is wrong per S1)\"]\n },\n \"S6\": {\n \"url\": \"https://github.com/mouadja02/skills/blob/main/skills/databases/sqlite-wal-checkpoint-starvation-diagnostics/SKILL.md\",\n \"type\": \"diagnostic_runbook\",\n \"authority\": \"medium (operational runbook; explicitly separates sourced facts from original operational guidance; cites sqlite.org docs and real issue trackers)\",\n \"limitations\": [\"Operational recommendations (alert ratios, sample counts, escalation order) are author-declared 'not SQLite guarantees'\", \"Issue references (Syncthing #10559, OpenCode #37495, Codex #30517) were not independently opened this stage\"]\n },\n \"S7\": {\n \"url\": \"https://dev.to/odd_background_328/reproduce-sqlite-wal-checkpoint-starvation-with-one-forgotten-reader-4jfo\",\n \"type\": \"engineering_writeup_repro\",\n \"authority\": \"medium-low (individual practitioner post, Jul 2026, with one substantive expert comment; methodology is coherent and cites sqlite.org/wal.html for the end-mark mechanism)\",\n \"limitations\": [\"No raw numbers published; claims are about the drill design, not measured results\", \"Single author, no peer review\"]\n },\n \"S8\": {\n \"url\": \"https:/Line truncated
|
||||
{"type":"step_finish","timestamp":1788905239802,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830fb4df0011VuesD2at","reason":"tool-calls","snapshot":"df3a7cef94ef70ddd656e7112645c86c5f3e16ae","messageID":"msg_g001a0830e07a9001MKP1i1O2V","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":69549,"input":746,"output":5187,"reasoning":0,"cache":{"write":0,"read":63616}},"cost":0}}
|
||||
{"type":"step_start","timestamp":1788905249238,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830fd9d5001DEQnxbaKT","messageID":"msg_g001a0830fb519001EiA8yDTTE","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","snapshot":"e5c0a925b104b1e13fe1f28a8f977f8e38a5d869","type":"step-start"}}
|
||||
{"type":"text","timestamp":1788905262924,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a0830fda5e002o7BlXI32C","messageID":"msg_g001a0830fb519001EiA8yDTTE","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"text","text":"Stage artifact written to `/mnt/workdrive/research-stage/research/issue-262/outward_reading.json`. Summary of the extraction:\n\n## OUTWARD_READING artifact — research-262-r1 (issue 262)\n\n**Sources read (11, IDs S1–S11):** sqlite.org/wal.html (S1) and wal_checkpoint_v2.html (S2) + joedougherty test suite (S3) carried from the prior partially-completed reading session; this session read S4 sqlite-deployment-safety-lab (HN #47637353 repro lab), S5 sqliteforum.com checkpoint guide, S6 WAL checkpoint-starvation diagnostic runbook, S7 dev.to one-forgotten-reader repro, S8 productionhardening.org (credibility unverified — anonymous site), S9 dev.to \"10x\" post (low authority, contains a factual error), S10 pytest-benchmark docs/PyPI, S11 Stack Overflow 393554 (via Stack Exchange API after 403 on direct fetch).\n\n**Claims extracted (19, O1–O19), highlights:**\n- **O1/O4 (S1, authoritative):** WAL = readers don't block writers, but only ONE writer at a time; SQLITE_BUSY still possible in WAL; WAL mode is persistent across connections; same-host only. → The acceptance test must not assert WAL raises multi-writer throughput.\n- **O2/O3 (S1):** reader \"end marks\" → long read txn starves checkpoints → unbounded WAL growth; read perf degrades with WAL size; auto-checkpoint (1000 pages) runs on the **committing** thread → tail-latency spikes. Measurable acceptance signals.\n- **O6 (S2):** `PRAGMA wal_checkpoint(PASSIVE)` returns the (busy, log, checkpointed) tuple — the non-blocking observation primitive for the test.\n- **O7/O8 (S3):** closest prior-art harness (pytest + multiprocessing, lock-error detection, ~500-writer ceiling); author's own finding that WAL didn't raise the concurrent-write ceiling.\n- **O9/O10 (S4):** incident-grounded failure modes (overlapping multi-process writers, SIGTERM mid-transaction, unhandled SQLITE_BUSY) + validated repro experiments.\n- **O11–O13 (S5–S7):** PASSIVE busy=0 ≠ completion; wal_autocheckpoint is a threshold not a guarantee; S7 gives a ready Given/When/Then starvation drill (hold reader → 10k writes → release reader → assert checkpoint resumes and WAL converges).\n- **O15 (S8):** failure-code matrix (BUSY/FULL/PROTOCOL/READONLY/IOERR/CORRUPT) — mechanism-level credible, numbers unattributed; quarantined for ADVERSARIAL.\n- **O16/O19 (S9, S5):** the \"10x\" claim is unsubstantiated; both secondary sources wrongly say auto-checkpoint runs on a reader connection — refuted in favor of S1, flagged so ADVERSARIAL doesn't inherit it.\n\n**Key limitations:** S1–S3 carried forward from prior session's verified extraction (not re-fetched); S8 anonymous/unverified; only claims-level reading of S3/S4 repos; ~10 low-priority discovery URLs deliberately not read; no measurements run (reading stage).\n\n**Mapping to repo (I1–I5):** per-call fresh connections in warm_router/curator → O14's re-apply-PRAGMA-per-connection requirement + sqlite-vec load cost as the benchmarkable overhead (O17); auto_tasks/multi-process writers → O5 data-race precondition and O9 scenario; rune_tui error sniffing → residual SQLITE_BUSY surfacing.\n\n```\nStageCompleted: OUTWARD_READING\n```","time":{"start":1788905249375,"end":1788905262922}}}
|
||||
{"type":"step_finish","timestamp":1788905262949,"sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","part":{"id":"prt_g001a083100f4c001dWfPfnUBP","reason":"stop","snapshot":"9dbbc164bf085fce5a0b86a4101243540d64fc60","messageID":"msg_g001a0830fb519001EiA8yDTTE","sessionID":"ses_-ffe5f7cf348c4ffeSAHmubYWN","type":"step-finish","tokens":{"total":70423,"input":5174,"output":865,"reasoning":0,"cache":{"write":0,"read":64384}},"cost":0}}
|
||||
@@ -0,0 +1,272 @@
|
||||
{
|
||||
"issue": 262,
|
||||
"round": 1,
|
||||
"current_stage": "ADVERSARIAL",
|
||||
"completed_stages": [
|
||||
"DEFINE",
|
||||
"INWARD",
|
||||
"OUTWARD_DISCOVERY",
|
||||
"OUTWARD_READING"
|
||||
],
|
||||
"artifacts": {
|
||||
"DEFINE": {
|
||||
"contract": {
|
||||
"issue": 262,
|
||||
"title": "OUTWARD_DISCOVERY acceptance: sqlite WAL performance in concurrent Python applications",
|
||||
"question_type": "repo-specific",
|
||||
"sub_questions": [
|
||||
"Acceptance test for the OUTWARD_DISCOVERY stage. Research question: what are the known performance characteristics of SQLite WAL mode under concurrent write workloads in Python applications?"
|
||||
],
|
||||
"required_stages": [
|
||||
"DEFINE",
|
||||
"INWARD",
|
||||
"SYNTHESIS",
|
||||
"QUALIFY"
|
||||
],
|
||||
"skipped_stages": {
|
||||
"ADVERSARIAL": "No design choice requiring adversarial evaluation.",
|
||||
"INNOVATION": "No design choice required; the issue defines the work.",
|
||||
"OUTWARD_DISCOVERY": "No external factual uncertainty identified in the issue.",
|
||||
"OUTWARD_READING": "No external factual uncertainty identified in the issue."
|
||||
},
|
||||
"evidence_classes": [
|
||||
"repo"
|
||||
],
|
||||
"sufficient_evidence": "\u22652 code-path citations for INWARD; \u22652 unique URLs for OUTWARD (if required)",
|
||||
"expected_artifact": "synthesis.json",
|
||||
"needs_mimo": false,
|
||||
"source": "deterministic"
|
||||
},
|
||||
"deterministic": true
|
||||
},
|
||||
"INWARD": {
|
||||
"context": {
|
||||
"keywords": [
|
||||
"outward_discovery",
|
||||
"acceptance",
|
||||
"sqlite",
|
||||
"wal",
|
||||
"performance",
|
||||
"concurrent",
|
||||
"python",
|
||||
"applications",
|
||||
"acceptance",
|
||||
"test",
|
||||
"outward_discovery",
|
||||
"stage",
|
||||
"research",
|
||||
"question",
|
||||
"known",
|
||||
"performance",
|
||||
"characteristics",
|
||||
"sqlite",
|
||||
"wal",
|
||||
"mode"
|
||||
],
|
||||
"umbrella_matches": [
|
||||
{
|
||||
"umbrella": "inference",
|
||||
"module": "model_routing",
|
||||
"keyword": "mode"
|
||||
},
|
||||
{
|
||||
"umbrella": "inference",
|
||||
"module": "model_profiles",
|
||||
"keyword": "mode"
|
||||
},
|
||||
{
|
||||
"umbrella": "inference",
|
||||
"module": "model_registry",
|
||||
"keyword": "mode"
|
||||
},
|
||||
{
|
||||
"umbrella": "inference",
|
||||
"module": "model_connect",
|
||||
"keyword": "mode"
|
||||
},
|
||||
{
|
||||
"umbrella": "orchestration",
|
||||
"module": "night_mode",
|
||||
"keyword": "mode"
|
||||
},
|
||||
{
|
||||
"umbrella": "orchestration",
|
||||
"module": "build_mode",
|
||||
"keyword": "mode"
|
||||
}
|
||||
],
|
||||
"candidate_files": [
|
||||
"src/rune/rune_tui.py",
|
||||
"src/rune/warm_router.py",
|
||||
"src/rune/curator.py",
|
||||
"src/rune/auto_tasks.py",
|
||||
"src/rune/memory_store.py",
|
||||
"src/rune/sleep_time.py",
|
||||
"src/rune/abstraction.py",
|
||||
"src/rune/cache.py",
|
||||
"src/rune/rune_operator.py",
|
||||
"src/rune/task_gate.py",
|
||||
"src/rune/tool_executor.py",
|
||||
"src/rune/voice_sync.py",
|
||||
"src/rune/claim_audit.py",
|
||||
"src/rune/complexity_scorer.py",
|
||||
"src/rune/connection_pool.py"
|
||||
],
|
||||
"candidate_tests": [
|
||||
"tests/test_stage_trigger_boundary.py",
|
||||
"tests/test_research_router.py",
|
||||
"tests/test_pipeline_integration.py",
|
||||
"tests/test_research_define.py",
|
||||
"tests/test_research_task_tree.py",
|
||||
"tests/test_p1_03_memory_selection.py",
|
||||
"tests/test_research_artifact.py",
|
||||
"tests/test_orchestration_migration_canary.py",
|
||||
"tests/test_p0_05_acceptance.py",
|
||||
"tests/test_p0_07_inference_trace.py"
|
||||
],
|
||||
"define_contract": {
|
||||
"issue": 262,
|
||||
"title": "OUTWARD_DISCOVERY acceptance: sqlite WAL performance in concurrent Python applications",
|
||||
"question_type": "repo-specific",
|
||||
"sub_questions": [
|
||||
"Acceptance test for the OUTWARD_DISCOVERY stage. Research question: what are the known performance characteristics of SQLite WAL mode under concurrent write workloads in Python applications?"
|
||||
],
|
||||
"required_stages": [
|
||||
"DEFINE",
|
||||
"INWARD",
|
||||
"SYNTHESIS",
|
||||
"QUALIFY"
|
||||
],
|
||||
"skipped_stages": {
|
||||
"ADVERSARIAL": "No design choice requiring adversarial evaluation.",
|
||||
"INNOVATION": "No design choice required; the issue defines the work.",
|
||||
"OUTWARD_DISCOVERY": "No external factual uncertainty identified in the issue.",
|
||||
"OUTWARD_READING": "No external factual uncertainty identified in the issue."
|
||||
},
|
||||
"evidence_classes": [
|
||||
"repo"
|
||||
],
|
||||
"sufficient_evidence": "\u22652 code-path citations for INWARD; \u22652 unique URLs for OUTWARD (if required)",
|
||||
"expected_artifact": "synthesis.json",
|
||||
"needs_mimo": false,
|
||||
"source": "deterministic"
|
||||
},
|
||||
"mimo_needed": false
|
||||
},
|
||||
"deterministic": true,
|
||||
"claims": [
|
||||
{
|
||||
"id": "I1",
|
||||
"claim": "Relevant file: src/rune/rune_tui.py",
|
||||
"evidence": [
|
||||
"src/rune/rune_tui.py"
|
||||
],
|
||||
"status": "CURRENT"
|
||||
},
|
||||
{
|
||||
"id": "I2",
|
||||
"claim": "Relevant file: src/rune/warm_router.py",
|
||||
"evidence": [
|
||||
"src/rune/warm_router.py"
|
||||
],
|
||||
"status": "CURRENT"
|
||||
},
|
||||
{
|
||||
"id": "I3",
|
||||
"claim": "Relevant file: src/rune/curator.py",
|
||||
"evidence": [
|
||||
"src/rune/curator.py"
|
||||
],
|
||||
"status": "CURRENT"
|
||||
},
|
||||
{
|
||||
"id": "I4",
|
||||
"claim": "Relevant file: src/rune/auto_tasks.py",
|
||||
"evidence": [
|
||||
"src/rune/auto_tasks.py"
|
||||
],
|
||||
"status": "CURRENT"
|
||||
},
|
||||
{
|
||||
"id": "I5",
|
||||
"claim": "Relevant file: src/rune/memory_store.py",
|
||||
"evidence": [
|
||||
"src/rune/memory_store.py"
|
||||
],
|
||||
"status": "CURRENT"
|
||||
}
|
||||
]
|
||||
},
|
||||
"OUTWARD_DISCOVERY": {
|
||||
"text": "I'll start by searching for a matching skill (required for first query), then ground the queries in the repo's SQLite usage before discovering external prior art.\n\nNo exact skill match (firecrawl-search is a partial hit \u2014 useful for the actual web searching). This is a stage in an orchestrated research process, so I'll proceed stage-wise: first ground the queries in the repo's actual SQLite usage, then discover external prior-art URLs.\n\nGrounding established: the repo opens many short-lived `sqlite3.connect` calls per process (warm_router, curator, sleep_time, self_improve\u2026), some `mode=ro`, some RW, with `PRAGMA journal_mode=WAL` in task_gate.py \u2014 a classic multi-process concurrent SQLite setup. Now I'll discover external prior art via web searches (titles/snippets only \u2014 no full-source reading).\n\nStrong first batch \u2014 official SQLite WAL docs, checkpoint-starvation prior art, and a pytest concurrent-writes test suite repo. Now covering the Python-specific and engineering-blog dimensions.\n\nExcellent coverage \u2014 the aiosqlite#382 issue (WAL fails at high concurrency) and the joedougherty pytest concurrent-writes suite are directly relevant prior art. One final batch: framework-level documentation (Django/SQLAlchemy) which the repo's stack could adopt patterns from.\n\nDiscovery is complete \u2014 10 search queries executed, ~25 distinct URLs found across official docs, GitHub issues/repos, Q&A, and engineering blogs. Composing the stage artifact.\n\n---\n\n# OUTWARD_DISCOVERY Artifact \u2014 Issue 262, Round 1\n\n**Contract**: Acceptance test for SQLite WAL performance in concurrent Python applications (repo-specific; rune's memory subsystem: `memory_store.py`, `warm_router.py`, `curator.py`, `auto_tasks.py`, `task_gate.py` \u2014 many short-lived `sqlite3.connect` calls, mixed `mode=ro`/RW connections across multiple processes, WAL enabled in `task_gate.py`, FTS5 + sqlite-vec).\n\n## 1. Search strategies\n\n| ID | Strategy | Queries | Targets |\n|----|----------|---------|---------|\n| S1 | Official WAL semantics | `sqlite wal mode performance benchmark concurrent readers single writer`; `sqlite pragma busy_timeout synchronous NORMAL WAL documentation` | sqlite.org docs; grounding for test assertions |\n| S2 | Python binding behavior | `python sqlite3 documentation timeout parameter check_same_thread threads`; `python multiprocessing sqlite WAL same database best practices` | stdlib docs, threads-vs-processes semantics |\n| S3 | Acceptance/perf test prior art | `pytest benchmark sqlite wal concurrency acceptance test python`; `aiosqlite concurrent writers WAL github issue` | test suites, benchmark tooling, known failure thresholds |\n| S4 | Failure modes | `sqlite wal checkpoint starvation stall production issues`; `sqlite WAL concurrency \"database is locked\" busy_timeout` | reproducible failure scenarios to assert against |\n| S5 | Framework precedent | `django documentation sqlite concurrency database is locked timeout`; `sqlalchemy pysqlite BEGIN IMMEDIATE` (no-hit \u2192 known-stable URL used) | documented defaults worth mirroring in the acceptance test |\n\n## 2. Discovered sources (classified)\n\n### official_docs (highest read priority)\n- **S1** https://sqlite.org/wal.html \u2014 WAL semantics: readers/writers concurrency, checkpointing, synchronous=NORMAL trade-offs, known multi-connection race bug. *Ground truth for what the acceptance test may assert.*\n- **S2** https://sqlite.org/pragma.html \u2014 `busy_timeout`, `journal_mode`, `synchronous` definitions (Python's `timeout` param maps to busy_timeout).\n- **S3** https://sqlite.org/c3ref/wal_checkpoint_v2.html \u2014 PASSIVE/FULL/RESTART/TRUNCATE checkpoint modes; blocking semantics.\n- **S4** https://docs.python.org/3/library/sqlite3.html \u2014 `timeout` param, `check_same_thread`, transaction control.\n- **S5** https://docs.sqlalchemy.org/en/20/dialects/sqlite.html \u2014 *(identified as known-stable official URL; query returned no hit)* \u2014 pysqlite serializable isolation / BEGIN IMMEDIATE / WAL guidance.\n\n### github_issue / github_repo (direct prior art)\n- **S6** https://github.com/omnilib/aiosqlite/issues/382 \u2014 \"Enabling WAL at scale increases failures and timeouts\": WAL fine below ~75 concurrent conns, degrades at 100. **Quantified failure threshold \u2014 key prior art for acceptance thresholds.**\n- **S7** https://github.com/joedougherty/sqlite3_concurrent_writes_test_suite \u2014 pytest + multiprocessing suite measuring max concurrent 1-record inserts before `database is locked`. **Closest structural template for the repo's acceptance test.**\n- **S8** https://github.com/anze3db/django-sqlite-dblock \u2014 repro repo: configure SQLite for multi-worker concurrency (Django context).\n- **S9** https://github.com/necat101/sqlite-deployment-safety-lab \u2014 reproduces WAL production issues: concurrent writers, checkpoint starvation, backup safety.\n\n### engineering_blog /Line truncated
|
||||
"tool_calls": 13,
|
||||
"event_counts": {
|
||||
"queries": 10,
|
||||
"sources_discovered": 0,
|
||||
"sources_read": 0,
|
||||
"evidence_accepted": 0,
|
||||
"tool_failures": 0,
|
||||
"tool_calls": 13
|
||||
},
|
||||
"elapsed": 471.078937292099
|
||||
},
|
||||
"OUTWARD_READING": {
|
||||
"text": "I'll start by searching for a matching skill, then locate the prior stage artifacts (especially the OUTWARD_DISCOVERY source list I need to read).\n\nNo exact skill match \u2014 this is a stage in a custom research pipeline, so I'll proceed directly. Memory shows a prior session completed OUTWARD_DISCOVERY for this issue; let me recover its source inventory.\n\nI've recovered the full state. Prior sessions already read S1\u2013S3; my job now is to read the remaining priority sources and compose the stage artifact. Fetching the next batch in parallel:\n\nGood progress \u2014 four more sources read. Fetching the remaining priority sources (productionhardening.org credibility check, the \"10x\" dev.to post, pytest-benchmark docs, Stack Overflow Q&A):\n\nStage artifact written to `/mnt/workdrive/research-stage/research/issue-262/outward_reading.json`. Summary of the extraction:\n\n## OUTWARD_READING artifact \u2014 research-262-r1 (issue 262)\n\n**Sources read (11, IDs S1\u2013S11):** sqlite.org/wal.html (S1) and wal_checkpoint_v2.html (S2) + joedougherty test suite (S3) carried from the prior partially-completed reading session; this session read S4 sqlite-deployment-safety-lab (HN #47637353 repro lab), S5 sqliteforum.com checkpoint guide, S6 WAL checkpoint-starvation diagnostic runbook, S7 dev.to one-forgotten-reader repro, S8 productionhardening.org (credibility unverified \u2014 anonymous site), S9 dev.to \"10x\" post (low authority, contains a factual error), S10 pytest-benchmark docs/PyPI, S11 Stack Overflow 393554 (via Stack Exchange API after 403 on direct fetch).\n\n**Claims extracted (19, O1\u2013O19), highlights:**\n- **O1/O4 (S1, authoritative):** WAL = readers don't block writers, but only ONE writer at a time; SQLITE_BUSY still possible in WAL; WAL mode is persistent across connections; same-host only. \u2192 The acceptance test must not assert WAL raises multi-writer throughput.\n- **O2/O3 (S1):** reader \"end marks\" \u2192 long read txn starves checkpoints \u2192 unbounded WAL growth; read perf degrades with WAL size; auto-checkpoint (1000 pages) runs on the **committing** thread \u2192 tail-latency spikes. Measurable acceptance signals.\n- **O6 (S2):** `PRAGMA wal_checkpoint(PASSIVE)` returns the (busy, log, checkpointed) tuple \u2014 the non-blocking observation primitive for the test.\n- **O7/O8 (S3):** closest prior-art harness (pytest + multiprocessing, lock-error detection, ~500-writer ceiling); author's own finding that WAL didn't raise the concurrent-write ceiling.\n- **O9/O10 (S4):** incident-grounded failure modes (overlapping multi-process writers, SIGTERM mid-transaction, unhandled SQLITE_BUSY) + validated repro experiments.\n- **O11\u2013O13 (S5\u2013S7):** PASSIVE busy=0 \u2260 completion; wal_autocheckpoint is a threshold not a guarantee; S7 gives a ready Given/When/Then starvation drill (hold reader \u2192 10k writes \u2192 release reader \u2192 assert checkpoint resumes and WAL converges).\n- **O15 (S8):** failure-code matrix (BUSY/FULL/PROTOCOL/READONLY/IOERR/CORRUPT) \u2014 mechanism-level credible, numbers unattributed; quarantined for ADVERSARIAL.\n- **O16/O19 (S9, S5):** the \"10x\" claim is unsubstantiated; both secondary sources wrongly say auto-checkpoint runs on a reader connection \u2014 refuted in favor of S1, flagged so ADVERSARIAL doesn't inherit it.\n\n**Key limitations:** S1\u2013S3 carried forward from prior session's verified extraction (not re-fetched); S8 anonymous/unverified; only claims-level reading of S3/S4 repos; ~10 low-priority discovery URLs deliberately not read; no measurements run (reading stage).\n\n**Mapping to repo (I1\u2013I5):** per-call fresh connections in warm_router/curator \u2192 O14's re-apply-PRAGMA-per-connection requirement + sqlite-vec load cost as the benchmarkable overhead (O17); auto_tasks/multi-process writers \u2192 O5 data-race precondition and O9 scenario; rune_tui error sniffing \u2192 residual SQLITE_BUSY surfacing.\n\n```\nStageCompleted: OUTWARD_READING\n```",
|
||||
"tool_calls": 16,
|
||||
"event_counts": {
|
||||
"queries": 0,
|
||||
"sources_discovered": 0,
|
||||
"sources_read": 9,
|
||||
"evidence_accepted": 0,
|
||||
"tool_failures": 1,
|
||||
"tool_calls": 16
|
||||
},
|
||||
"elapsed": 346.0588722229004
|
||||
}
|
||||
},
|
||||
"blocking_unknowns": [],
|
||||
"status": "ACTIVE",
|
||||
"stage_history": [
|
||||
{
|
||||
"stage": "DEFINE",
|
||||
"round": 1,
|
||||
"completed_at": "auto",
|
||||
"artifact_keys": [
|
||||
"contract",
|
||||
"deterministic"
|
||||
]
|
||||
},
|
||||
{
|
||||
"stage": "INWARD",
|
||||
"round": 1,
|
||||
"completed_at": "auto",
|
||||
"artifact_keys": [
|
||||
"context",
|
||||
"deterministic",
|
||||
"claims"
|
||||
]
|
||||
},
|
||||
{
|
||||
"stage": "OUTWARD_DISCOVERY",
|
||||
"round": 1,
|
||||
"completed_at": "auto",
|
||||
"artifact_keys": [
|
||||
"text",
|
||||
"tool_calls",
|
||||
"event_counts",
|
||||
"elapsed"
|
||||
]
|
||||
},
|
||||
{
|
||||
"stage": "OUTWARD_READING",
|
||||
"round": 1,
|
||||
"completed_at": "auto",
|
||||
"artifact_keys": [
|
||||
"text",
|
||||
"tool_calls",
|
||||
"event_counts",
|
||||
"elapsed"
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -102,10 +102,8 @@ class StageExecutor:
|
||||
return self._execute_define(event)
|
||||
elif stage == "INWARD":
|
||||
return self._execute_inward(event)
|
||||
elif stage == "OUTWARD_DISCOVERY":
|
||||
return self._execute_outward_discovery(event)
|
||||
elif stage == "OUTWARD_READING":
|
||||
return self._execute_not_implemented(stage)
|
||||
elif stage == "OUTWARD":
|
||||
return self._execute_outward(event)
|
||||
else:
|
||||
return self._execute_not_implemented(stage)
|
||||
|
||||
@@ -199,8 +197,8 @@ class StageExecutor:
|
||||
"artifact": artifact,
|
||||
}
|
||||
|
||||
def _execute_outward_discovery(self, event: dict) -> dict:
|
||||
"""OUTWARD_DISCOVERY: discover and classify external sources."""
|
||||
def _execute_outward(self, event: dict) -> dict:
|
||||
"""OUTWARD: one coherent MiMo external-research pass (discovery + reading + evidence extraction)."""
|
||||
import re as _re
|
||||
|
||||
define_artifact = self.tree.state["artifacts"].get("DEFINE", {})
|
||||
@@ -216,7 +214,7 @@ class StageExecutor:
|
||||
strategy = route(" ".join(all_q[:3]) if all_q else question)
|
||||
|
||||
pp = [
|
||||
"STAGE: OUTWARD_DISCOVERY",
|
||||
"STAGE: OUTWARD",
|
||||
"ISSUE: #" + str(self.issue),
|
||||
"RESEARCH QUESTION: " + question,
|
||||
]
|
||||
@@ -235,13 +233,16 @@ class StageExecutor:
|
||||
pp.append("- Preserve query/tool receipts")
|
||||
pp.append("- Identify candidate sources with stable IDs (O1, O2, ...)")
|
||||
pp.append("- Classify each source")
|
||||
pp.append("- Select sources for OUTWARD_READING with relevance rationale")
|
||||
pp.append("- Select sources for reading and actually read them")
|
||||
pp.append("- Extract evidence claims relevant to the subquestions")
|
||||
pp.append("- Record limitations and contradictions")
|
||||
pp.append("- Preserve source IDs and fetch/read receipts")
|
||||
pp.append("")
|
||||
pp.append("DO NOT:")
|
||||
pp.append("- Deeply synthesize the sources")
|
||||
pp.append("- Design the Rune solution")
|
||||
pp.append("- Modify code")
|
||||
pp.append("- Continue into OUTWARD_READING")
|
||||
pp.append("- Continue into further research after the evidence requirement is satisfied")
|
||||
pp.append("- Claim search/source activity that did not occur")
|
||||
|
||||
prompt = chr(10).join(pp)
|
||||
@@ -249,8 +250,8 @@ class StageExecutor:
|
||||
mimo_bin = os.environ.get("MIMO_BIN", "/var/lib/gitea-desktop-runner/bin/mimo")
|
||||
mimo_model = os.environ.get("MIMO_MODEL", "Verboo Code/glm-5.3-flash")
|
||||
mimo_agent = os.environ.get("MIMO_AGENT", "build")
|
||||
events_path = os.path.join(self.artifact_dir, "stage_OUTWARD_DISCOVERY.events.jsonl")
|
||||
err_path = os.path.join(self.artifact_dir, "stage_OUTWARD_DISCOVERY.mimo.err.log")
|
||||
events_path = os.path.join(self.artifact_dir, "stage_OUTWARD.events.jsonl")
|
||||
err_path = os.path.join(self.artifact_dir, "stage_OUTWARD.mimo.err.log")
|
||||
os.makedirs(self.artifact_dir, exist_ok=True)
|
||||
|
||||
cmd = [mimo_bin, "run", "--agent", mimo_agent, "-m", mimo_model,
|
||||
@@ -262,7 +263,7 @@ class StageExecutor:
|
||||
|
||||
if relay_result["returncode"] != 0:
|
||||
self.tree.fail("mimo exited " + str(relay_result["returncode"]))
|
||||
return {"status": "STAGE_FAILED", "stage": "OUTWARD_DISCOVERY",
|
||||
return {"status": "STAGE_FAILED", "stage": "OUTWARD",
|
||||
"error": "mimo exited " + str(relay_result["returncode"])}
|
||||
|
||||
if not relay_result["texts"]:
|
||||
@@ -271,7 +272,7 @@ class StageExecutor:
|
||||
with open(err_path) as f:
|
||||
error_detail = f.read()[-300:]
|
||||
self.tree.fail("no text output. stderr: " + error_detail)
|
||||
return {"status": "STAGE_FAILED", "stage": "OUTWARD_DISCOVERY",
|
||||
return {"status": "STAGE_FAILED", "stage": "OUTWARD",
|
||||
"error": "no text output", "stderr": error_detail}
|
||||
|
||||
artifact_text = "\n\n".join(relay_result["texts"])
|
||||
@@ -293,32 +294,40 @@ class StageExecutor:
|
||||
|
||||
queries = [{"id": "Q1", "query": question, "tool_receipt": "mimo webfetch"}]
|
||||
|
||||
# Split sources into discovered vs selected (both inside one artifact)
|
||||
selected = [s for s in sources if s.get("selected_for_reading")]
|
||||
|
||||
artifact = {
|
||||
"stage": "OUTWARD_DISCOVERY",
|
||||
"stage": "OUTWARD",
|
||||
"issue": self.issue,
|
||||
"round": self.round_no,
|
||||
"attempt": event.get("attempt", 1),
|
||||
"queries": queries,
|
||||
"sources": sources,
|
||||
"discovery": {
|
||||
"queries": queries,
|
||||
"sources_discovered": sources,
|
||||
"source_count": len(sources),
|
||||
},
|
||||
"reading": {
|
||||
"sources_selected": selected,
|
||||
"sources_read": [s["id"] for s in selected],
|
||||
"evidence_extracted": len(artifact_text),
|
||||
},
|
||||
"coverage": {
|
||||
"required_classes": evidence_classes,
|
||||
"represented_classes": ["web"] if urls else [],
|
||||
"uncovered": [c for c in evidence_classes if c != "web"] if urls else evidence_classes,
|
||||
},
|
||||
"next_stage_input": {
|
||||
"selected_source_ids": [s["id"] for s in sources if s.get("selected_for_reading")],
|
||||
},
|
||||
"text": artifact_text,
|
||||
"event_counts": relay_result["event_counts"],
|
||||
"elapsed": relay_result["elapsed"],
|
||||
}
|
||||
|
||||
gate_errors = self._validate_outward_discovery(artifact)
|
||||
gate_errors = self._validate_outward(artifact)
|
||||
if gate_errors:
|
||||
self.tree.fail("; ".join(gate_errors))
|
||||
attempt = event.get("attempt", 1)
|
||||
status = "GATE_FAILED" if attempt >= 2 else "GATE_RETRY"
|
||||
return {"status": status, "stage": "OUTWARD_DISCOVERY",
|
||||
return {"status": status, "stage": "OUTWARD",
|
||||
"errors": gate_errors, "artifact_hash": artifact_hash(artifact)}
|
||||
|
||||
artifact_digest = artifact_hash(artifact)
|
||||
@@ -332,20 +341,20 @@ class StageExecutor:
|
||||
print(" Hash: " + artifact_digest)
|
||||
print(" Next: " + next_stage)
|
||||
|
||||
return {"status": "STAGE_COMPLETED", "stage": "OUTWARD_DISCOVERY",
|
||||
return {"status": "STAGE_COMPLETED", "stage": "OUTWARD",
|
||||
"artifact_hash": artifact_digest, "next_stage": next_stage, "artifact": artifact}
|
||||
|
||||
def _validate_outward_discovery(self, artifact: dict) -> list:
|
||||
def _validate_outward(self, artifact: dict) -> list:
|
||||
errors = []
|
||||
sources = artifact.get("sources", [])
|
||||
queries = artifact.get("queries", [])
|
||||
if not queries:
|
||||
errors.append("OUTWARD_DISCOVERY: no query receipts")
|
||||
errors.append("OUTWARD: no query receipts")
|
||||
if len(sources) < 2:
|
||||
errors.append("OUTWARD_DISCOVERY: " + str(len(sources)) + " sources < 2")
|
||||
errors.append("OUTWARD: " + str(len(sources)) + " sources < 2")
|
||||
source_ids = [s.get("id") for s in sources]
|
||||
if len(source_ids) != len(set(source_ids)):
|
||||
errors.append("OUTWARD_DISCOVERY: duplicate source IDs")
|
||||
errors.append("OUTWARD: duplicate source IDs")
|
||||
for src in sources:
|
||||
if not src.get("url", "").startswith("http"):
|
||||
errors.append("OUTWARD_DISCOVERY source " + src.get("id", "?") + ": invalid URL")
|
||||
@@ -354,7 +363,7 @@ class StageExecutor:
|
||||
represented = coverage.get("represented_classes", [])
|
||||
uncovered = [c for c in required if c not in represented]
|
||||
if uncovered and not coverage.get("uncovered"):
|
||||
errors.append("OUTWARD_DISCOVERY: classes not represented: " + str(uncovered))
|
||||
errors.append("OUTWARD: classes not represented: " + str(uncovered))
|
||||
return errors
|
||||
|
||||
|
||||
|
||||
@@ -28,15 +28,14 @@ from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
STAGES = [
|
||||
"DEFINE", "INWARD", "OUTWARD_DISCOVERY", "OUTWARD_READING",
|
||||
"DEFINE", "INWARD", "OUTWARD",
|
||||
"ADVERSARIAL", "INNOVATION", "SYNTHESIS", "QUALIFY",
|
||||
]
|
||||
|
||||
STAGE_ARTIFACT_FILES = {
|
||||
"DEFINE": "define.json",
|
||||
"INWARD": "inward.json",
|
||||
"OUTWARD_DISCOVERY": "outward_discovery.json",
|
||||
"OUTWARD_READING": "outward_reading.json",
|
||||
"OUTWARD": "outward.json",
|
||||
"ADVERSARIAL": "adversarial.json",
|
||||
"INNOVATION": "innovation.json",
|
||||
"SYNTHESIS": "synthesis.json",
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
{"success":true,"data":{"web":[{"url":"https://stackoverflow.com/questions/46023203/sqlite-3-wal-mode-multiple-processes-frequently-corrupting-database","title":"SQLite 3 WAL mode multiple processes frequently corrupting ...","description":"This seems to mostly occur if a process crashed after having opened a connection ・ it has something to do with the -shm and -wal index files ...Is it safe to delete sqlite's WAL file? - Stack OverflowSQLITE db files not closed. db-shm and db-wal files remainMore results from stackoverflow.com","position":1},{"url":"https://www.sqlite.org/wal.html","title":"Write-Ahead Logging - SQLite","description":"[](https://sqlite.org/index.html)\n\n# 7. Implementation Of Shared-Memory For The WAL-Index\nleading to database corruption.","position":2},{"url":"https://sqlite.org/forum/forumpost/6cd3d10b06","title":"Can -wal -shm files be deleted if -wal file is empty? - SQLite User Forum","description":"If there are processes with the db open and you delete these files, the db might become corrupted later on. should delete the *-wal and *-shm ...","position":3},{"url":"https://avi.im/blag/2025/sqlite-wal-checksum/","title":"PSA: SQLite WAL checksums fail silently and may lose data - blag","description":"SQLite WAL has checksums, but on corruption it drops all the data and does not raise error. A WAL may contain multiple frames for the same page ...","position":4},{"url":"https://lobste.rs/s/bi8dbr/sqlite_corrupted_wal_can_silently_lose","title":"SQLite corrupted WAL can silently lose committed entries - Lobsters","description":"A well known bug between SQLite and ZFS interactions will cause the database to randomly lock up during WAL flushes for several seconds (this ...","position":5},{"url":"https://scottspence.com/posts/sqlite-corruption-fs-copyfile-issue","title":"SQLite Corruption with fs.copyFile() in WAL Mode - Scott Spence","description":"# SQLite Corruption with fs.copyFile() in WAL Mode\n## [What happened?](https://scottspence.com/posts/sqlite-corruption-fs-copyfile-issue#what-happened)\n```undefined\n*** in database main ***\nPage 42: btreeInitPage() returns error code 11\nFreelist: 2 of 3 pages missing\n...freelist link 2 corresponds to page 134\nTree 5 page 789: index entries are not in ascending order\nRow 456 missing from index idx_posts\nRow 789 missing from index idx_tags\n...\n[80+ more rows of pain]\n```\n\n## [The recovery process](https://scottspence.com/posts/sqlite-corruption-fs-copyfile-issue#the-recovery-process)\n```bash\n# Enter the production container\ndocker exec -it your-container-name sh\n\n# Check database integrity\nsqlite3 /app/data/site-data.db \"PRAGMA integrity_check;\"\n# Result: extensive corruption confirmed\n```\n\n```bash\n# From WSL on local machine\n# Note: 'coolify' is my SSH config alias for the production server\nscp /home/scott/repos/scottspence.com/data/site-data.db coolify:/tmp/db-restore/\n```\n\n```bash\n# On production server\ndocker cp /tmp/db-restore/site-data.db your-container-name:/app/data/site-data.db\n\n# Remove WAL and shared memory files\ndocker exec your-container-name sh -c \"rm -f /app/data/site-data.db-wal /app/data/site-data.db-shm\"\n\n# Verify integrity\ndocker exec your-container-name sqlite3 /app/data/site-data.db \"PRAGMA integrity_check;\"\n# Result: ok\n```","position":6}]},"id":"01a08313-aa75-76b2-8744-d30debb49a2c","creditsUsed":2}
|
||||
Reference in new issue
Block a user